Reinforcement learning (RL) is used to improve the reasoning abilities of LLMs, while training data span heterogeneous tasks. However, most RL post-training pipelines rely on fixed or manually designed task mixtures, even though task usefulness changes as training progresses. Online curriculum methods often define learnability by update magnitude, ignoring whether the update translates into reward gains, which can misallocate rollout budget toward tasks with large but ineffective updates. We propose PAC, a Progress-Augmented Advantage Curriculum for multi-task RL of LLMs that combines two task-level signals: advantage-derived learnability, which measures the magnitude of the policy update a task can induce, and recent reward gains, which show whether those updates have improved task performance. A Bayesian Thompson Sampling controller uses these signals to allocate rollouts across tasks during GRPO training. We evaluate PAC under two settings: a multi-level reasoning setting and a multi-domain reasoning setting. PAC improves sample efficiency and final performance: it reaches comparable validation scores with fewer rollout steps and achieves higher final averages than random sampling and advantage-based curriculum baselines in both settings. These results show that jointly tracking advantage signals and actual reward gains yields an effective online curriculum for LLM post-training.


翻译:暂无翻译

0
下载
关闭预览

相关内容

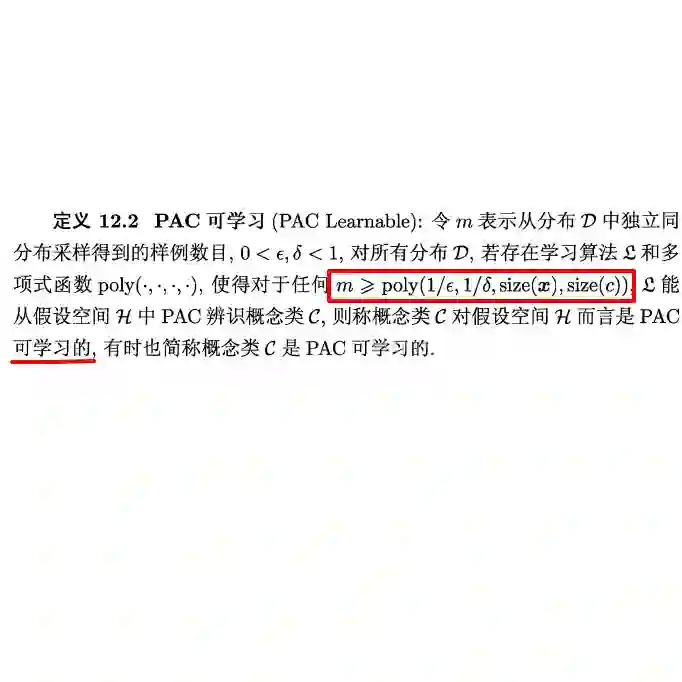
PAC学习理论不关心假设选择算法,他关心的是能否从假设空间H中学习一个好的假设h。此理论不关心怎样在假设空间中寻找好的假设,只关心能不能找得到。现在我们在来看一下什么叫“好假设”?只要满足两个条件(PAC辨识条件)即可
面向大型推理模型的强化学习综述
专知会员服务
30+阅读 · 2025年9月11日
大语言模型的强化学习技术综述
专知会员服务
42+阅读 · 2025年7月8日
专知会员服务
23+阅读 · 2021年6月26日
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
「基于通信的多智能体强化学习」 进展综述
基于模型的强化学习综述
专知
42+阅读 · 2022年7月13日
【MIT博士论文】数据高效强化学习,176页pdf
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
【强化学习】强化学习/增强学习/再励学习介绍
产业智能官
10+阅读 · 2018年2月23日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
VIP会员
最新内容
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
8+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
11+阅读 · 10月15日
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
10+阅读 · 10月14日
软件定义无人机蜂群给防空带来全新压力
专知会员服务
10+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
14+阅读 · 10月13日
相关VIP内容
面向大型推理模型的强化学习综述
专知会员服务
30+阅读 · 2025年9月11日
大语言模型的强化学习技术综述
专知会员服务
42+阅读 · 2025年7月8日
专知会员服务
23+阅读 · 2021年6月26日
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关基金
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员