

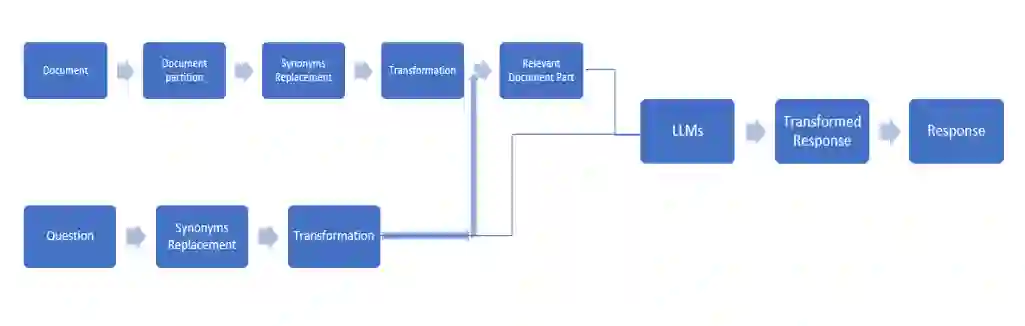
Protecting sensitive information is crucial in today's world of Large Language Models (LLMs) and data-driven services. One common method used to preserve privacy is by using data perturbation techniques to reduce overreaching utility of (sensitive) Personal Identifiable Information (PII) data while maintaining its statistical and semantic properties. Data perturbation methods often result in significant information loss, making them impractical for use. In this paper, we propose 'Life of PII', a novel Obfuscation Transformer framework for transforming PII into faux-PII while preserving the original information, intent, and context as much as possible. Our approach includes an API to interface with the given document, a configuration-based obfuscator, and a model based on the Transformer architecture, which has shown high context preservation and performance in natural language processing tasks and LLMs. Our Transformer-based approach learns mapping between the original PII and its transformed faux-PII representation, which we call "obfuscated" data. Our experiments demonstrate that our method, called Life of PII, outperforms traditional data perturbation techniques in terms of both utility preservation and privacy protection. We show that our approach can effectively reduce utility loss while preserving the original information, offering greater flexibility in the trade-off between privacy protection and data utility. Our work provides a solution for protecting PII in various real-world applications.
翻译:保护敏感信息在当今大型语言模型(LLMs)和数据驱动服务的时代至关重要。一种常用的隐私保护方法是通过数据扰动技术,在保持(敏感)个人身份信息(PII)数据的统计属性和语义属性的同时,降低其过度效用。然而,数据扰动方法常导致显著的信息损失,使其在实际应用中难以推广。本文提出一种名为"PII的生命"的新型混淆变换器框架,该框架能在最大限度保留原始信息、意图和上下文的前提下,将PII转化为伪PII。我们的方法包括一个用于与给定文档交互的API接口、一个基于配置的混淆器,以及一个基于Transformer架构的模型——该架构在自然语言处理任务和LLMs中展现出卓越的上下文保持能力与性能。基于Transformer的方法能够学习原始PII与其转化后的伪PII表示(即"混淆"数据)之间的映射关系。实验结果表明,我们提出的"PII的生命"方法在效用保持和隐私保护方面均优于传统数据扰动技术。该方法可在保留原始信息的同时有效降低效用损失,为隐私保护与数据效用之间的权衡提供更大灵活性。我们的工作为现实应用中保护PII提供了切实可行的解决方案。


相关内容


 微信扫码咨询专知VIP会员