

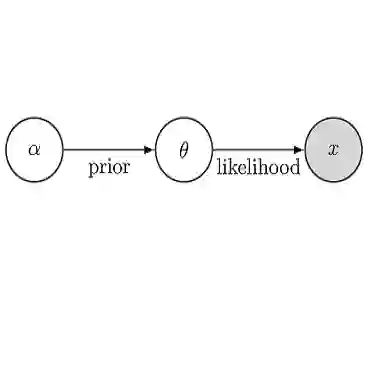
Hierarchical data is ubiquitous in the empirical sciences and most commonly analyzed with generalized linear mixed-effects models (GLMMs), which have interpretable parameters. Bayesian inference for GLMMs yields calibrated uncertainty estimates but requires Markov Chain Monte Carlo (MCMC); the gold-standard No-U-Turn Sampler (NUTS) is slow and must restart for every new dataset, model and prior specification. We introduce MetaBeta, a pretrained amortized model for in-context Bayesian inference over GLMMs. The full prior and model specification are supplied as context at test time, and the model returns an asymptotically exact posterior at the speed of a forward pass. Two set transformers and two conditional neural spline flows mirror the GLMM's hierarchical structure and are trained jointly on millions of realistic simulated datasets with continuous, binary and count outcomes. The flow posterior is refined by Independence Metropolis-Hastings against the unnormalized posterior, yielding tuning-free asymptotically correct inference. Alternatively, MetaBeta warm-starts NUTS, yielding nearly identical inference 3.5-13x faster than its cold-started counterpart, while removing over 98% of its divergent transitions. On controlled benchmarks with ground-truth parameters, MetaBeta matches NUTS in parameter recovery, posterior calibration and out-of-sample prediction; on real datasets with unknown parameters, priors and model structure, its posteriors closely agree with those of NUTS; and it remains faithful where amortized models typically struggle: under misspecified likelihoods, misspecified priors, out-of-distribution predictors, collinear designs and data-poor regimes. On real data, a full prior sensitivity analysis including model comparison takes a few seconds with MetaBeta against 14-18 core-hours for NUTS, tracing its posteriors throughout. Our model is open-source and open-weights.
翻译:暂无翻译




相关内容



 微信扫码咨询专知VIP会员