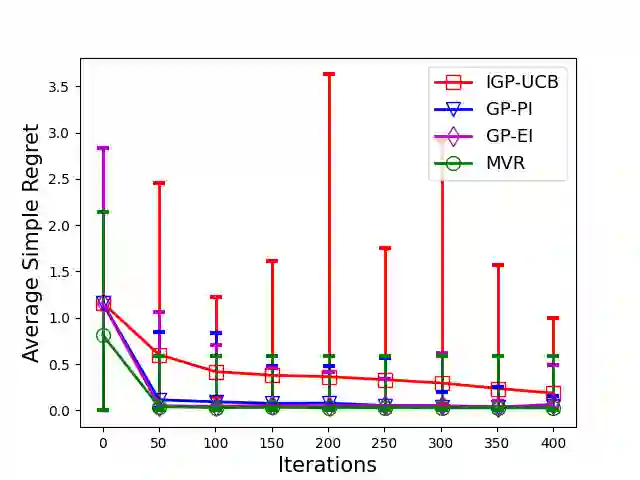
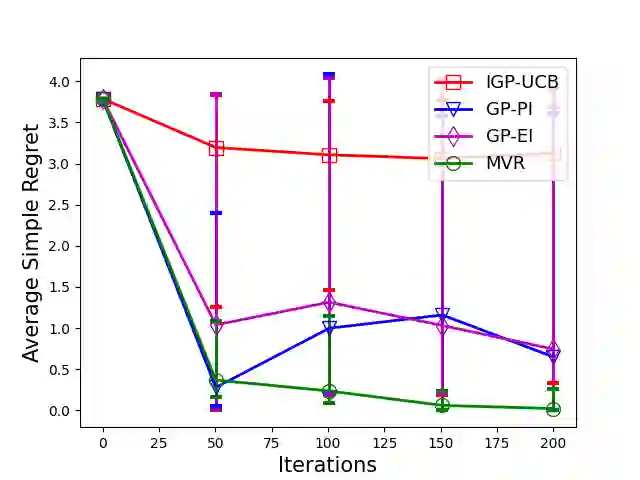
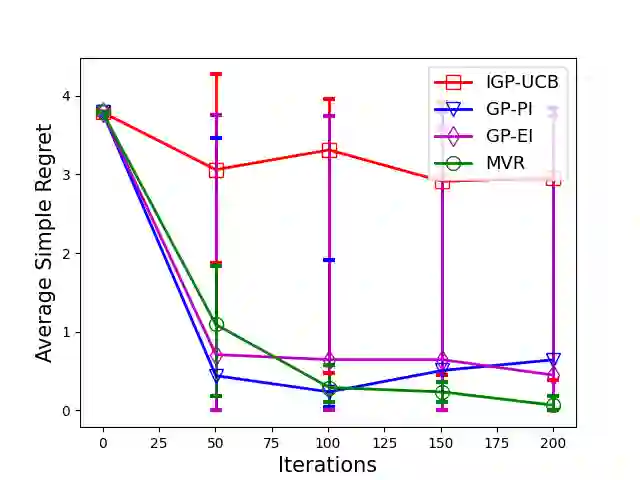
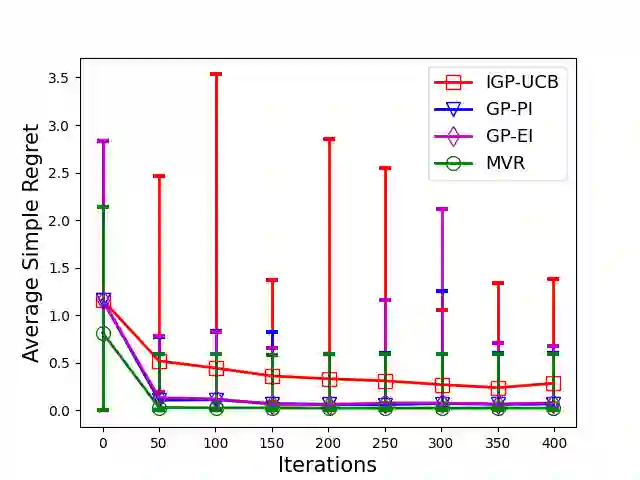
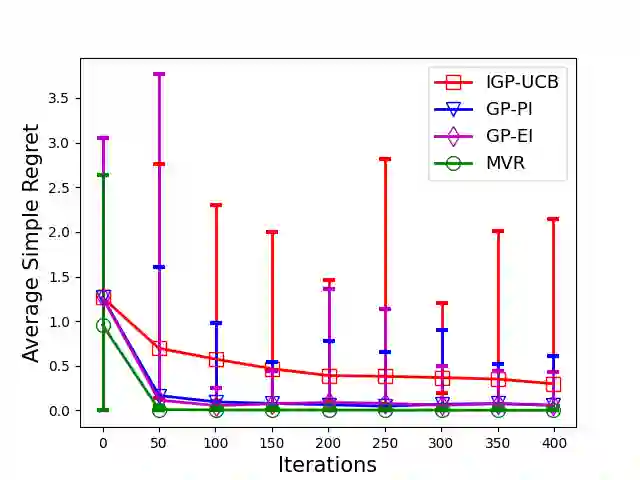
Consider the sequential optimization of a continuous, possibly non-convex, and expensive to evaluate objective function $f$. The problem can be cast as a Gaussian Process (GP) bandit where $f$ lives in a reproducing kernel Hilbert space (RKHS). The state of the art analysis of several learning algorithms shows a significant gap between the lower and upper bounds on the simple regret performance. When $N$ is the number of exploration trials and $\gamma_N$ is the maximal information gain, we prove an $\tilde{\mathcal{O}}(\sqrt{\gamma_N/N})$ bound on the simple regret performance of a pure exploration algorithm that is significantly tighter than the existing bounds. We show that this bound is order optimal up to logarithmic factors for the cases where a lower bound on regret is known. To establish these results, we prove novel and sharp confidence intervals for GP models applicable to RKHS elements which may be of broader interest.


翻译:考虑一个连续的, 可能是非convex, 并且用来评估客观功能的昂贵费用。 问题可以被描绘成一个高斯进程( GP) 土匪, $f 住在复制的Hilbert 空间( RKHS ) 。 一些学习算法的最新分析显示, 在简单的遗憾表现上, 下限和上限之间有很大差距。 当美元是勘探试验的数量, $\gamma_N$是最大的信息收益时, 我们证明, $\ tilde ~mathcal{ O{ (\\\\\\\ sqrt\ gamma_N/N} 绑在纯粹探索算法的简单遗憾表现上, 它比现有的界限要紧得多。 我们证明, 这个约束是最佳的逻辑因素, 对于已知的遗憾程度较低的案例来说, 。 为了确定这些结果, 我们证明适用于 RKHS 元素的G 模型有新颖和强烈的信任期。
0
下载
关闭预览

相关内容

专知会员服务
79+阅读 · 2021年3月16日
专知会员服务
52+阅读 · 2020年12月14日
专知会员服务
55+阅读 · 2020年9月7日
深度强化学习策略梯度教程,53页ppt
专知会员服务
184+阅读 · 2020年2月1日
专知会员服务
162+阅读 · 2020年1月16日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
LibRec 精选:AutoML for Contextual Bandits
LibRec智能推荐
7+阅读 · 2019年9月19日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
RL 真经
CreateAMind
6+阅读 · 2018年12月28日
Disentangled的假设的探讨
CreateAMind
9+阅读 · 2018年12月10日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
Auto-Encoding GAN
CreateAMind
7+阅读 · 2017年8月4日
强化学习族谱
CreateAMind
26+阅读 · 2017年8月2日
强化学习 cartpole_a3c
CreateAMind
9+阅读 · 2017年7月21日
Arxiv
0+阅读 · 2021年10月15日
Arxiv
3+阅读 · 2018年10月18日
Arxiv
3+阅读 · 2018年2月24日
Arxiv
3+阅读 · 2017年12月14日
VIP会员
最新内容
军事域更好使用人工智能的实用指南
专知会员服务
3+阅读 · 10月22日
《衡量语言模型中的作战规划能力》
专知会员服务
11+阅读 · 10月20日
Maven智能系统:帕兰提尔军事人工智能平台详解
专知会员服务
11+阅读 · 10月20日
《测试自动化框架在敏捷软件开发中的角色》
专知会员服务
8+阅读 · 10月20日
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
11+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
16+阅读 · 10月15日
现代电磁战:集成式系统簇时代如何实现频谱优势
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
12+阅读 · 10月14日
相关VIP内容
专知会员服务
79+阅读 · 2021年3月16日
专知会员服务
52+阅读 · 2020年12月14日
专知会员服务
55+阅读 · 2020年9月7日
深度强化学习策略梯度教程,53页ppt
专知会员服务
184+阅读 · 2020年2月1日
专知会员服务
162+阅读 · 2020年1月16日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
相关资讯
LibRec 精选:AutoML for Contextual Bandits
LibRec智能推荐
7+阅读 · 2019年9月19日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
RL 真经
CreateAMind
6+阅读 · 2018年12月28日
Disentangled的假设的探讨
CreateAMind
9+阅读 · 2018年12月10日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
Auto-Encoding GAN
CreateAMind
7+阅读 · 2017年8月4日
强化学习族谱
CreateAMind
26+阅读 · 2017年8月2日
强化学习 cartpole_a3c
CreateAMind
9+阅读 · 2017年7月21日
Top
微信扫码咨询专知VIP会员