

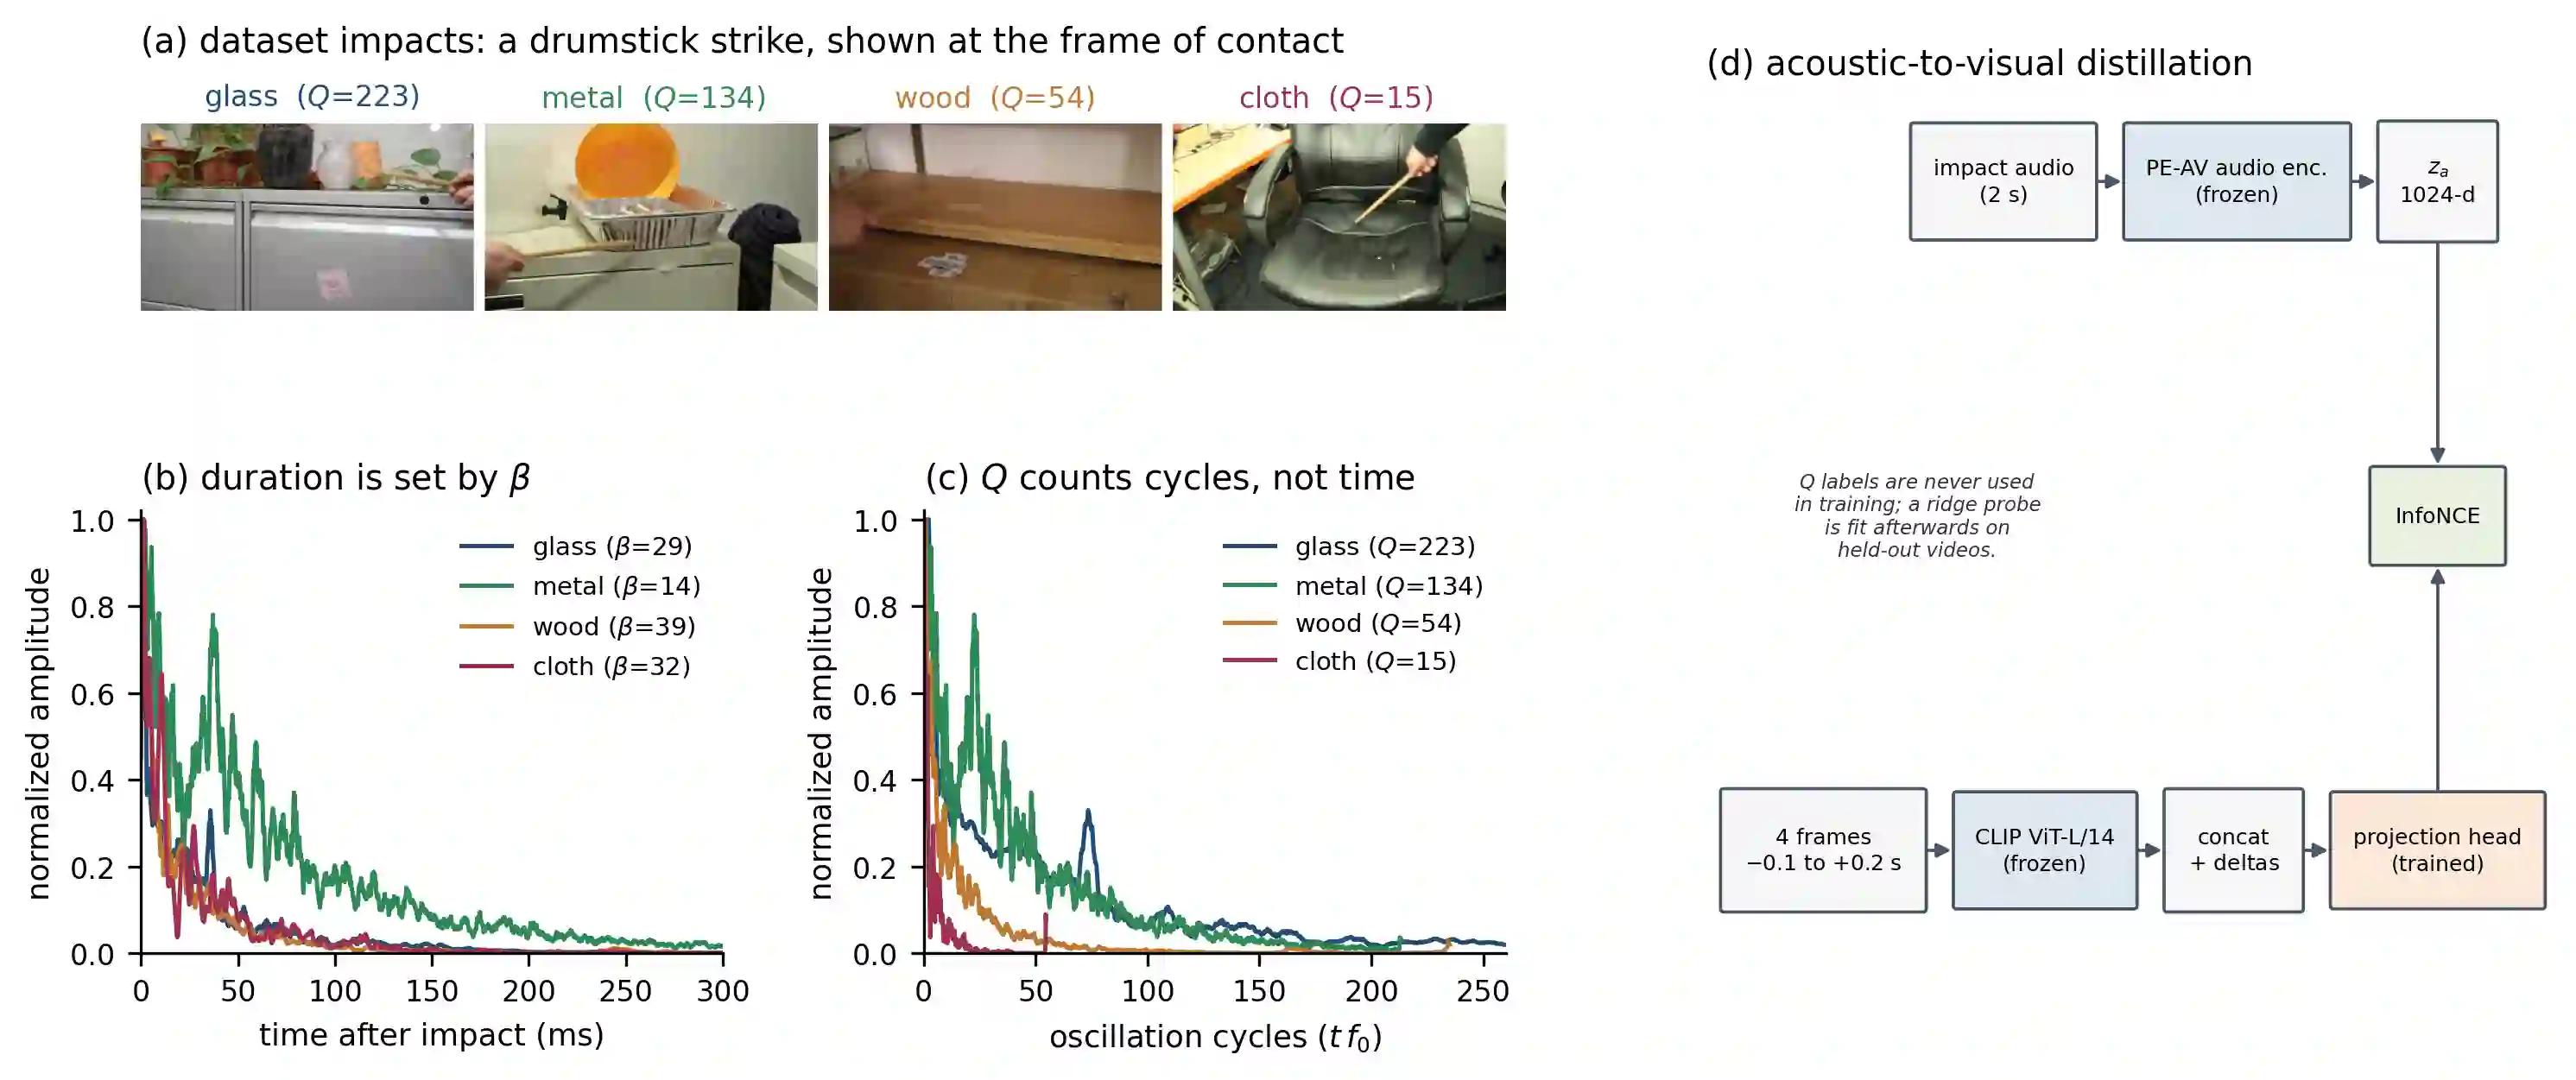
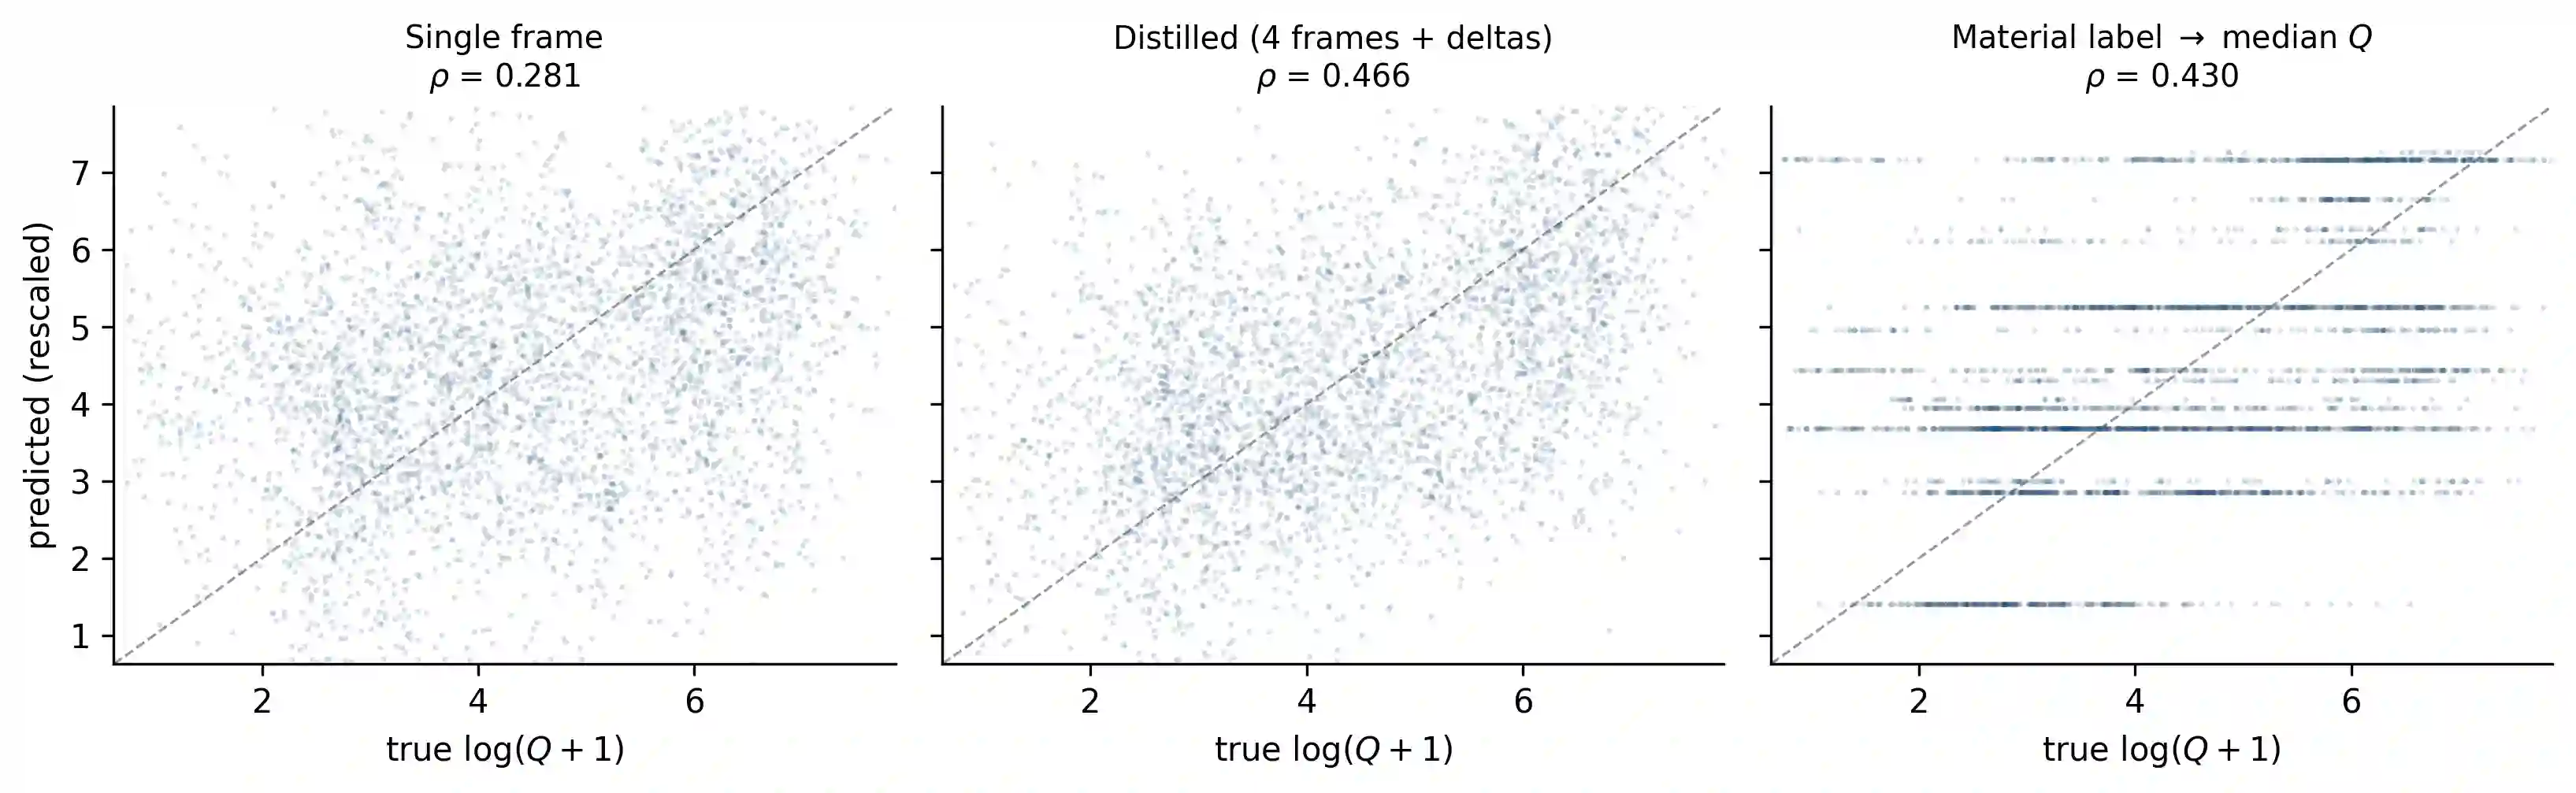
Physical understanding is crucial for decision making, yet vision models struggle to infer properties such as damping that govern how materials behave. Audio encodes such properties directly, because an object's acoustic response to impact reveals its damping through measurable decay. We probe frozen encoders for the quality factor $Q$, a dimensionless measure of how many oscillations an object completes before its ring dies away, and report how well each embedding orders impacts by $Q$ using the Spearman rank correlation $ρ$, for which $ρ=1$ is a perfect ordering and $ρ=0$ an unrelated one. Audio embeddings reach $ρ=0.73$ and retain most of that advantage on materials withheld from training, while a single video frame taken at the moment of impact, encoded by CLIP, supports only $ρ=0.28$. Having established where the signal lives, we ask how much of that gap vision can recover. We distill a frozen audio teacher into a frozen CLIP backbone through a trained projection head and find that this recovers a useful fraction of the audio advantage. Because pooled correlations on this task are dominated in practice by category identity, we also evaluate under a leave-one-material-out protocol in which the held-out material is withheld from the projection head as well as the probe. Distillation with a four-frame input improves the correlation there from 0.234 to 0.338 (+0.053 over the matched four-frame baseline, 14 of 17 materials), a gain that no category-level strategy can produce. Widening the visual input to four frames spanning the impact supplies half of that improvement at no acoustic cost, which indicates that part of what a single frame misses is visible dynamics.
翻译:暂无翻译




相关内容



 微信扫码咨询专知VIP会员