Recent advances in Large Language Models (LLMs) have led to dramatic improvements in question answering (QA). To address the challenge of evaluating QA systems, standardized benchmarks have been introduced. This work focuses on the problem of geospatial QA, where a large collection of geospatial data is available in the form of a spatial database or other forms. Existing work on geospatial QA benchmarks has various limitations, including a small number of questions, limited spatial predicates, narrow output types, and no multi-source reasoning. We present GS-QA, an extensible geospatial QA benchmark with 2,800 question-answer pairs across 28 templates on top of OpenStreetMap and Wikipedia data, covering a wide range of spatial objects, predicates (including directional and towards filtering), and answer types (entity names, locations, distances, directions, counts, and aggregated areas/lengths). A key feature of GS-QA is that some questions require combining information from multiple sources, e.g., geospatial information from OSM and factual information from Wikipedia. GS-QA includes a comprehensive evaluation methodology that combines text-based QA measures with geospatial-specific measures such as distance error and angular error. We implemented nine LLM-based geospatial QA baselines using three LLMs (GPT-4o, Claude Sonnet 4.6, and Ministral-3) with combinations of direct prompting, retrieval-augmented generation, and text-to-SQL. Our results show that existing solutions perform reasonably well on simple spatial predicates with entity name outputs, but accuracy degrades significantly for questions involving complex spatial predicates, numeric output types, and multi-source reasoning, demonstrating that geospatial QA remains a challenging open problem warranting further research.


翻译:暂无翻译

0
下载
关闭预览

相关内容

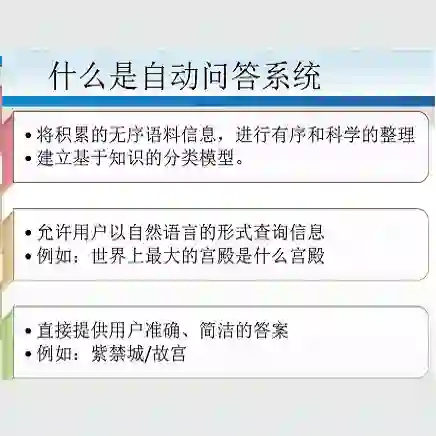
自动问答(Question Answering, QA)是指利用计算机自动回答用户所提出的问题以满足用户知识需求的任务。不同于现有搜索引擎,问答系统是信息服务的一种高级形式,系统返回用户的不再是基于关键词匹配排序的文档列表,而是精准的自然语言答案。近年来,随着人工智能的飞速发展,自动问答已经成为倍受关注且发展前景广泛的研究方向。

知识荟萃

精品入门和进阶教程、论文和代码整理等

更多

查看相关VIP内容、论文、资讯等
大语言模型中的隐式推理:综合综述
专知会员服务
34+阅读 · 2025年9月4日
大语言模型遇上知识图谱:问答系统中的融合与机遇
专知会员服务
30+阅读 · 2025年5月30日
超越语言的推理:潜在思维链推理的综合综述
专知会员服务
22+阅读 · 2025年5月23日
大型语言模型推理引擎的综述:优化与效率的视角
专知会员服务
23+阅读 · 2025年5月13日
通过逻辑推理赋能大语言模型:综述
专知会员服务
33+阅读 · 2025年2月24日
天大最新《大型语言模型评估》全面综述,111页pdf
专知会员服务
89+阅读 · 2023年10月31日
GraphSAGE: GCN落地必读论文
AI100
29+阅读 · 2019年8月15日
论文浅尝 | 问题生成(QG)与答案生成(QA)的结合
开放知识图谱
16+阅读 · 2018年7月15日
论文浅尝 | 基于知识图谱子图匹配以回答自然语言问题
开放知识图谱
26+阅读 · 2018年6月26日
论文浅尝 | Question Answering over Freebase
开放知识图谱
19+阅读 · 2018年1月9日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
VIP会员
最新内容
现代电磁战:集成式系统簇时代如何实现频谱优势
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
0+阅读 · 今天14:47
软件定义无人机蜂群给防空带来全新压力
专知会员服务
9+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
9+阅读 · 10月13日
迈向更智慧的军事情报
专知会员服务
9+阅读 · 10月12日
《美国陆军2026年野战手册 2-0 情报》
专知会员服务
8+阅读 · 10月12日
《基于启发式算法求解武器-目标分配问题》
专知会员服务
9+阅读 · 10月12日
相关VIP内容
大语言模型中的隐式推理:综合综述
专知会员服务
34+阅读 · 2025年9月4日
大语言模型遇上知识图谱:问答系统中的融合与机遇
专知会员服务
30+阅读 · 2025年5月30日
超越语言的推理:潜在思维链推理的综合综述
专知会员服务
22+阅读 · 2025年5月23日
大型语言模型推理引擎的综述:优化与效率的视角
专知会员服务
23+阅读 · 2025年5月13日
通过逻辑推理赋能大语言模型:综述
专知会员服务
33+阅读 · 2025年2月24日
天大最新《大型语言模型评估》全面综述,111页pdf
专知会员服务
89+阅读 · 2023年10月31日
相关基金
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员