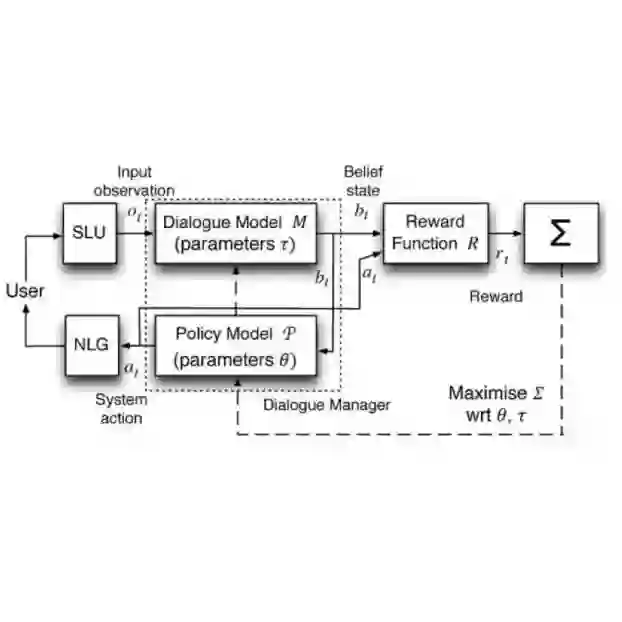
We identify a fundamental mismatch in empathetic reinforcement learning: support priorities evolve with the dialogue state, yet existing methods typically optimize predefined reward specifications that remain fixed across turns. To model these evolving support priorities, we organize empathetic support along cognitive, affective, and proactive empathy, and propose Context-Adaptive Rubric Evolution (CARE). At each turn, CARE generates a context-adaptive rubric by adjusting both the weights of these three empathy dimensions and their fine-grained evaluation criteria. The rubric generator is trained with turn-level rubric supervision and human preference data through supervised fine-tuning followed by preference-based reinforcement learning, and then serves as an adaptive reward interface for online empathetic RL. Integrated with both RLVER and MICA, CARE achieves state-of-the-art performance across SentientBench, EQBench3, and EMPA under three independent LLM judges. Notably, on EMPA, CARE improves EPM-Idx over the strongest baseline by at least 13 points under all three judges, including an increase from 28.11 to 83.54 under Gemini-2.5-Pro. Further analyses show that learned rubric priorities systematically vary across dialogue stages and user emotions, demonstrating that CARE adapts what is rewarded as support needs evolve.


翻译:暂无翻译

0
下载
关闭预览

相关内容

148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【强化学习资源集合】Awesome Reinforcement Learning
专知会员服务
99+阅读 · 2019年12月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
【深度强化学习】深度强化学习揭秘
产业智能官
21+阅读 · 2017年11月13日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Arxiv
0+阅读 · 10月1日
Relational Deep Reinforcement Learning
Arxiv
10+阅读 · 2018年6月28日
VIP会员
最新内容
软件定义无人机蜂群给防空带来全新压力
专知会员服务
4+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
5+阅读 · 10月13日
迈向更智慧的军事情报
专知会员服务
5+阅读 · 10月12日
《美国陆军2026年野战手册 2-0 情报》
专知会员服务
5+阅读 · 10月12日
《基于启发式算法求解武器-目标分配问题》
专知会员服务
7+阅读 · 10月12日
《美陆军最新条令出版物 2-0 情报》
专知会员服务
8+阅读 · 10月10日
电子战测试与训练靶场:战前验证战备状态
专知会员服务
3+阅读 · 10月10日
《美国陆军如何作战》46页最新报告
专知会员服务
9+阅读 · 10月10日
相关VIP内容
148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【强化学习资源集合】Awesome Reinforcement Learning
专知会员服务
99+阅读 · 2019年12月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关基金
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员