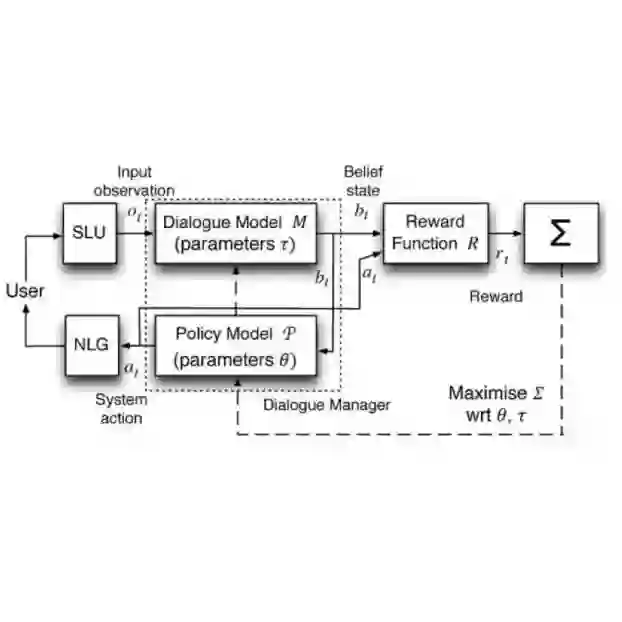
Conversational Query Rewriting (CQR) turns a context dependent user turn into a standalone query for a retriever, and most methods do this in a single step from the dialogue history before retrieving once. The rewrite is therefore fixed before any corpus evidence is available to correct its reference resolution or its vocabulary. We recast CQR as a sequential retrieval problem: an agent rewrites the current turn, retrieves, and conditions its next rewrite on the returned passages. The agent acts in a typed space of three rewriting operations, resolving conversational intent into a standalone query, generating lexical reformulations, or synthesizing pseudo-documents for document-to-document matching, together with a stop action that ends the episode. We train the policy with supervised fine-tuning followed by reinforcement learning against a single retrieval-quality reward, using no human rewrite annotations. Across TopiOCQA and QReCC, the agent outperforms several retrieval-aligned baselines, while remaining effective across retrieval backends and generalizing to the CAsT benchmarks without additional training. Further analysis shows that, through retrieval-reward optimization alone, the learned policy develops a behavior of grounding pseudo-documents in passages retrieved by earlier steps, substantially improving retrieval.


翻译:暂无翻译

0
下载
关闭预览

相关内容

【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
半监督多任务学习:Semisupervised Multitask Learning
我爱读PAMI
18+阅读 · 2018年4月29日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
6+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Arxiv
18+阅读 · 2021年6月10日
VIP会员
最新内容
软件定义无人机蜂群给防空带来全新压力
专知会员服务
5+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
5+阅读 · 10月13日
迈向更智慧的军事情报
专知会员服务
5+阅读 · 10月12日
《美国陆军2026年野战手册 2-0 情报》
专知会员服务
5+阅读 · 10月12日
《基于启发式算法求解武器-目标分配问题》
专知会员服务
7+阅读 · 10月12日
《美陆军最新条令出版物 2-0 情报》
专知会员服务
8+阅读 · 10月10日
电子战测试与训练靶场:战前验证战备状态
专知会员服务
3+阅读 · 10月10日
《美国陆军如何作战》46页最新报告
专知会员服务
9+阅读 · 10月10日
相关VIP内容
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关资讯
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
半监督多任务学习:Semisupervised Multitask Learning
我爱读PAMI
18+阅读 · 2018年4月29日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
相关基金
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
6+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员