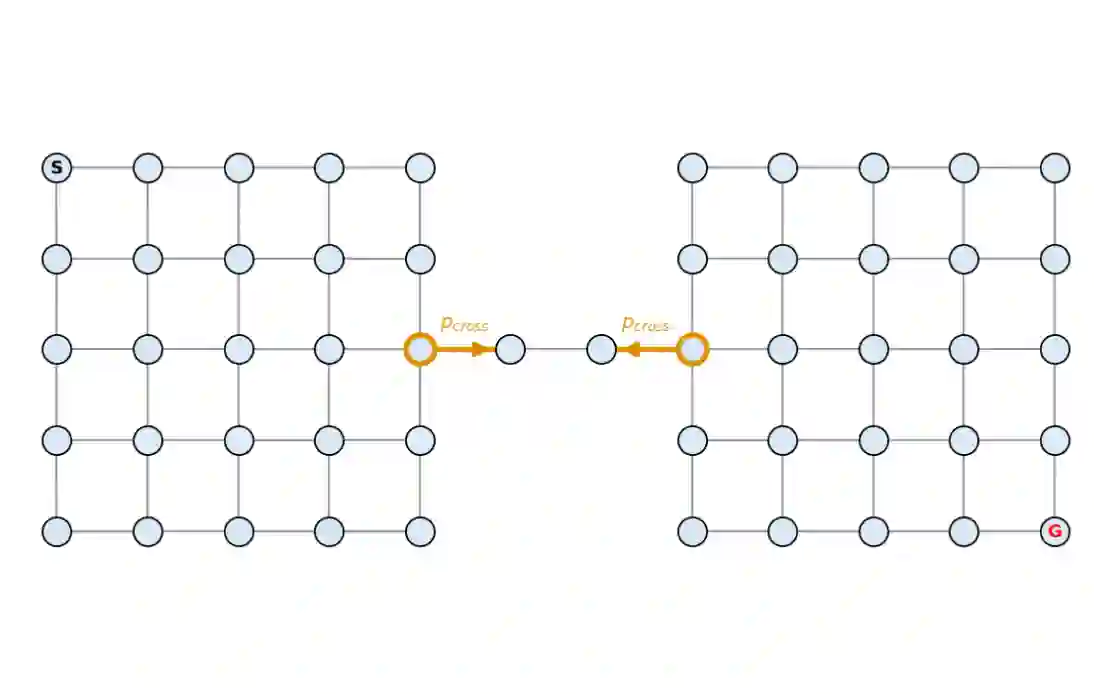
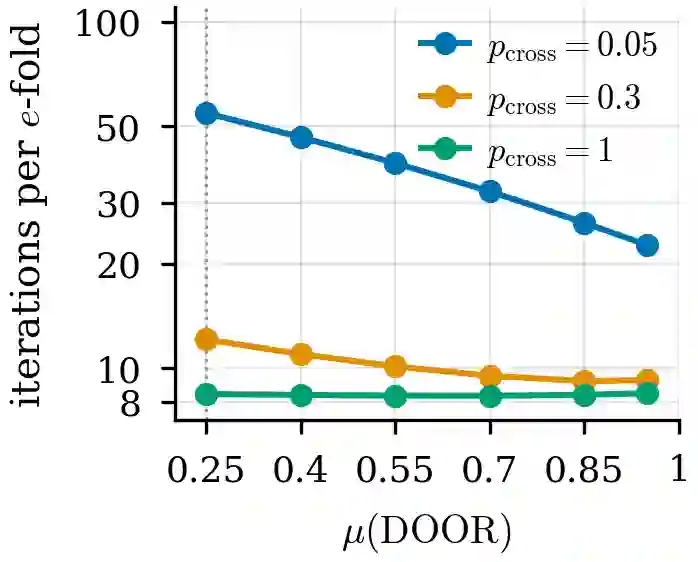
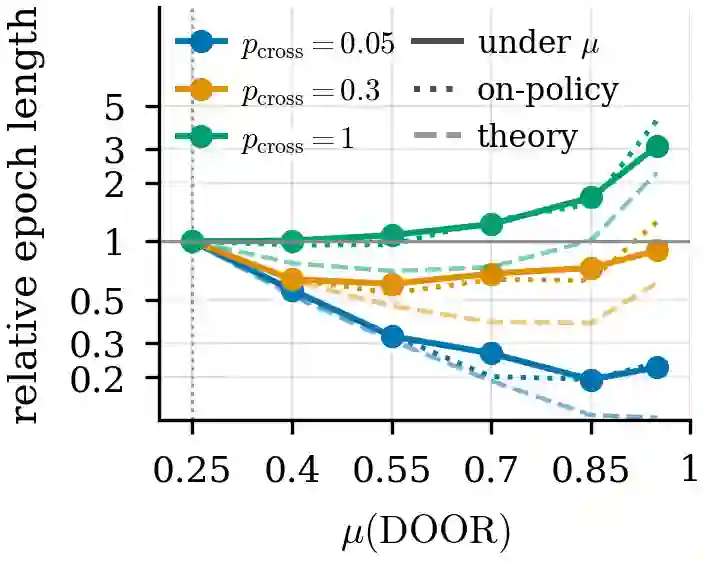
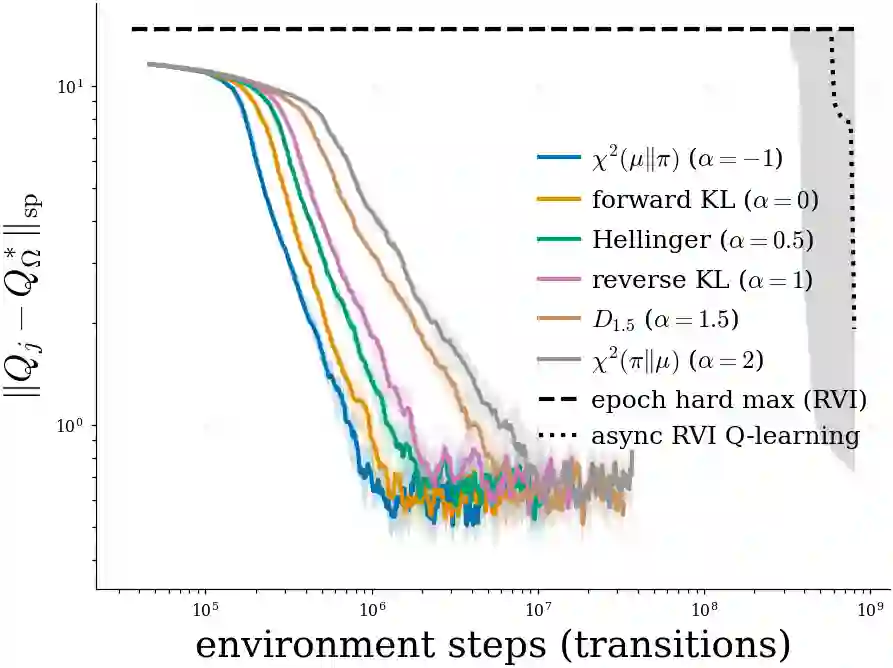
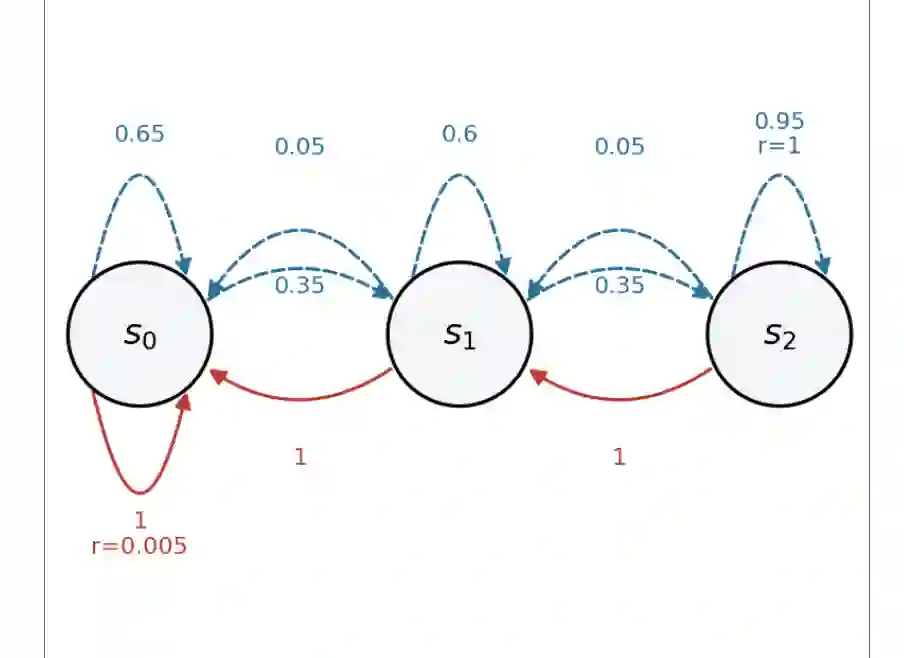
The average-reward setting for reinforcement learning is challenging because its Bellman operator is known to contract in span only when the underlying Markov chain is mixing. Whereas existing work typically assumes a contraction property, e.g., through environment mixing, we consider the setting where we are given a reward-agnostic $m$-step mixing policy, and we control the contraction and exploration properties of the learned policy by regularizing toward the mixing policy. We provide finite-time analysis of $Q$-learning algorithms that can be instantiated with multiple choices of regularization, with guarantees measured with respect to the regularized fixed point. Our framework exposes novel regularizer-dependent objects that control contraction, exploration, and operator bias. In the one-step setting, our rates match the best known rates for $Q$-iteration and synchronous $Q$-learning, and for $m$-step mixing we derive new rates. We also study $Q$-planning variants, and show that planning acts as time-localized learning, where the planning horizon $H$ trades off the bias from the boundary value against the sample complexity. Finally, we present numerical studies validating the analysis: (i) knowledge of a strong mixing policy improves convergence and exploration, and its advantage increases with bottleneck severity and, (ii) our theory predicts the convergence and bias rankings of regularizers from the $α$-divergence family.


翻译:暂无翻译
0
下载
关闭预览

相关内容

148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
【深度强化学习】深度强化学习揭秘
产业智能官
21+阅读 · 2017年11月13日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
17+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
12+阅读 · 2013年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
VIP会员
最新内容
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
8+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
8+阅读 · 10月15日
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
9+阅读 · 10月14日
软件定义无人机蜂群给防空带来全新压力
专知会员服务
10+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
13+阅读 · 10月13日
相关VIP内容
148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关资讯
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
【深度强化学习】深度强化学习揭秘
产业智能官
21+阅读 · 2017年11月13日
相关基金
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
17+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
12+阅读 · 2013年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员