Large language models (LLMs) can generate fluent Arabic answers, yet factual errors remain difficult to detect, localize, explain, and verify. Existing hallucination benchmarks often provide response-level labels, with limited support for identifying the exact erroneous content, explaining why it is incorrect, or selecting the correct factual answer. We introduce HalluTruthQA, a fine-grained benchmark for hallucination evaluation in Arabic question answering. The benchmark contains 2,400 expert-curated examples across four knowledge-intensive domains: Islamic knowledge, history, science, and geography. Each example pairs an Arabic question and a model-generated answer with a verified reference answer, a binary hallucination label, and six candidate answers for factual verification. Hallucinated answers additionally include character-level erroneous spans, human-written explanations, and macro- and micro-level hallucination types. We evaluate four open-source LLMs, ALLaM-7B, Falcon-H1R-7B, Qwen3-32B, and SILMA, in a zero-shot setting across hallucination detection, span-level localization, factual verification, and explanation evaluation. Results show that these tasks capture different abilities: no single model performs best across all tasks. The best scores are 0.880 Macro-F1 for detection, 0.516 F1-Sp for localization, 0.852 LO-Score for factual verification, and 0.644 for explanation evaluation. These findings show that hallucination evaluation should move beyond response-level detection toward the localization, verification, and explanation of factual errors.


翻译:暂无翻译

0
下载
关闭预览

相关内容

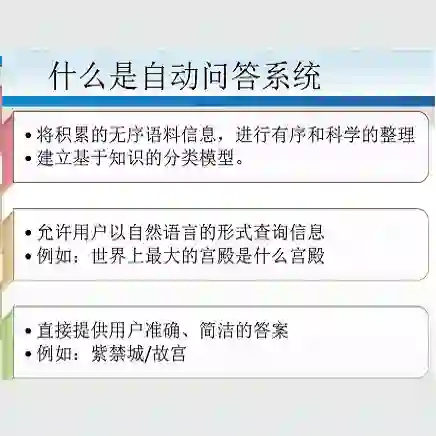
自动问答(Question Answering, QA)是指利用计算机自动回答用户所提出的问题以满足用户知识需求的任务。不同于现有搜索引擎,问答系统是信息服务的一种高级形式,系统返回用户的不再是基于关键词匹配排序的文档列表,而是精准的自然语言答案。近年来,随着人工智能的飞速发展,自动问答已经成为倍受关注且发展前景广泛的研究方向。

知识荟萃

精品入门和进阶教程、论文和代码整理等

更多

查看相关VIP内容、论文、资讯等
大语言模型中的检索与结构化增强生成综述
专知会员服务
34+阅读 · 2025年9月17日
大语言模型中的隐式推理:综合综述
专知会员服务
34+阅读 · 2025年9月4日
大语言模型与小语言模型协同机制综述
专知会员服务
40+阅读 · 2025年5月15日
结合知识增强的大型语言模型复杂问题求解综述
专知会员服务
16+阅读 · 2025年5月7日
重新思考不确定性:大语言模型时代的关键综述与分析
专知会员服务
39+阅读 · 2024年11月20日
基于大语言模型的复杂任务自主规划处理框架
专知会员服务
103+阅读 · 2024年4月12日
绝对干货!NLP预训练模型:从transformer到albert
新智元
15+阅读 · 2019年11月10日
深度学习文本分类方法综述(代码)
中国人工智能学会
28+阅读 · 2018年6月16日
基础 | GRU神经网络
黑龙江大学自然语言处理实验室
27+阅读 · 2018年3月5日
概率图模型体系:HMM、MEMM、CRF
机器学习研究会
30+阅读 · 2018年2月10日
论文浅尝 | Improved Neural Relation Detection for KBQA
开放知识图谱
13+阅读 · 2018年1月21日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
VIP会员
最新内容
软件定义无人机蜂群给防空带来全新压力
专知会员服务
4+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
5+阅读 · 10月13日
迈向更智慧的军事情报
专知会员服务
5+阅读 · 10月12日
《美国陆军2026年野战手册 2-0 情报》
专知会员服务
5+阅读 · 10月12日
《基于启发式算法求解武器-目标分配问题》
专知会员服务
7+阅读 · 10月12日
《美陆军最新条令出版物 2-0 情报》
专知会员服务
8+阅读 · 10月10日
电子战测试与训练靶场:战前验证战备状态
专知会员服务
3+阅读 · 10月10日
《美国陆军如何作战》46页最新报告
专知会员服务
9+阅读 · 10月10日
相关VIP内容
大语言模型中的检索与结构化增强生成综述
专知会员服务
34+阅读 · 2025年9月17日
大语言模型中的隐式推理:综合综述
专知会员服务
34+阅读 · 2025年9月4日
大语言模型与小语言模型协同机制综述
专知会员服务
40+阅读 · 2025年5月15日
结合知识增强的大型语言模型复杂问题求解综述
专知会员服务
16+阅读 · 2025年5月7日
重新思考不确定性:大语言模型时代的关键综述与分析
专知会员服务
39+阅读 · 2024年11月20日
基于大语言模型的复杂任务自主规划处理框架
专知会员服务
103+阅读 · 2024年4月12日
相关基金
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员