

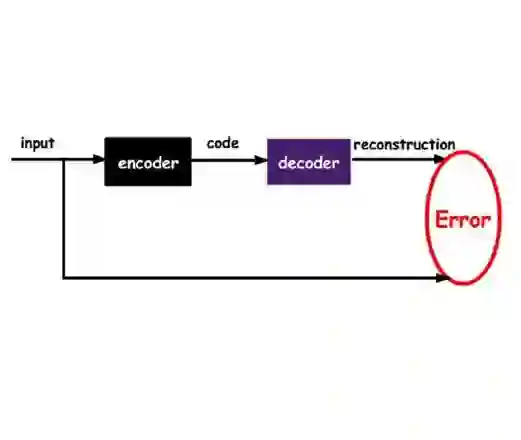
Autoencoders are the core component of latent video generative models, compressing high-dimensional videos into compact latent spaces for downstream generation. However, existing video autoencoders are primarily optimized for pixel-level reconstruction, providing limited supervision for learning structured latent representations. We argue that videos should not be treated merely as signals to be reconstructed, but rather as 2D projections of dynamic 3D worlds that exhibit explicit and well-structured geometric properties. Building on this insight, we propose \textbf{V}ideo \textbf{G}eometry \textbf{G}rounded \textbf{A}utoencoder (\textbf{VGGA}), a geometry-aware video autoencoder that explicitly incorporates geometric constraints into the reconstruction process. Specifically, VGGA grounds the learned representations along three complementary geometric dimensions: \emph{Structural Depth}, \emph{Motion Correspondence}, and \emph{Projective Warping}. These objectives are unified within a Video Geometry Decoder, which employs a shared spatio-temporal upsampling trunk to jointly optimize geometric learning and RGB reconstruction. Through these geometry-grounded objectives, VGGA encourages the latent representations to capture the underlying 3D structure and motion of dynamic scenes. VGGA consistently improves video generation across both geometry-centric and human-motion domains, reducing gFVD by 28.1\% on RealEstate10K and 37.7\% on Taichi-HD. Notably, these substantial generation improvements are achieved while maintaining comparable reconstruction quality, demonstrating that geometry-grounded representation learning yields a more effective latent space for video generation.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员