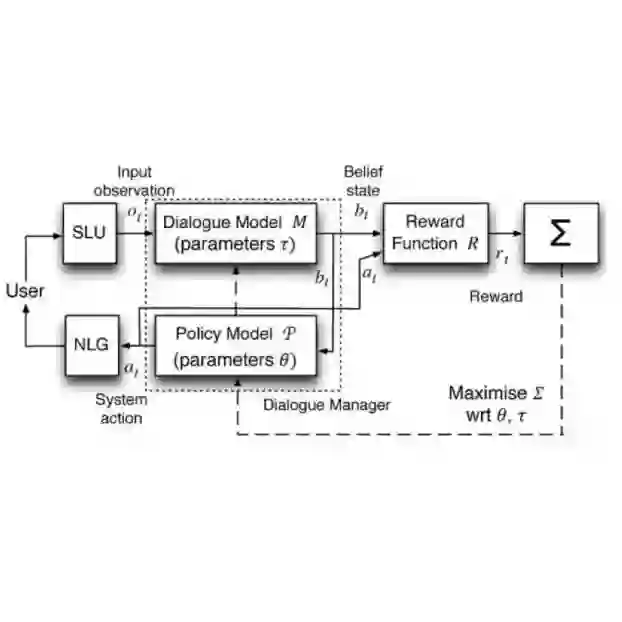
Red teaming is essential for securing Large Language Models, yet current automated methods remain limited by templates and single-turn attacks. To simulate the complex, interactive nature of real-world adversarial attacks, we introduce a novel red teaming paradigm designed to maximize expected cumulative harm through strategic interaction. By formalizing red teaming as a Markov Decision Process in a hierarchical reinforcement learning framework, we navigate the challenges of sparse rewards and long-horizon planning. Our generative agent learns diverse, multi-turn attacks using a token-level harm reward, consistently uncovering vulnerabilities that bypass baselines. This approach achieves a new state of the art and reframes LLM red teaming as a principled, trajectory-based process.


翻译:暂无翻译

0
下载
关闭预览

相关内容

《各指挥层级均亟需红队能力》报告
专知会员服务
11+阅读 · 9月23日
《基于强化学习的自动化红队测试》
专知会员服务
12+阅读 · 7月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
近期语音类前沿论文
深度学习每日摘要
14+阅读 · 2019年3月17日
meta learning 17年:MAML SNAIL
CreateAMind
11+阅读 · 2019年1月2日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
Arxiv
0+阅读 · 10月1日
VIP会员
最新内容
软件定义无人机蜂群给防空带来全新压力
专知会员服务
7+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
7+阅读 · 10月13日
迈向更智慧的军事情报
专知会员服务
6+阅读 · 10月12日
《美国陆军2026年野战手册 2-0 情报》
专知会员服务
5+阅读 · 10月12日
《基于启发式算法求解武器-目标分配问题》
专知会员服务
7+阅读 · 10月12日
《美陆军最新条令出版物 2-0 情报》
专知会员服务
8+阅读 · 10月10日
电子战测试与训练靶场:战前验证战备状态
专知会员服务
3+阅读 · 10月10日
《美国陆军如何作战》46页最新报告
专知会员服务
10+阅读 · 10月10日
相关资讯
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
近期语音类前沿论文
深度学习每日摘要
14+阅读 · 2019年3月17日
meta learning 17年:MAML SNAIL
CreateAMind
11+阅读 · 2019年1月2日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
相关基金
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
Top
微信扫码咨询专知VIP会员