

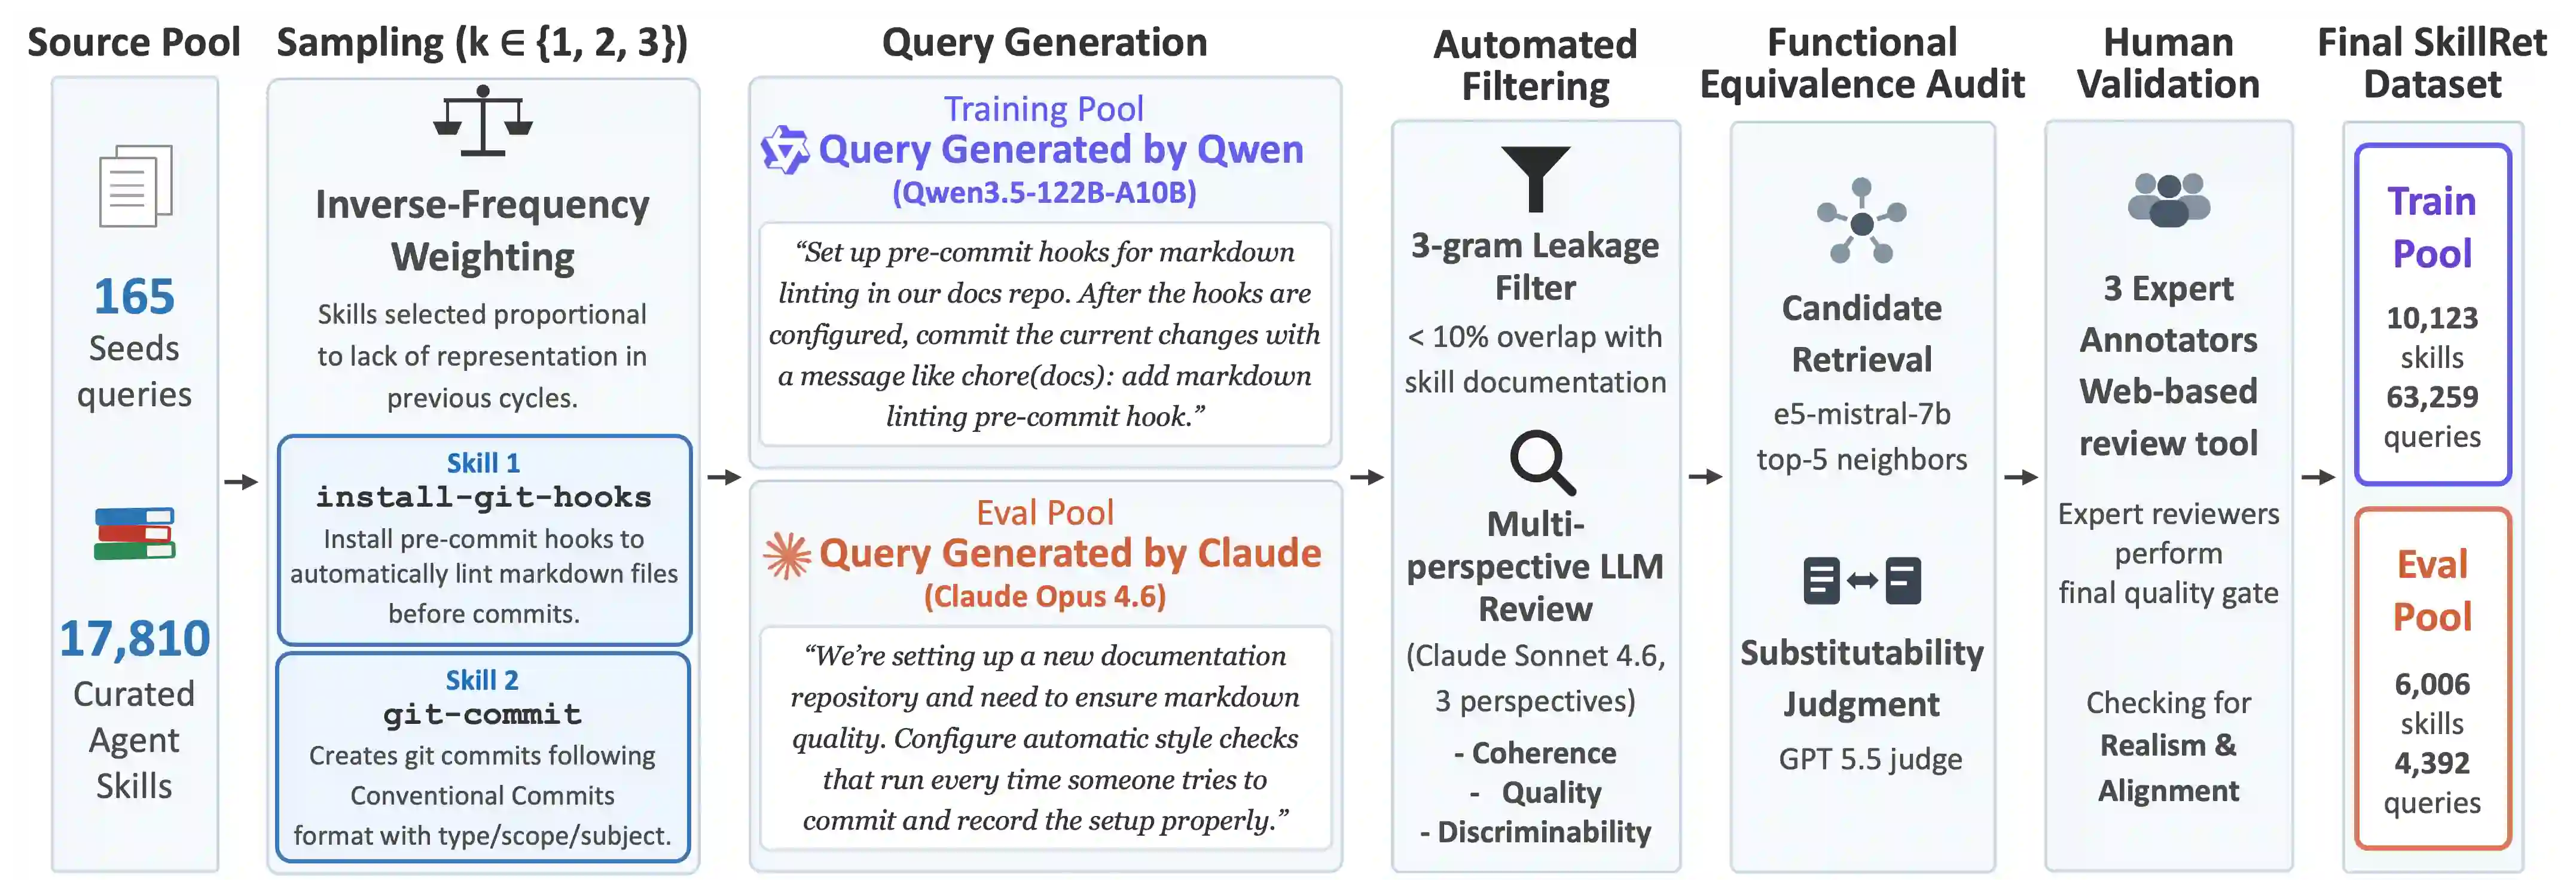
As LLM agents are increasingly deployed with large libraries of reusable skills, selecting the right skill for a user request has become a critical systems challenge. In small libraries, users may invoke skills explicitly by name, but this assumption breaks down as skill ecosystems grow under tight context and latency budgets. Despite its practical importance, skill retrieval remains underexplored, with limited benchmarks and little understanding of retrieval behavior on realistic skill libraries. To address this gap, we introduce SkillRet, a large-scale benchmark for skill retrieval in LLM agents. SkillRet contains 16,129 public agent skills, organized with structured semantic tags and a two-level taxonomy spanning 6 major categories and 18 sub-categories. It provides 63,259 training samples and 4,392 evaluation queries with disjoint skill pools, enabling both benchmarking and retrieval-oriented training. Across a diverse set of retrievers, we find that skill retrieval remains far from solved: off-the-shelf models struggle on realistic large-scale skill libraries, and prior skill-retrieval models still leave substantial headroom. Task-specific fine-tuning on SkillRet improves NDCG@10 by 12.9 points over the strongest prior retriever and by 16.2 points over the strongest off-the-shelf retriever. Our analysis further suggests that these gains arise because fine-tuned models better focus on the small skill-relevant signals within long and noisy queries. These results establish SkillRet as a strong benchmark and foundation for future research on retrieval in large-scale agent systems. We publicly release the benchmark (https://huggingface.co/datasets/ThakiCloud/SKILLRET), code (https://github.com/ThakiCloud/SKILLRET), and model checkpoints (0.6B: https://huggingface.co/ThakiCloud/SKILLRET-Embedding-0.6B; 8B: https://huggingface.co/ThakiCloud/SKILLRET-Embedding-8B).
翻译:暂无翻译




相关内容



 微信扫码咨询专知VIP会员