

The success of the Neural Radiance Fields (NeRFs) for modeling and free-view rendering static objects has inspired numerous attempts on dynamic scenes. Current techniques that utilize neural rendering for facilitating free-view videos (FVVs) are restricted to either offline rendering or are capable of processing only brief sequences with minimal motion. In this paper, we present a novel technique, Residual Radiance Field or ReRF, as a highly compact neural representation to achieve real-time FVV rendering on long-duration dynamic scenes. ReRF explicitly models the residual information between adjacent timestamps in the spatial-temporal feature space, with a global coordinate-based tiny MLP as the feature decoder. Specifically, ReRF employs a compact motion grid along with a residual feature grid to exploit inter-frame feature similarities. We show such a strategy can handle large motions without sacrificing quality. We further present a sequential training scheme to maintain the smoothness and the sparsity of the motion/residual grids. Based on ReRF, we design a special FVV codec that achieves three orders of magnitudes compression rate and provides a companion ReRF player to support online streaming of long-duration FVVs of dynamic scenes. Extensive experiments demonstrate the effectiveness of ReRF for compactly representing dynamic radiance fields, enabling an unprecedented free-viewpoint viewing experience in speed and quality.
翻译:神经辐射场(NeRF)在静态物体建模与自由视角渲染方面的成功,激发了众多针对动态场景的探索。当前利用神经渲染实现自由视点视频(FVV)的技术,要么局限于离线渲染,要么仅能处理运动幅度极小的短序列。本文提出一种名为残差辐射场(ReRF)的新型紧凑神经表示技术,可在长时动态场景中实现实时FVV渲染。ReRF在时空特征空间中显式建模相邻时间戳间的残差信息,并采用基于全局坐标的小型MLP作为特征解码器。具体而言,ReRF通过紧凑的运动网格与残差特征网格来利用帧间特征相似性。实验表明,该策略能在不牺牲质量的前提下处理大幅运动。我们进一步提出顺序训练方案以保持运动/残差网格的平滑性与稀疏性。基于ReRF,我们设计了专用FVV编解码器,实现三个数量级的压缩率,并配套开发了ReRF播放器以支持动态场景长时FVV的在线流式传输。大量实验证明,ReRF能紧凑表示动态辐射场,在速度与质量上实现前所未有的自由视点观看体验。


相关内容
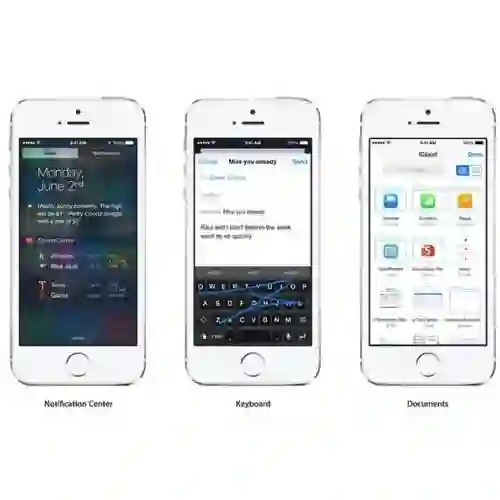
- Today (iOS and OS X): widgets for the Today view of Notification Center
- Share (iOS and OS X): post content to web services or share content with others
- Actions (iOS and OS X): app extensions to view or manipulate inside another app
- Photo Editing (iOS): edit a photo or video in Apple's Photos app with extensions from a third-party apps
- Finder Sync (OS X): remote file storage in the Finder with support for Finder content annotation
- Storage Provider (iOS): an interface between files inside an app and other apps on a user's device
- Custom Keyboard (iOS): system-wide alternative keyboards
Source: iOS 8 Extensions: Apple’s Plan for a Powerful App Ecosystem



 微信扫码咨询专知VIP会员