

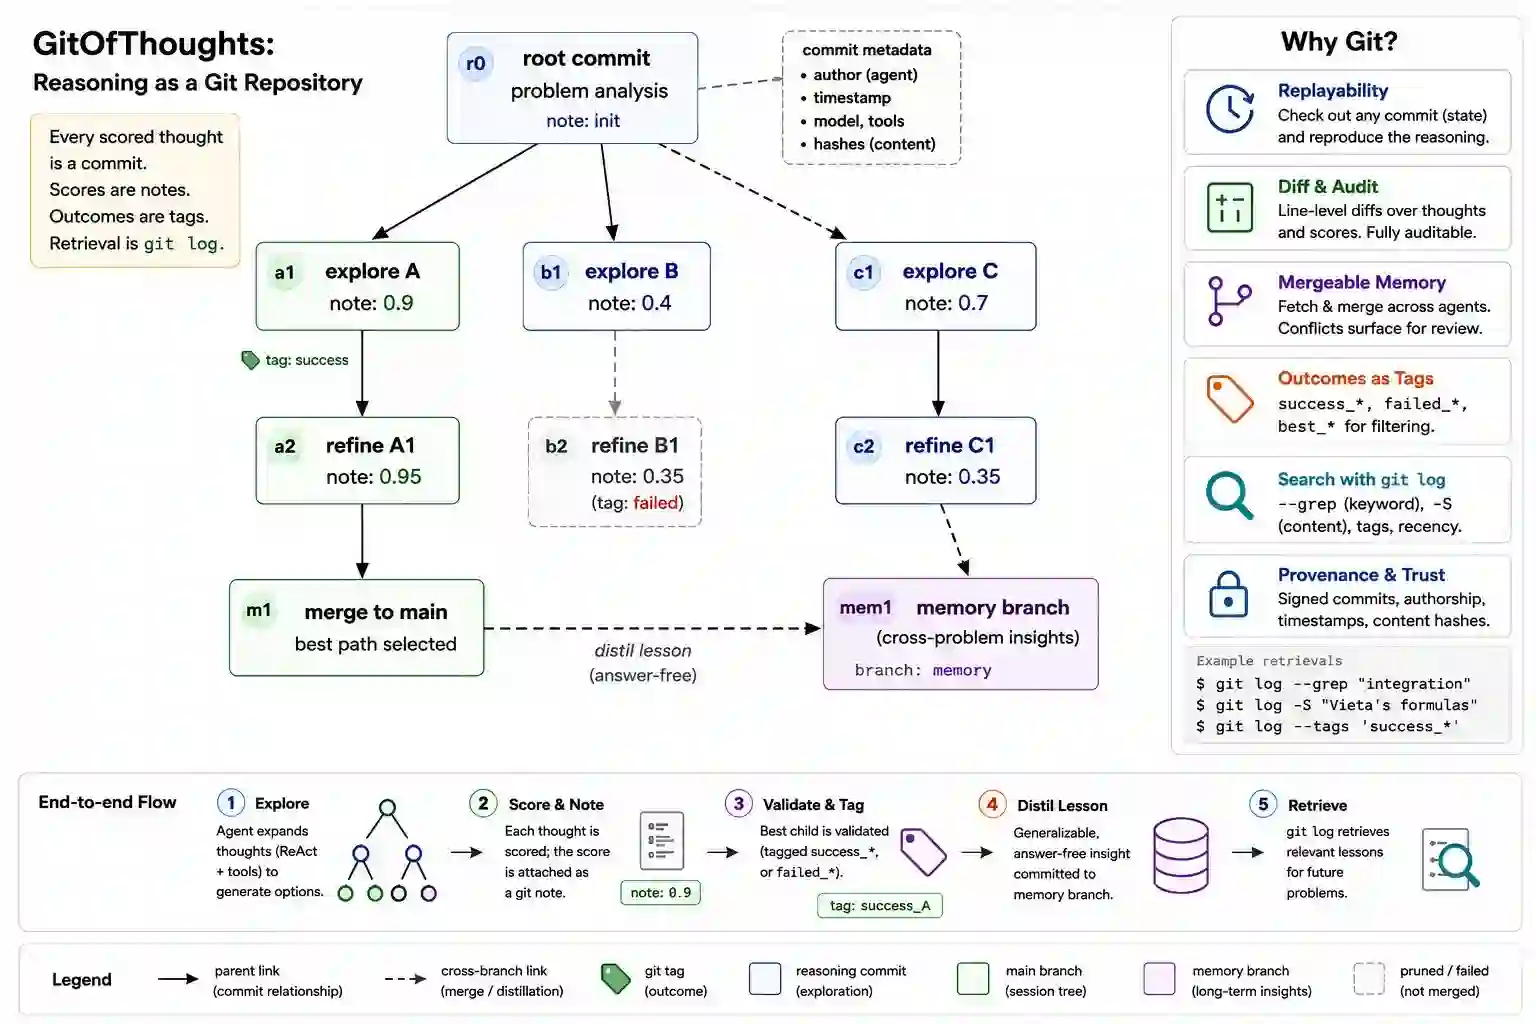
Large language model reasoning leaves no trace once it is done. The steps of a chain of thought disappear when the context window closes, a pruned search branch is just gone, and memory buffers cannot be diffed, merged, or audited. Code, infrastructure, and experiments are all version-controlled. Reasoning is not. GitOfThoughts stores an agent's reasoning tree as a git repository. Every scored thought becomes a commit, scores become notes, outcomes become tags, and retrieval is just git log over the agent's own history. We use this to test something simple. Does giving an agent memory from past problems actually make it more accurate? We tried five memory stores (none, a markdown file, a vector database, a graph, and git) across two benchmarks, two model sizes, and several pre-registered repeat experiments. The answer, on new problems, is no, including one promising early result that did not hold up when we repeated it. Memory only helps once the problem being solved is nearly identical to something already in memory (cosine similarity above about 0.8); below that, it does nothing. In other words, the model is finding the answer rather than learning the method. Even a model 4.5x larger still cannot pull a reusable method out of a worked example; it just gets better at spotting near-copies. The only thing that reliably helped on new problems was generating several answers and picking the most common one (self-consistency). So the case for using git as the memory store is not that it retrieves better. It is that it gives auditability, history, and the ability to merge two agents' memories, at no cost to accuracy.


翻译:暂无翻译
0
下载
关闭预览

相关内容

不可错过!厦大《模式识别》课程,附Slides
专知会员服务
57+阅读 · 2023年6月30日
148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
必读的7篇 IJCAI 2019【图神经网络(GNN)】相关论文
专知会员服务
92+阅读 · 2020年1月10日
FlowQA: Grasping Flow in History for Conversational Machine Comprehension
专知会员服务
35+阅读 · 2019年10月18日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
近期语音类前沿论文
深度学习每日摘要
14+阅读 · 2019年3月17日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
语义分割+视频分割开源代码集合
极市平台
35+阅读 · 2018年3月5日
[深度学习] AlexNet,GoogLeNet,VGG,ResNet简化版
机器学习和数学
20+阅读 · 2017年10月13日
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
VIP会员
最新内容
《衡量语言模型中的作战规划能力》
专知会员服务
1+阅读 · 今天14:34
Maven智能系统:帕兰提尔军事人工智能平台详解
专知会员服务
2+阅读 · 今天14:21
《测试自动化框架在敏捷软件开发中的角色》
专知会员服务
1+阅读 · 今天14:09
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
9+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
14+阅读 · 10月15日
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
11+阅读 · 10月14日
软件定义无人机蜂群给防空带来全新压力
专知会员服务
10+阅读 · 10月13日
相关资讯
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
近期语音类前沿论文
深度学习每日摘要
14+阅读 · 2019年3月17日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
语义分割+视频分割开源代码集合
极市平台
35+阅读 · 2018年3月5日
[深度学习] AlexNet,GoogLeNet,VGG,ResNet简化版
机器学习和数学
20+阅读 · 2017年10月13日
相关基金
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
Top
微信扫码咨询专知VIP会员




