

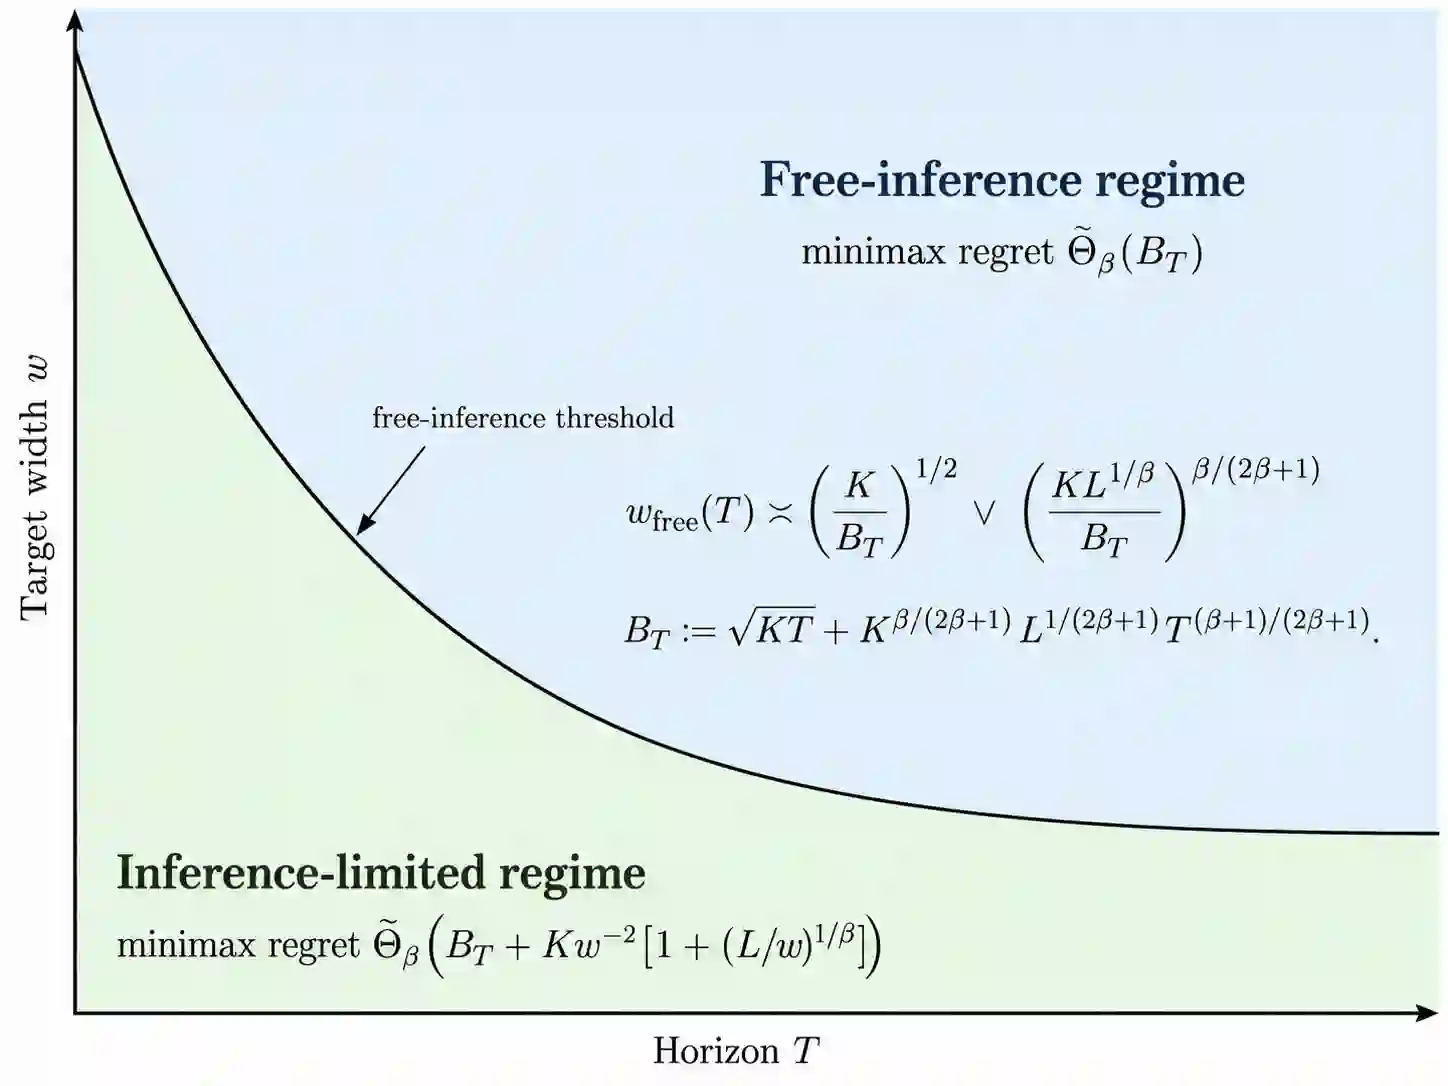
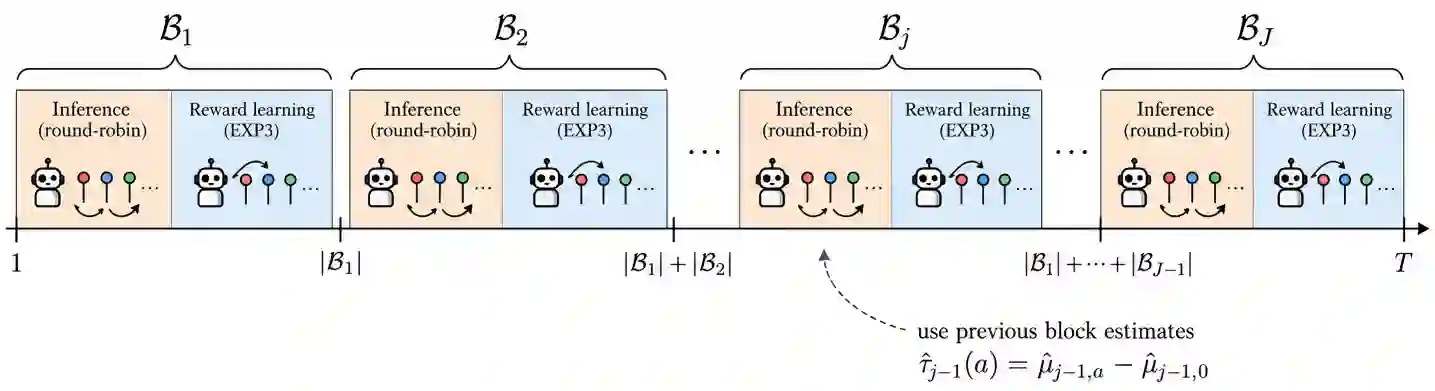
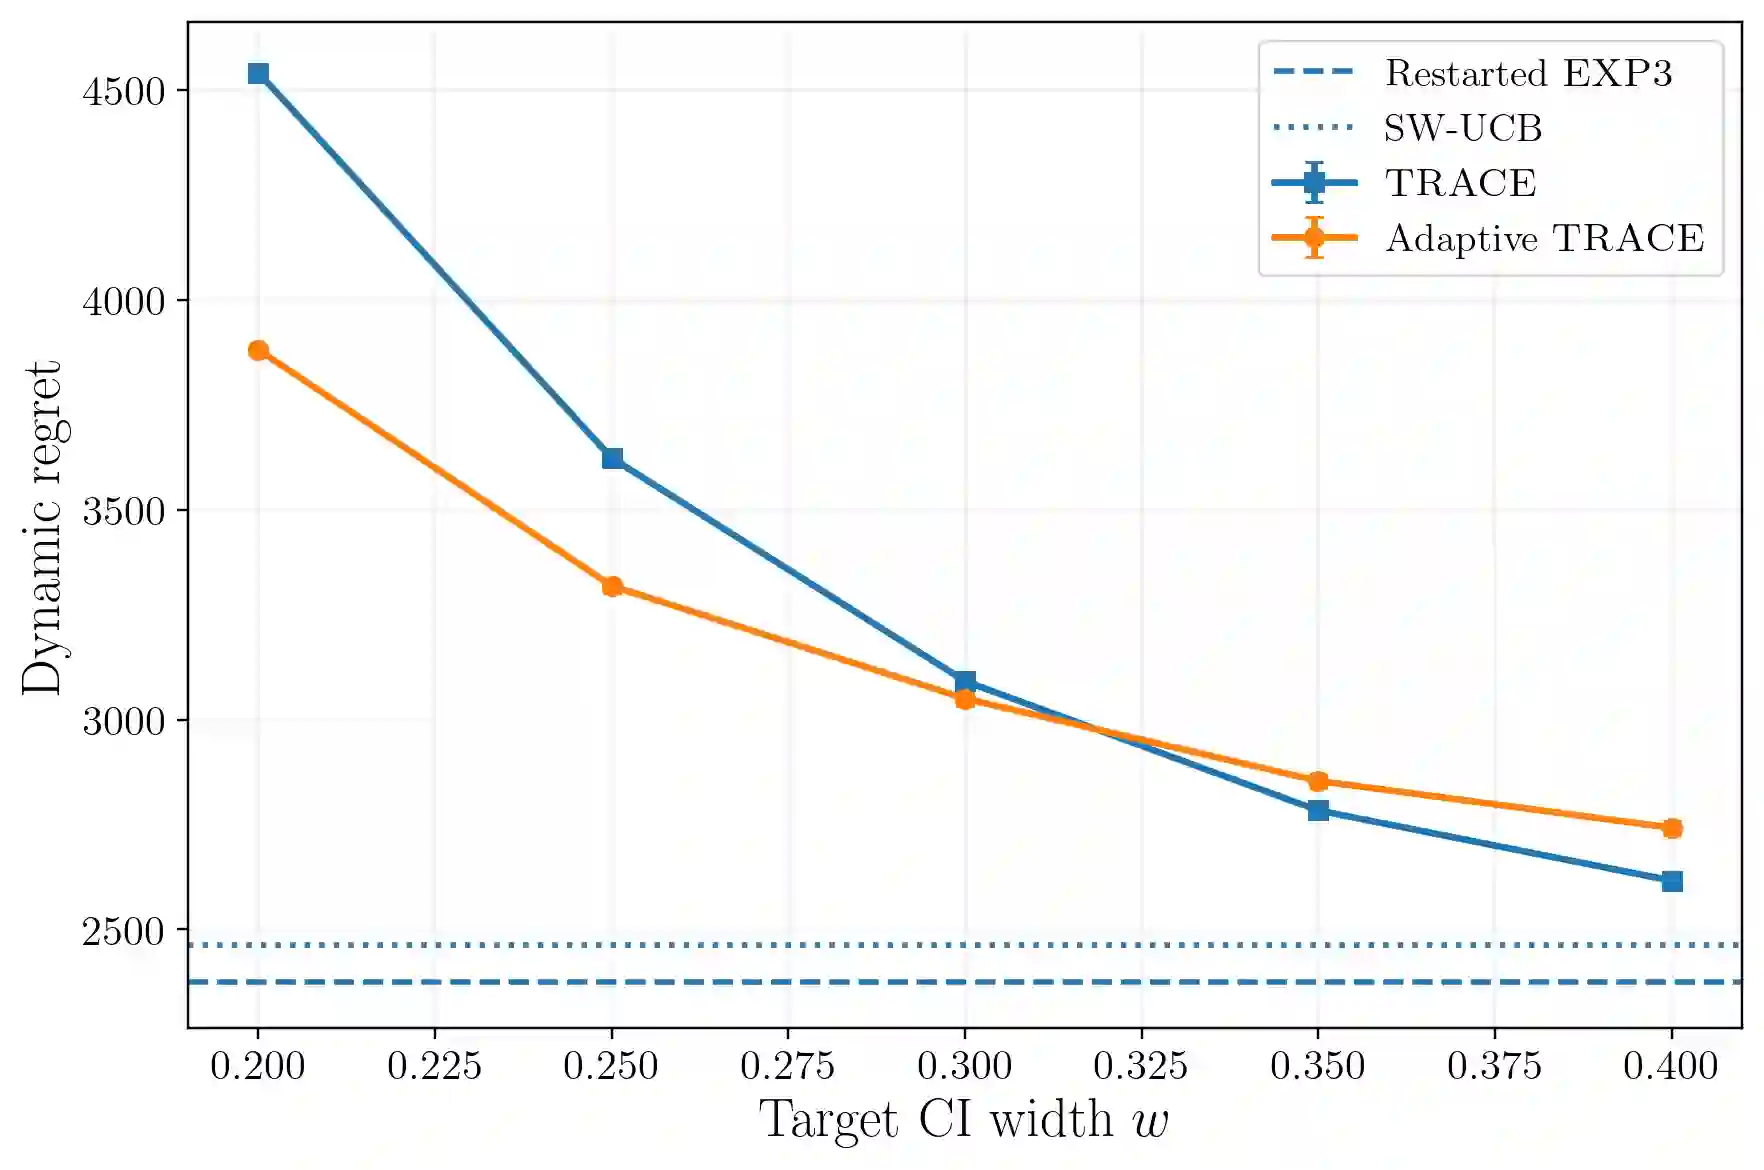
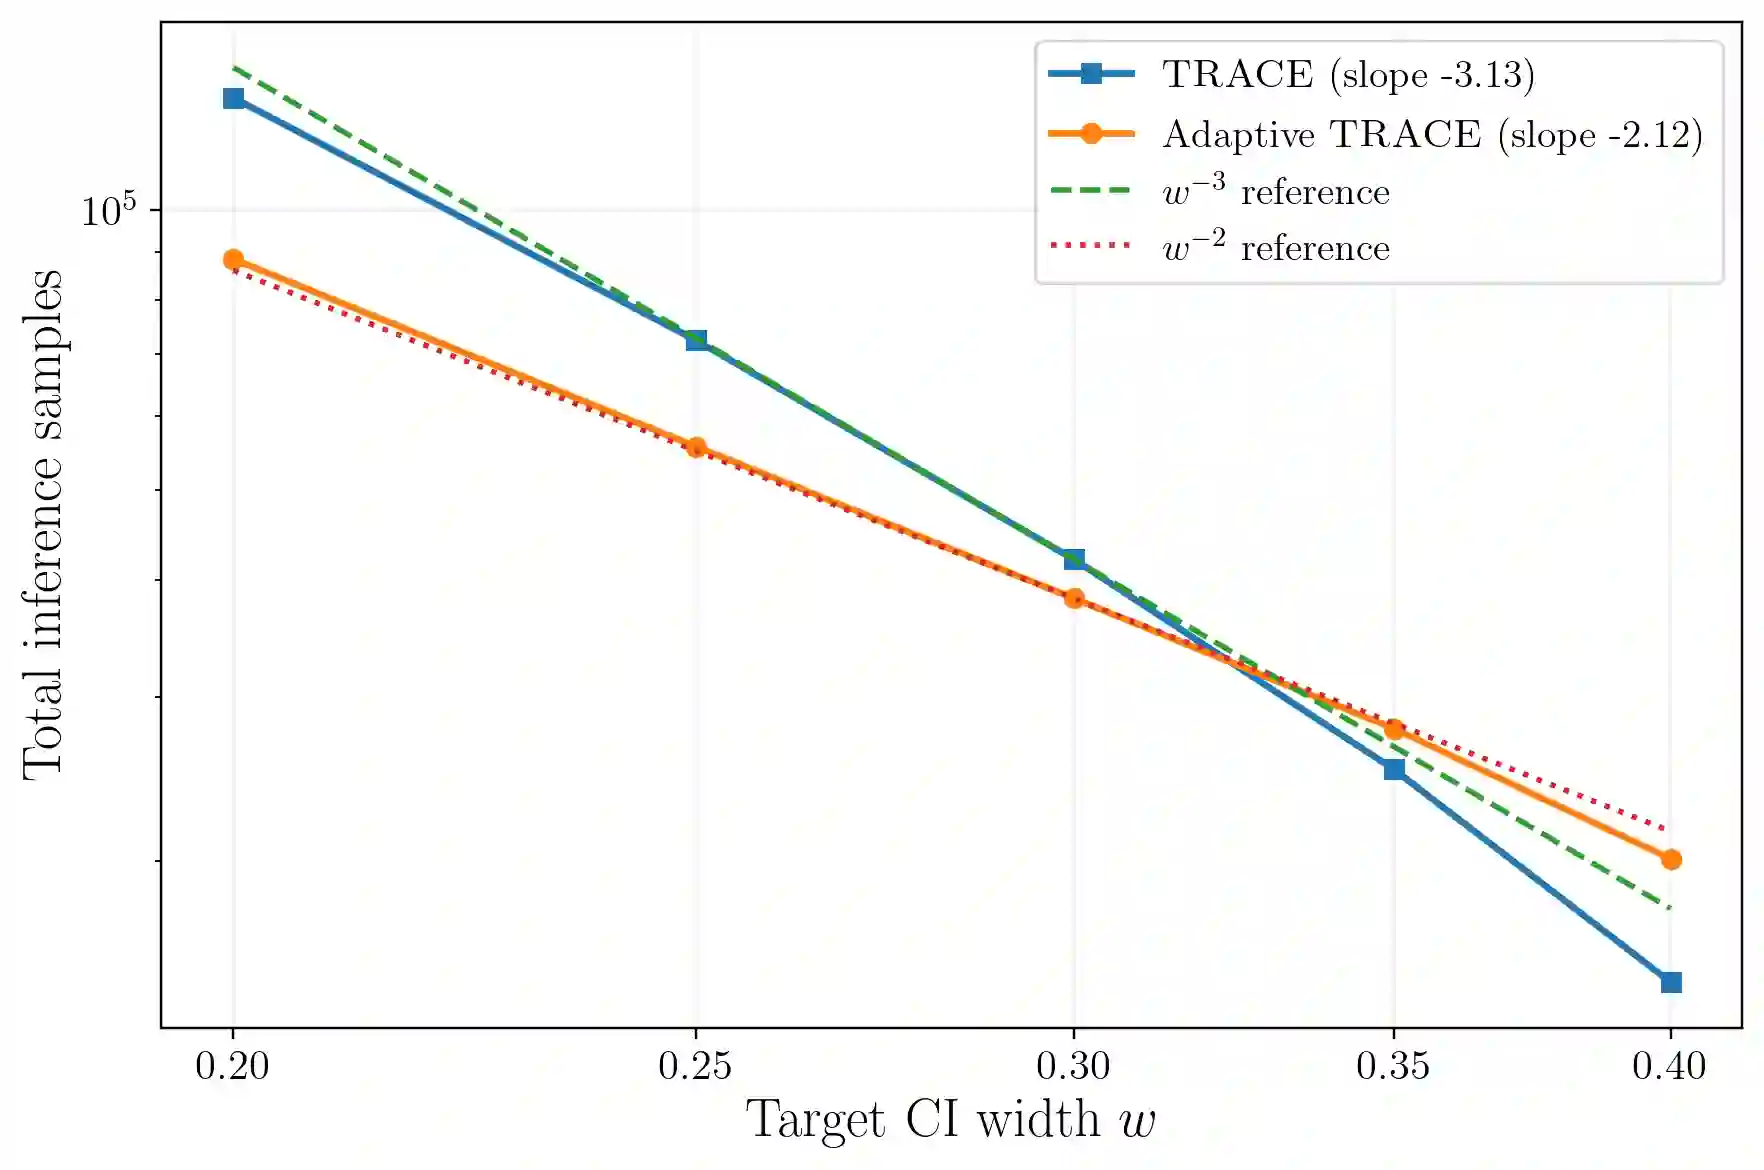
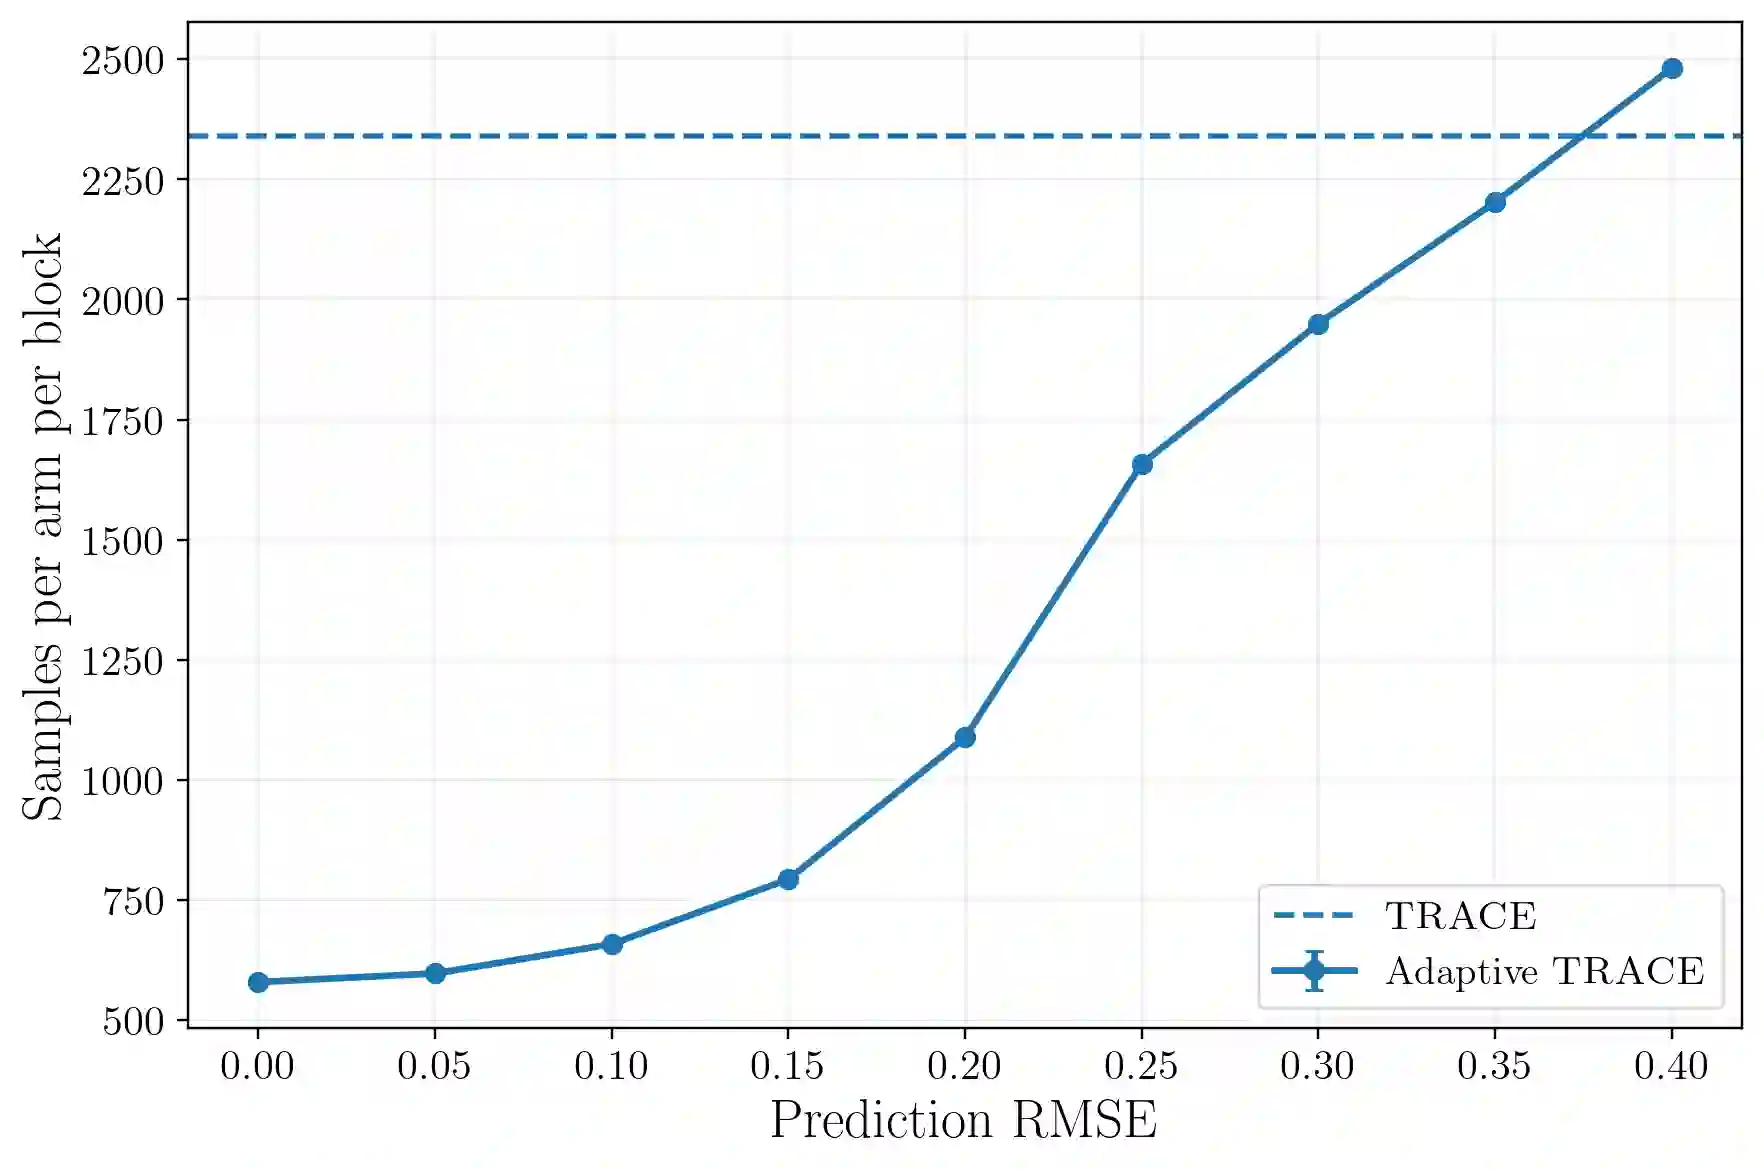
Adaptive experiments use bandit algorithms to favor interventions with higher expected rewards. However, decision-makers also require reliable inference on current treatment effects: differences between intervention and reference-arm mean rewards at the present time, rather than historical averages. These objectives conflict: reward maximization favors better interventions, whereas current-effect inference requires continued exploration of potentially suboptimal interventions as outcomes change over time. We characterize this tradeoff for $K$-arm bandits with Hölder-smooth mean rewards of exponent $β\in(0,1]$ and constant $L$. Requiring high-probability simultaneous coverage of all current effects by confidence intervals of width at most $w$, we establish matching minimax bounds, up to logarithmic factors, on expected dynamic regret. Over horizon $T$, our algorithm TRACE (Tracking Rewards and Current Effects) achieves regret of order $\widetilde{O}_β\left(\sqrt{KT}+K^{β/(2β+1)}L^{1/(2β+1)}T^{(β+1)/(2β+1)}+Kw^{-2}(1+L^{1/β}w^{-1/β})\right)$, where the notation hides logarithms and constants depending only on $β$. This regret--precision tradeoff separates reward-learning regret from the cost of refreshing current-effect estimates, which remains unavoidable even when one arm is uniformly optimal. An empirical-Bernstein e-process extension adapts exploration to realized prediction errors while preserving worst-case guarantees. When within-block drift is negligible relative to sampling error, all observations, including reward-learning observations, can be reused for asymptotically normal pointwise inference and stronger local stationarity yields local asymptotic efficiency. Finally, we show that regret constraints can prevent honest adaptation to unknown smoothness and support our theory with extensive numerical experiments.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员