Recent advances in Vision-Language Models (VLMs) have significantly improved Visual Question Answering (VQA) performance, yet their reasoning over structured content such as tables remains inconsistent, often plagued by spatial misalignment and logical hallucinations. Existing approaches for improving table VQA typically rely on architectural modifications or expensive supervised fine-tuning (SFT), which impose high barriers to entry due to the need for large-scale, expert-annotated datasets and significant computational resources. In this work, we propose Self-RefineVQA, a training-free, inference-time self-correction framework that improves table VQA performance without additional labeled data or model updates. Inspired by human revision behavior, our method enables a single VLM to iteratively act as a generator, critic, and refiner, forming a closed self-feedback loop that corrects common reasoning errors through prompt-guided re-evaluation. Experiments on tabular VQA benchmarks demonstrate that Self-RefineVQA yields consistent accuracy gains in monolingual and cross-lingual understanding, with a particularly significant boost for small models, enabling lightweight models (e.g., 2B-7B parameters) to rival the performance of significantly larger counterparts. Furthermore, we provide a comparative complexity analysis demonstrating that while inference cost increases linearly, our framework offers superior data efficiency and a lower cumulative cost by eliminating the prohibitive annotation bottleneck of human labeling required for fine-tuning. Our results highlight the potential of prompt-based self-improvement as a scalable, accessible paradigm for reliable table reasoning in VLMs.


翻译:暂无翻译

0
下载
关闭预览

相关内容

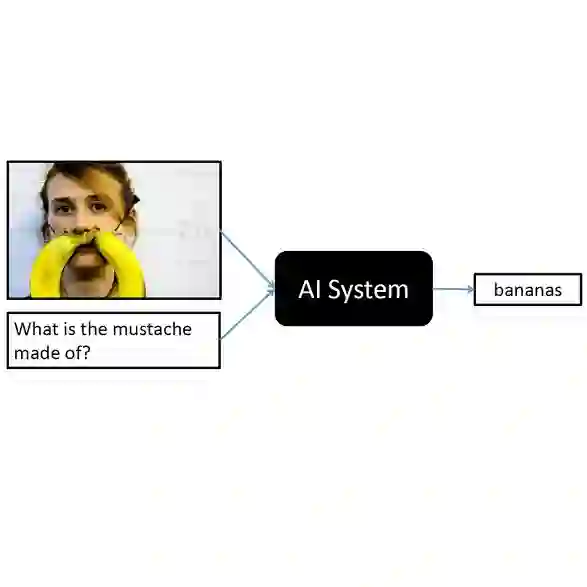
视觉问答(Visual Question Answering,VQA),是一种涉及计算机视觉和自然语言处理的学习任务。这一任务的定义如下: A VQA system takes as input an image and a free-form, open-ended, natural-language question about the image and produces a natural-language answer as the output[1]。 翻译为中文:一个VQA系统以一张图片和一个关于这张图片形式自由、开放式的自然语言问题作为输入,以生成一条自然语言答案作为输出。简单来说,VQA就是给定的图片进行问答。

知识荟萃

精品入门和进阶教程、论文和代码整理等

更多

查看相关VIP内容、论文、资讯等
在无标注条件下适配视觉—语言模型:全面综述
专知会员服务
13+阅读 · 2025年8月9日
高效视觉语言模型研究综述
专知会员服务
14+阅读 · 2025年4月18日
【2022新书】视觉问答 (VQA):从理论到应用
专知会员服务
63+阅读 · 2022年5月24日
【CVPR2021】基于反事实推断的视觉问答框架
专知会员服务
27+阅读 · 2021年3月4日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
论文浅尝 | 基于知识图谱子图匹配以回答自然语言问题
开放知识图谱
26+阅读 · 2018年6月26日
国家自然科学基金
9+阅读 · 2017年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
18+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
7+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
10+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
8+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
5+阅读 · 11月6日
相关VIP内容
在无标注条件下适配视觉—语言模型:全面综述
专知会员服务
13+阅读 · 2025年8月9日
高效视觉语言模型研究综述
专知会员服务
14+阅读 · 2025年4月18日
【2022新书】视觉问答 (VQA):从理论到应用
专知会员服务
63+阅读 · 2022年5月24日
【CVPR2021】基于反事实推断的视觉问答框架
专知会员服务
27+阅读 · 2021年3月4日
相关资讯
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
论文浅尝 | 基于知识图谱子图匹配以回答自然语言问题
开放知识图谱
26+阅读 · 2018年6月26日
相关基金
国家自然科学基金
9+阅读 · 2017年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员