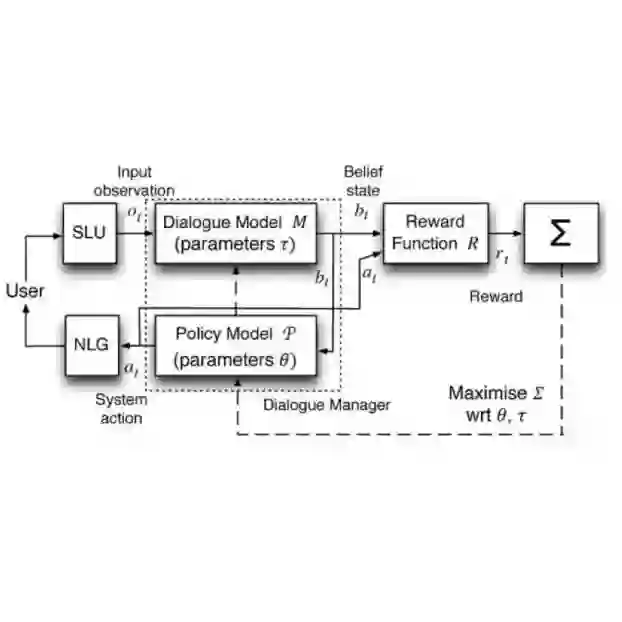
We identify a fundamental mismatch in empathetic reinforcement learning: support priorities evolve with the dialogue state, yet existing methods typically optimize predefined reward specifications that remain fixed across turns. To model these evolving support priorities, we organize empathetic support along cognitive, affective, and proactive empathy, and propose Context-Adaptive Rubric Evolution (CARE). At each turn, CARE generates a context-adaptive rubric by adjusting both the weights of these three empathy dimensions and their fine-grained evaluation criteria. The rubric generator is trained with turn-level rubric supervision and human preference data through supervised fine-tuning followed by preference-based reinforcement learning, and then serves as an adaptive reward interface for online empathetic RL. Integrated with both RLVER and MICA, CARE achieves state-of-the-art performance across SentientBench, EQBench3, and EMPA under three independent LLM judges. Notably, on EMPA, CARE improves EPM-Idx over the strongest baseline by at least 13 points under all three judges, including an increase from 28.11 to 83.54 under Gemini-2.5-Pro. Further analyses show that learned rubric priorities systematically vary across dialogue stages and user emotions, demonstrating that CARE adapts what is rewarded as support needs evolve. Code is available at https://asa13opp.github.io/CARE-project-page.


翻译:暂无翻译

0
下载
关闭预览

相关内容

148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【强化学习资源集合】Awesome Reinforcement Learning
专知会员服务
99+阅读 · 2019年12月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
【深度强化学习】深度强化学习揭秘
产业智能官
21+阅读 · 2017年11月13日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Arxiv
0+阅读 · 10月18日
Arxiv
0+阅读 · 10月12日
Relational Deep Reinforcement Learning
Arxiv
10+阅读 · 2018年6月28日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
18+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
7+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
10+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
8+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
5+阅读 · 11月6日
相关VIP内容
148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
【强化学习资源集合】Awesome Reinforcement Learning
专知会员服务
99+阅读 · 2019年12月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关基金
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员