

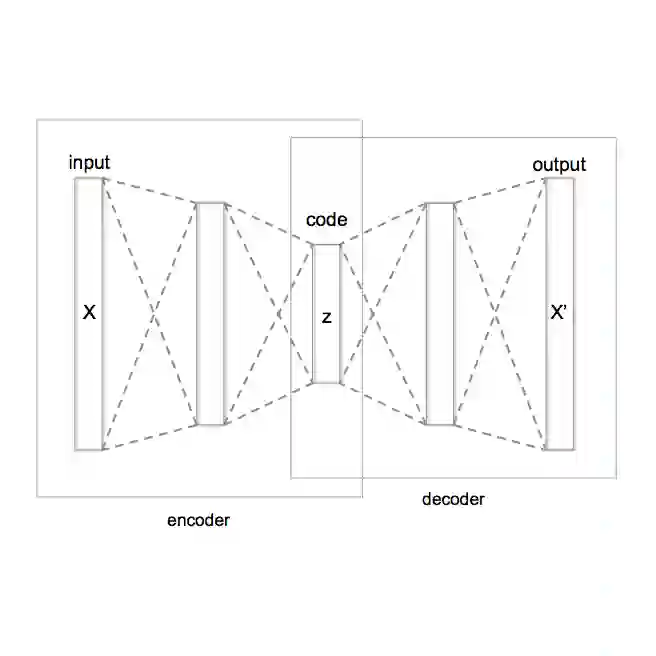
Continuous Variational Autoencoders (VAEs) serve as the fundamental continuous tokenizer for modern neural audio generation systems, enabling high-fidelity reconstruction while providing a compact, smooth latent space for downstream generative priors. However, continuous VAEs face a fundamental conflict among compression rate, reconstruction fidelity, and latent space topology, which we formalize as the Rate-Distortion-Regularity Trilemma. This trilemma stems from a topological mismatch: the isotropic Gaussian prior in standard VAEs imposes a flat latent geometry that fails to accommodate audio's hierarchical nature, where low-frequency components are structured and compressible while high-frequency components are stochastic and incompressible, leading to disordered information packing in which crucial semantic features are interleaved with high-entropy noise. To address this challenge, we propose Structured Topology-Aware Regularization (STAR), a general training strategy that reshapes latent space geometry by imposing a growth-based constraint field, routing structural and textural information into channel subspaces with matching capacities. STAR is applicable to any VAE architecture and effectively resolves the trilemma, as demonstrated in CNN-based VAEs. We further present STAR-VAE, which combines STAR with a hybrid CNN-Mamba architecture for local feature extraction and linear-complexity global context modeling, and STAR-Gen, an LLM-based Flow Matching framework that leverages STAR-VAE's structured latent space for high-fidelity generation without vector quantization artifacts. Experiments across diverse audio domains show that STAR-VAE achieves state-of-the-art reconstruction fidelity and enhanced semantic information preservation, while the structured latent space improves both traditional diffusion models and STAR-Gen for text-to-audio generation.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员