

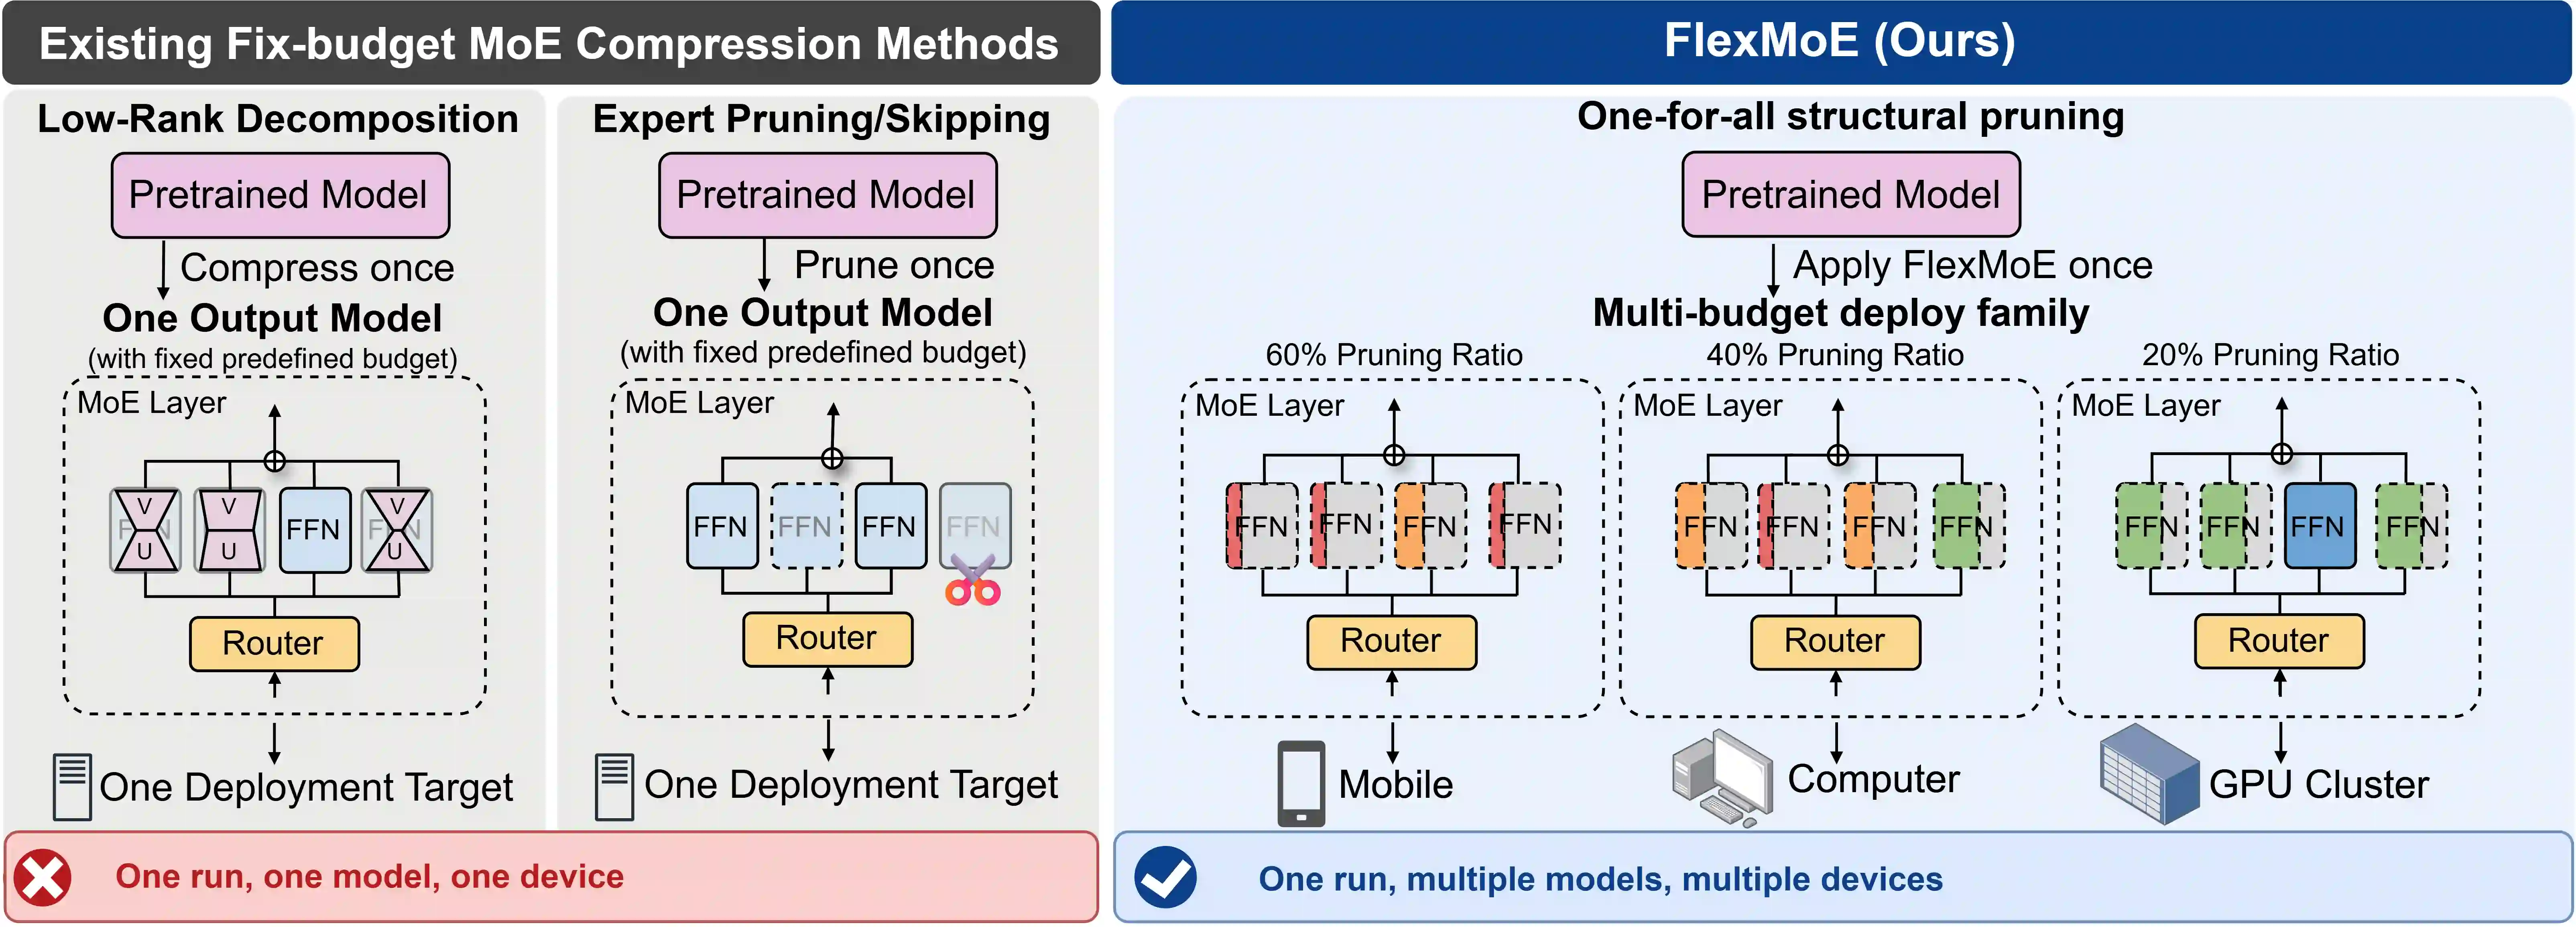
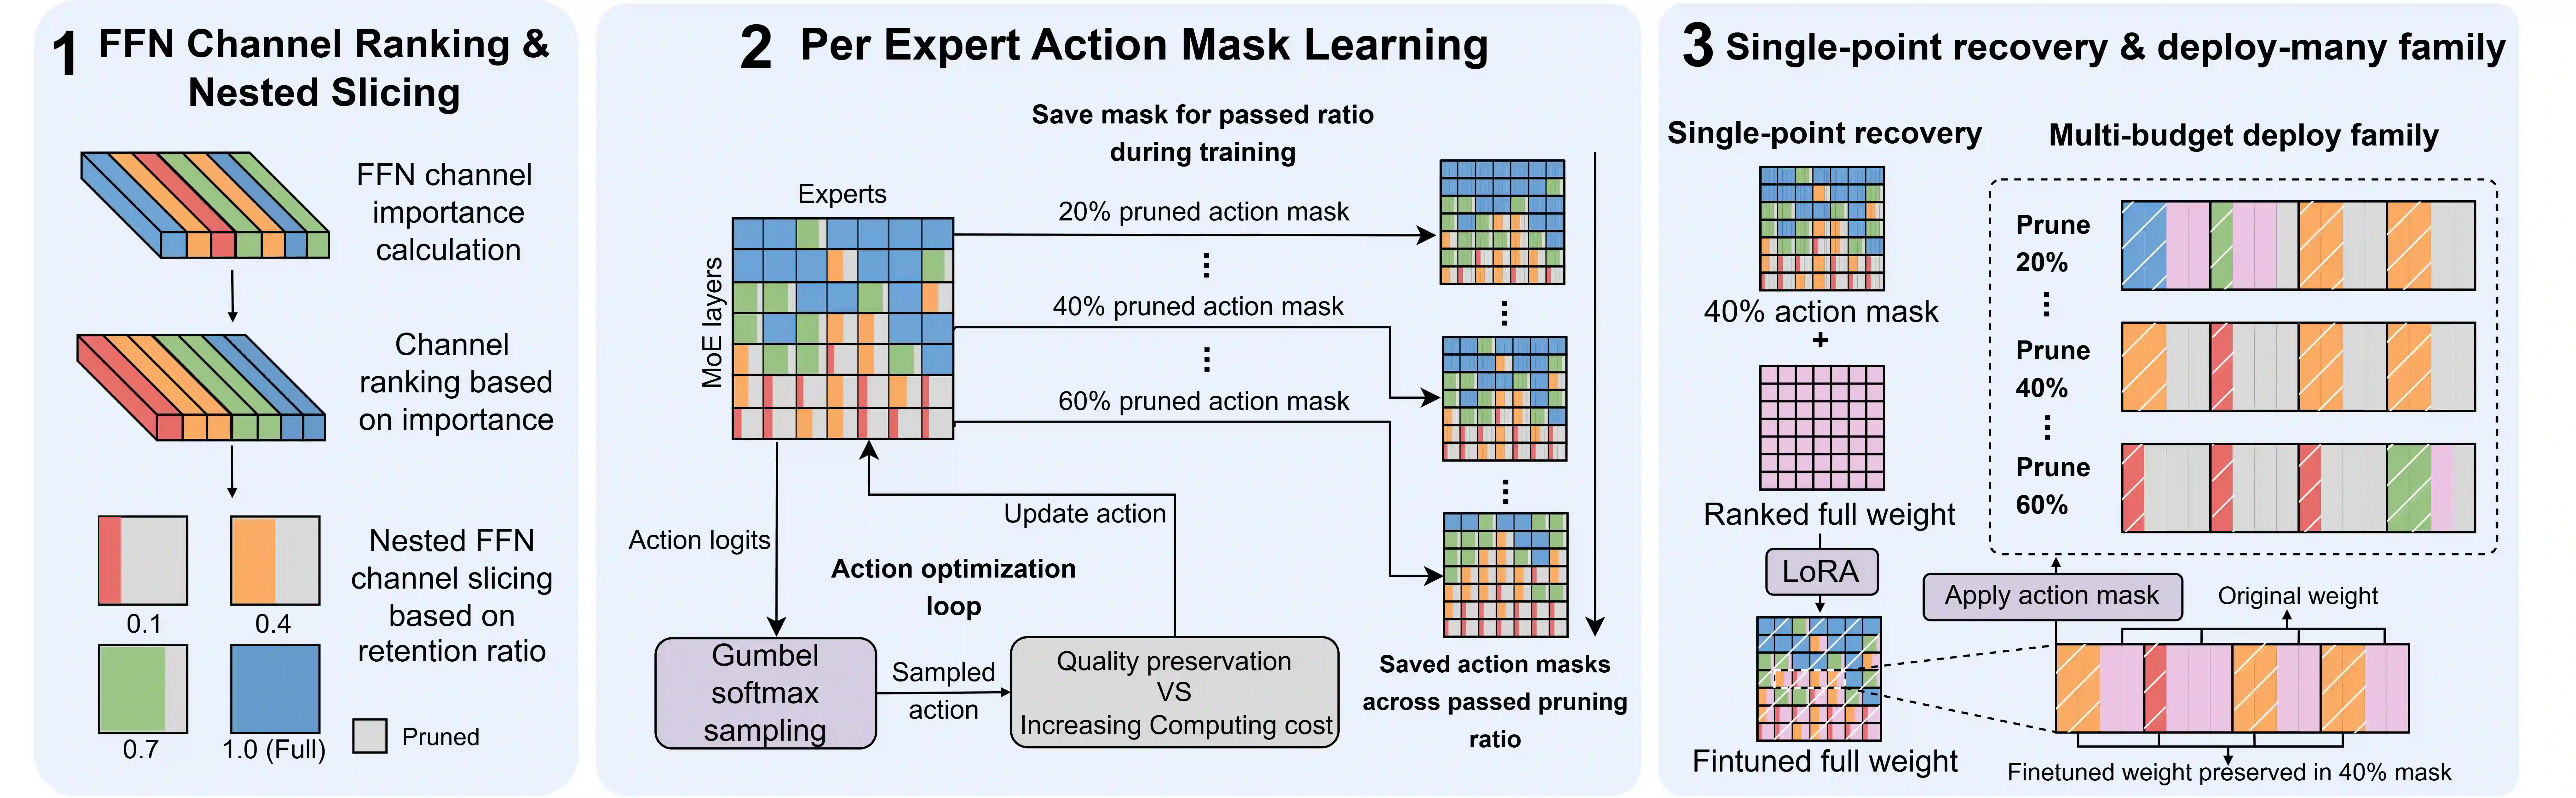
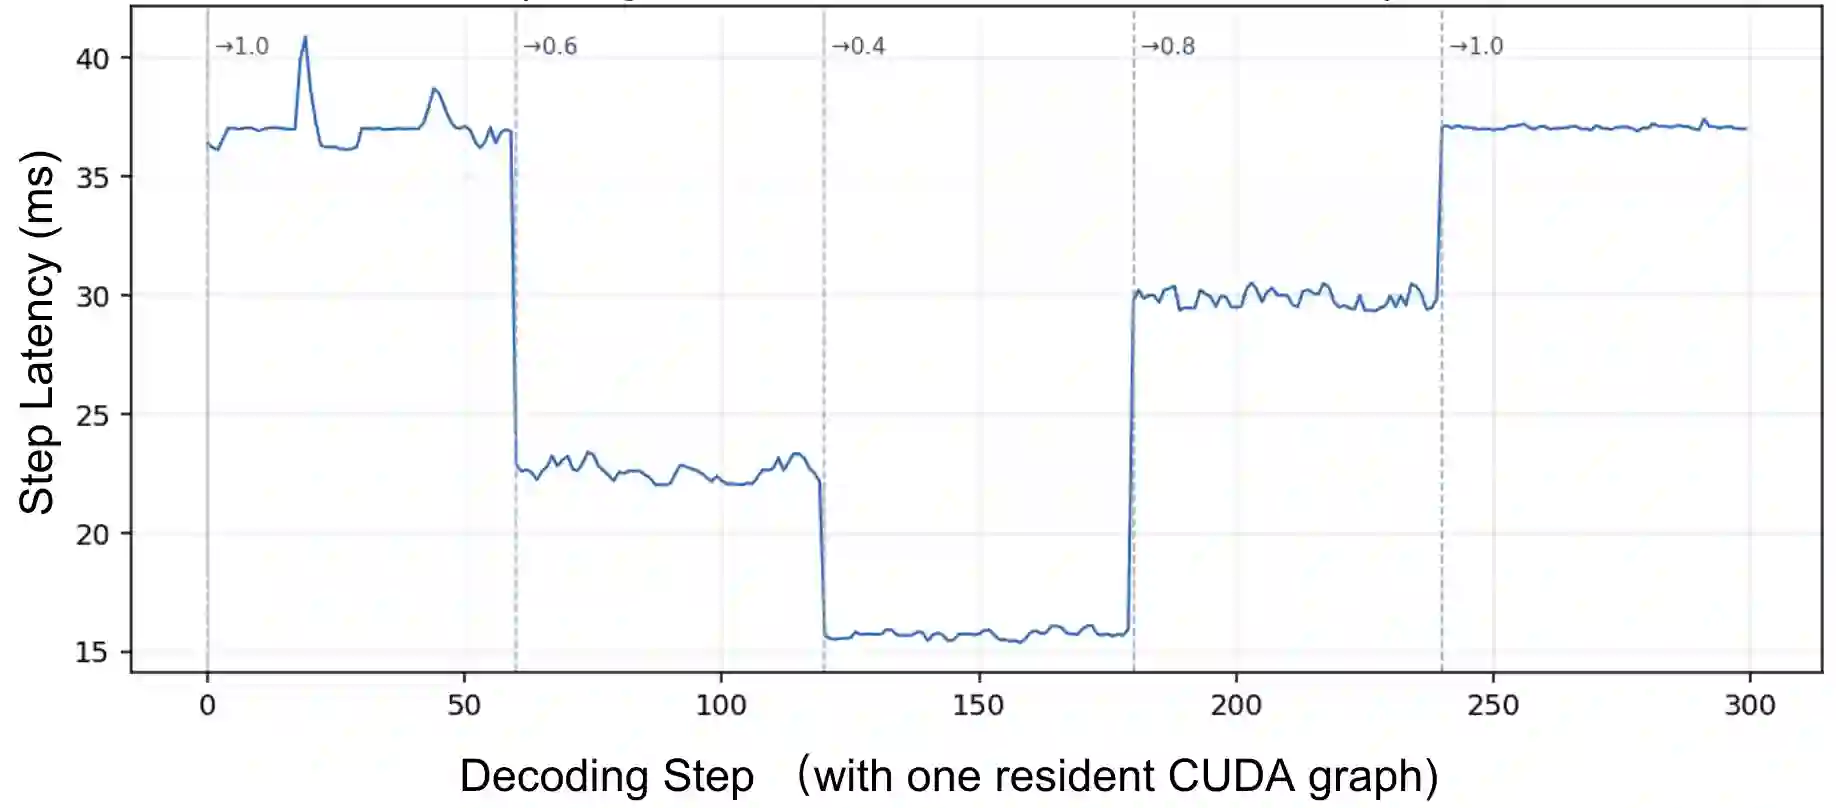
Mixture-of-Experts (MoE) language models scale model capacity through sparse expert activation, yet deployment still requires storing and serving all experts. Moreover, deployment budgets can vary substantially across devices, users, and workloads. Existing MoE compression methods typically optimize a separate compressed model for each target budget. We introduce FlexMoE, a post-training one-for-all framework that converts a large pretrained MoE model into a multi-budget family of smaller deployable subnetworks. FlexMoE first ranks expert FFN channels by importance to construct a sliceable weight space shared across budgets, and then learns expert-wise discrete retention actions under gradually increasing cost pressure, allowing a single action-training run to produce reliable pruning masks across budgets. Moreover, only a single mid-budget fine-tune can further recover degraded performance and yields a shared recovered model that transfers to other unseen budgets, avoiding repeated per-budget recovery and separated checkpoint storage. Across tested MoE LLMs with diverse architectures and scales, FlexMoE consistently outperforms strong MoE compression baselines. In particular, on Qwen2-57B-A14B, it retains ~99.8% of base performance while pruning 50% of routed-expert parameters even without recovery fine-tuning. For deployment, pruned subnetworks deliver real memory reduction and end-to-end throughput gains, while our kernel co-design enables runtime budget switching without checkpoint reloading and delivers substantial inference acceleration.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员