
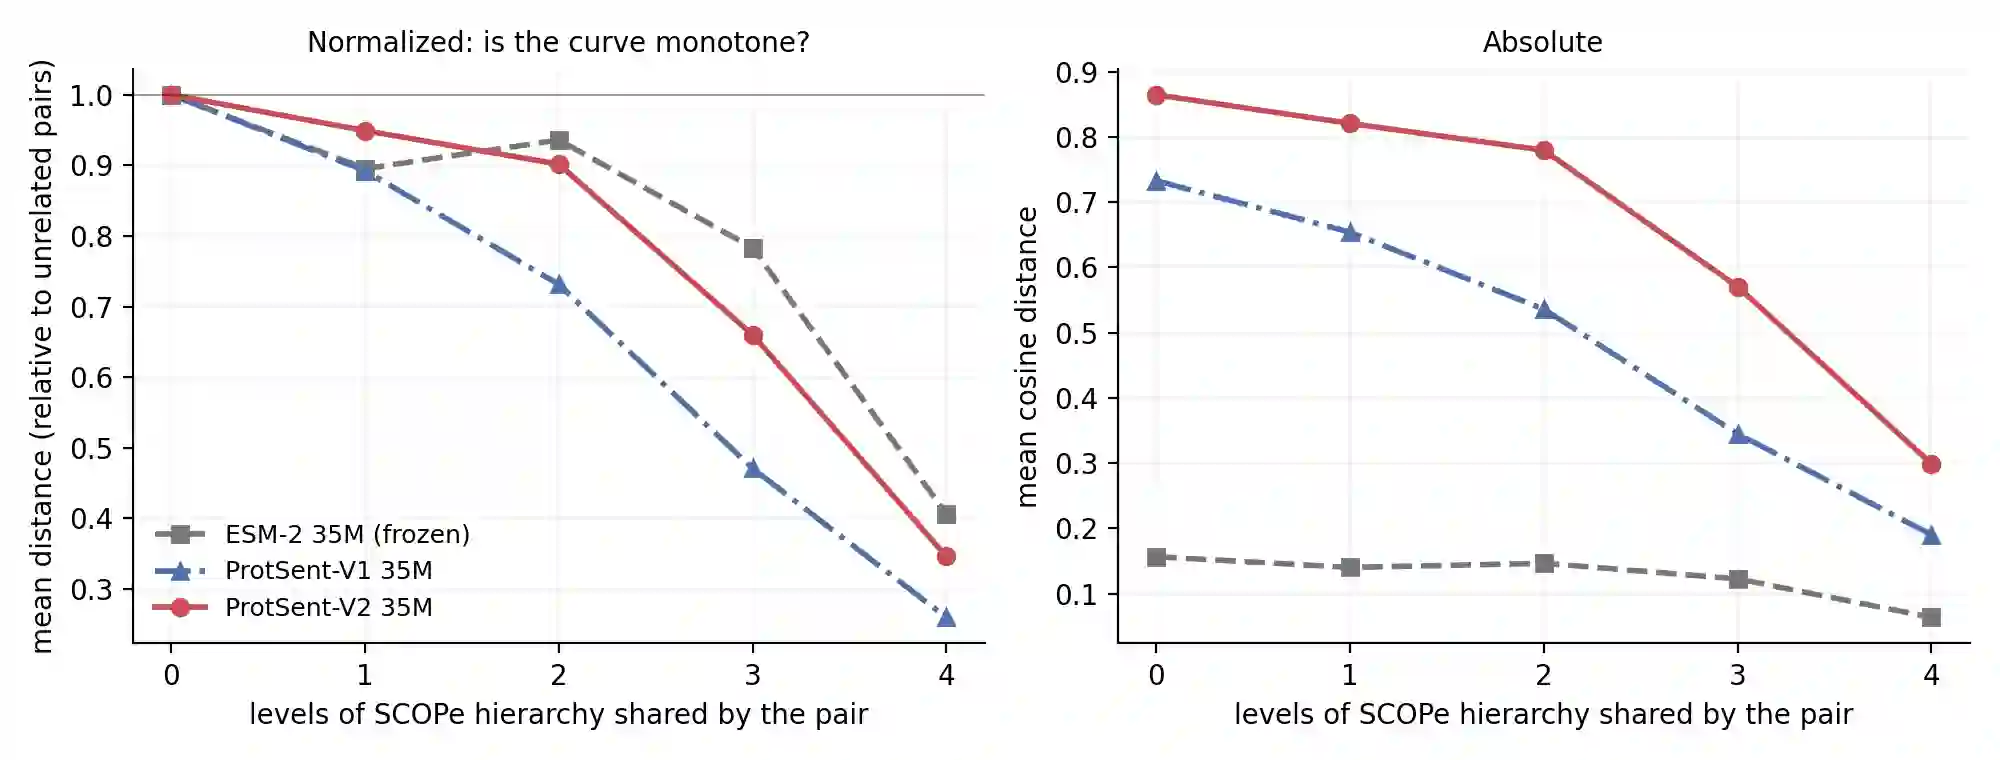
Protein language models produce rich per-residue representations, but the sequence embeddings obtained by mean-pooling them are never trained to place related proteins near one another, so the geometry that retrieval, clustering and nearest-neighbor transfer depend on is never optimized. We present ProtSent, a contrastive post-training framework that supervises a protein language model with three types of biological relation at once, Pfam family co-membership, AlphaFold DB structural clusters and STRING interactions, and with deep mutational scanning fitness ordering as an optional fourth. It needs no structure at training or inference, trains on corpora filtered at 40% sequence identity against the benchmark test sets they most resemble, and is applied to ESM-2 (35M and 150M parameters) and ESM-C (300M). Post-training makes structural family membership recoverable from the frozen embedding without a trained readout: on SCOPe-40, the adjusted Rand index of the 35M model rises from 0.054 (near chance) to 0.507, and family retrieval gains +0.185, +0.190 and +0.424 Recall@1 over the three frozen backbones, with paired bootstrap intervals excluding zero. On the CATH midnight-zone benchmark, homologous-superfamily accuracy rises from 40.7% to 56.7% at 35M and from 43.3% to 62.7% at 150M, more than the 12 points a CATH-supervised model gains over its own base. Against a maximally sensitive HMMER search, alignment keeps the best single hit at both ESM-2 scales, but the embedding leads at ranking depth (MAP 0.705 against 0.607 at 150M) and returns a ranking for every query, including those where alignment finds none. Under a trained linear probe, however, the same embeddings fall below the untuned backbone, as do structure-distilled embeddings against theirs, so the gain in neighborhood structure comes at a cost in linear-probe accuracy. Code and models: https://github.com/oriel9p/ProtSent


翻译:暂无翻译
0
下载
关闭预览

相关内容

ACM/IEEE第23届模型驱动工程语言和系统国际会议,是模型驱动软件和系统工程的首要会议系列,由ACM-SIGSOFT和IEEE-TCSE支持组织。自1998年以来,模型涵盖了建模的各个方面,从语言和方法到工具和应用程序。模特的参加者来自不同的背景,包括研究人员、学者、工程师和工业专业人士。MODELS 2019是一个论坛,参与者可以围绕建模和模型驱动的软件和系统交流前沿研究成果和创新实践经验。今年的版本将为建模社区提供进一步推进建模基础的机会,并在网络物理系统、嵌入式系统、社会技术系统、云计算、大数据、机器学习、安全、开源等新兴领域提出建模的创新应用以及可持续性。 官网链接:http://www.modelsconference.org/
ICML2024|知识感知的强化学习优化的蛋白质定向进化方法
专知会员服务
15+阅读 · 2024年10月18日
ACL 2024 | 基于知识指令的人类语言-蛋白质语言对齐模型
专知会员服务
17+阅读 · 2024年6月29日
用蛋白语言模型改进蛋白复合物预测
专知会员服务
10+阅读 · 2022年9月25日
Science | ProteinMPNN : 基于深度学习的蛋白序列设计
专知会员服务
12+阅读 · 2022年9月18日
综述:基于进化和物理启发建模的计算蛋白设计
专知会员服务
16+阅读 · 2022年9月12日
ICLR2022 | OntoProtein:融入基因本体知识的蛋白质预训练
专知会员服务
29+阅读 · 2022年2月20日
NLP新宠 | 浅谈Prompt的前世今生
机器学习与推荐算法
14+阅读 · 2021年8月16日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
论文浅尝 | Question Answering over Freebase
开放知识图谱
19+阅读 · 2018年1月9日
自然语言处理(二)机器翻译 篇 (NLP: machine translation)
DeepLearning中文论坛
12+阅读 · 2015年7月1日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
11+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
4+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
7+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
4+阅读 · 11月6日
相关VIP内容
ICML2024|知识感知的强化学习优化的蛋白质定向进化方法
专知会员服务
15+阅读 · 2024年10月18日
ACL 2024 | 基于知识指令的人类语言-蛋白质语言对齐模型
专知会员服务
17+阅读 · 2024年6月29日
用蛋白语言模型改进蛋白复合物预测
专知会员服务
10+阅读 · 2022年9月25日
Science | ProteinMPNN : 基于深度学习的蛋白序列设计
专知会员服务
12+阅读 · 2022年9月18日
综述:基于进化和物理启发建模的计算蛋白设计
专知会员服务
16+阅读 · 2022年9月12日
ICLR2022 | OntoProtein:融入基因本体知识的蛋白质预训练
专知会员服务
29+阅读 · 2022年2月20日
相关资讯
NLP新宠 | 浅谈Prompt的前世今生
机器学习与推荐算法
14+阅读 · 2021年8月16日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
论文浅尝 | Question Answering over Freebase
开放知识图谱
19+阅读 · 2018年1月9日
自然语言处理(二)机器翻译 篇 (NLP: machine translation)
DeepLearning中文论坛
12+阅读 · 2015年7月1日
相关基金
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员



