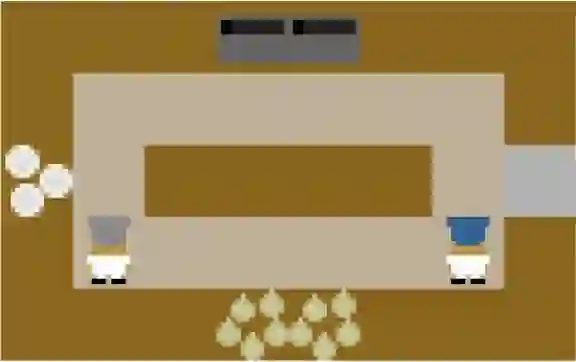
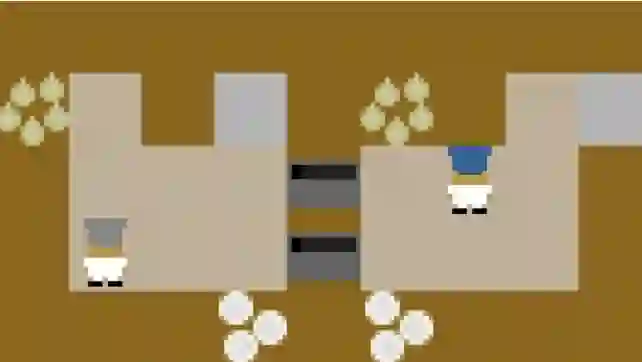
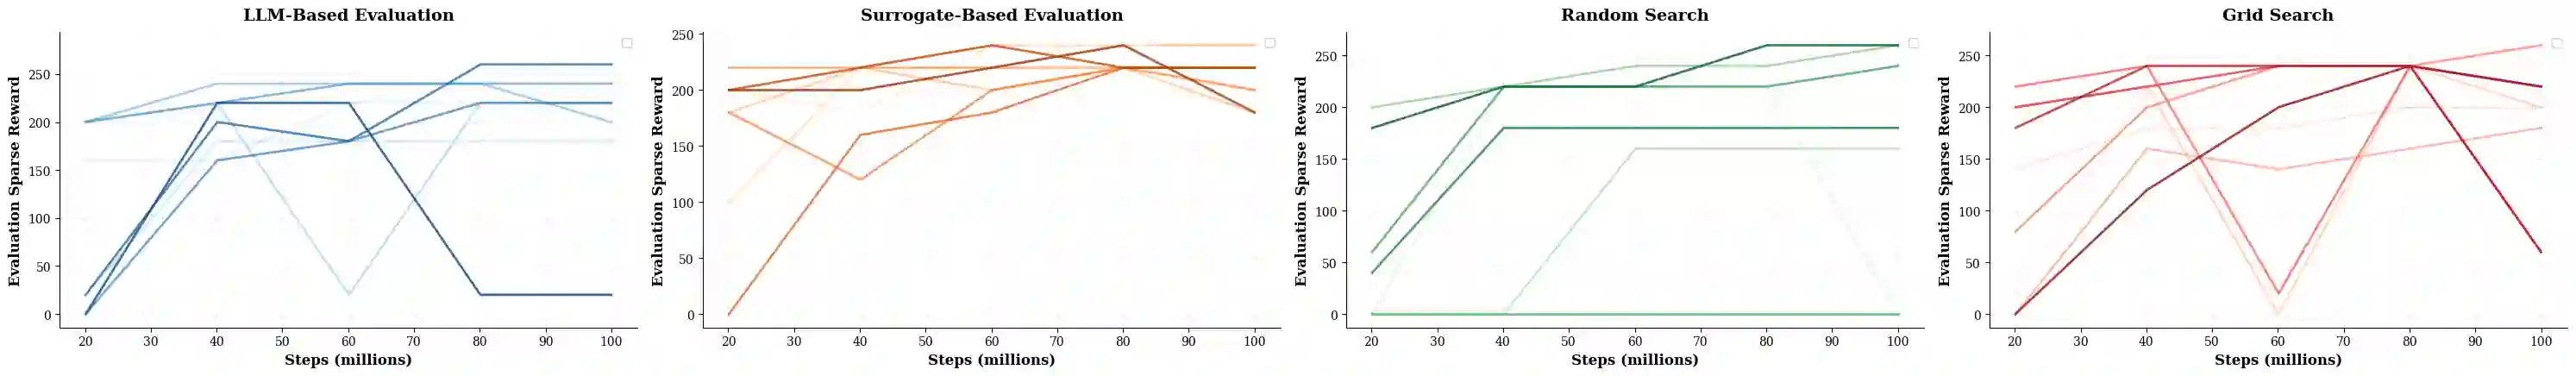
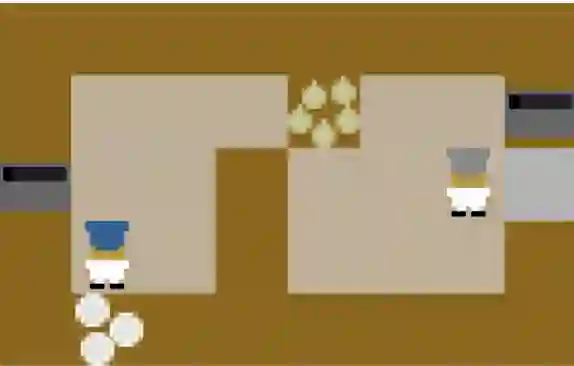
Many Multi-Agent Reinforcement Learning (MARL) agents fail to adapt properly to cooperating with agents trained with the same objectives but different seeds, algorithms, or other training differences. This is the problem of Zero-Shot Coordination (ZSC), which focuses on training agents to cooperate well with unknown agents. ZSC has been studied for a variety of tabular cases and simple games such as Hanabi, achieving excellent results. However, existing solutions to ZSC only consider identical rewards for your trained agents and all future partners. This is not realistic for the trained agents, as they do not consider the problem of cooperating with agents that have identical sparse objectives but shape the rewards for those objectives in different manner. To address this issue, we show how to train an ensemble of methods using randomized reward shapings chosen using 4 selection algorithms. Experiments done on the Overcooked environment demonstrate consistent improvements of 62.2%-119.2% in sparse reward over baseline ZSC algorithms when playing with agents that have identical sparse rewards but different reward shapings.


翻译:暂无翻译
0
下载
关闭预览

相关内容

开放环境下的协作多智能体强化学习进展综述
专知会员服务
36+阅读 · 2025年1月19日
专知会员服务
19+阅读 · 2021年7月11日
【斯坦福大学】Gradient Surgery for Multi-Task Learning
专知会员服务
47+阅读 · 2020年1月23日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
《DeepGCNs: Making GCNs Go as Deep as CNNs》
专知会员服务
32+阅读 · 2019年10月17日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
Zero-Shot Learning相关资源大列表
专知
52+阅读 · 2019年1月1日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Focal Loss for Dense Object Detection
统计学习与视觉计算组
12+阅读 · 2018年3月15日
From Softmax to Sparsemax-ICML16(1)
KingsGarden
74+阅读 · 2016年11月26日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
55+阅读 · 2011年12月31日
国家自然科学基金
19+阅读 · 2008年12月31日
VIP会员
最新内容
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
1+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
2+阅读 · 11月6日
《面向国防领域的大语言模型基准测试与适配》
专知会员服务
17+阅读 · 10月28日
世界模型入门:从序贯决策到通用智能体
专知会员服务
19+阅读 · 10月24日
相关资讯
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
Zero-Shot Learning相关资源大列表
专知
52+阅读 · 2019年1月1日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Focal Loss for Dense Object Detection
统计学习与视觉计算组
12+阅读 · 2018年3月15日
From Softmax to Sparsemax-ICML16(1)
KingsGarden
74+阅读 · 2016年11月26日
相关基金
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
55+阅读 · 2011年12月31日
国家自然科学基金
19+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员