Adapting a generalist vision-language-action (VLA) policy to a target task with limited demonstrations can improve nominal task success while reducing robustness to variations in appearance, objects, and instructions. We introduce reasoning-aligned fine-tuning (RAFT), a two-stage post-training procedure: RAFT first trains low-rank adapters on task-relevant reasoning annotations, then freezes them while fine-tuning the policy on action demonstrations. On a physical DROID robot, RAFT achieves $75.0\%$ out-of-distribution success, compared with $27.9\%$ for plain fine-tuning; on a multi-stage bimanual YAM task, it reaches $70.0\%$ mean success, compared with $36.0\%$ for the strongest baseline. RAFT also improves success under visual, object, and instruction shifts in simulated pick-and-place and open-drawer tasks. Compared with plain fine-tuning, RAFT policies place more attention on annotated task regions and yield higher linear-probe accuracy for object identity in later layers. A broader reasoning-data mixture further improves downstream success across demonstration budgets.


翻译:暂无翻译

0
下载
关闭预览

相关内容

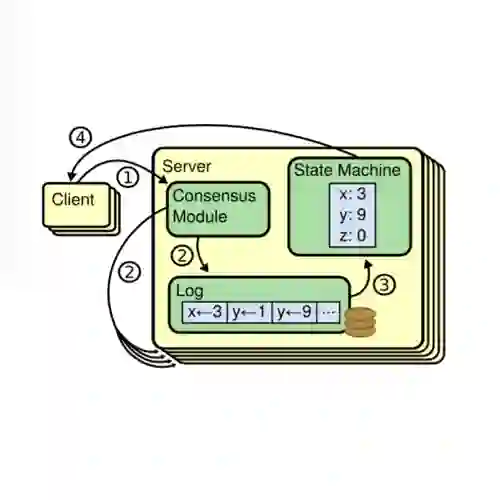
Stanford的Diego Ongaro和John Ousterhout提出了Raft算法,这是一个更容易理解的分布式一致性算法,在算法的论文中,不仅详细描述了算法,甚至给出了RPC接口定义和伪代码,这显然更加容易应用到工程实践中。
视觉-语言-动作(VLA)模型的前世今生
专知会员服务
22+阅读 · 2025年8月29日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
【泡泡图灵智库】密集相关的自监督视觉描述学习(RAL)
泡泡机器人SLAM
11+阅读 · 2018年10月6日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
国家自然科学基金
122+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
97+阅读 · 2009年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
13+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
5+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
7+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
4+阅读 · 11月6日
相关VIP内容
视觉-语言-动作(VLA)模型的前世今生
专知会员服务
22+阅读 · 2025年8月29日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关基金
国家自然科学基金
122+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
97+阅读 · 2009年12月31日
Top
微信扫码咨询专知VIP会员