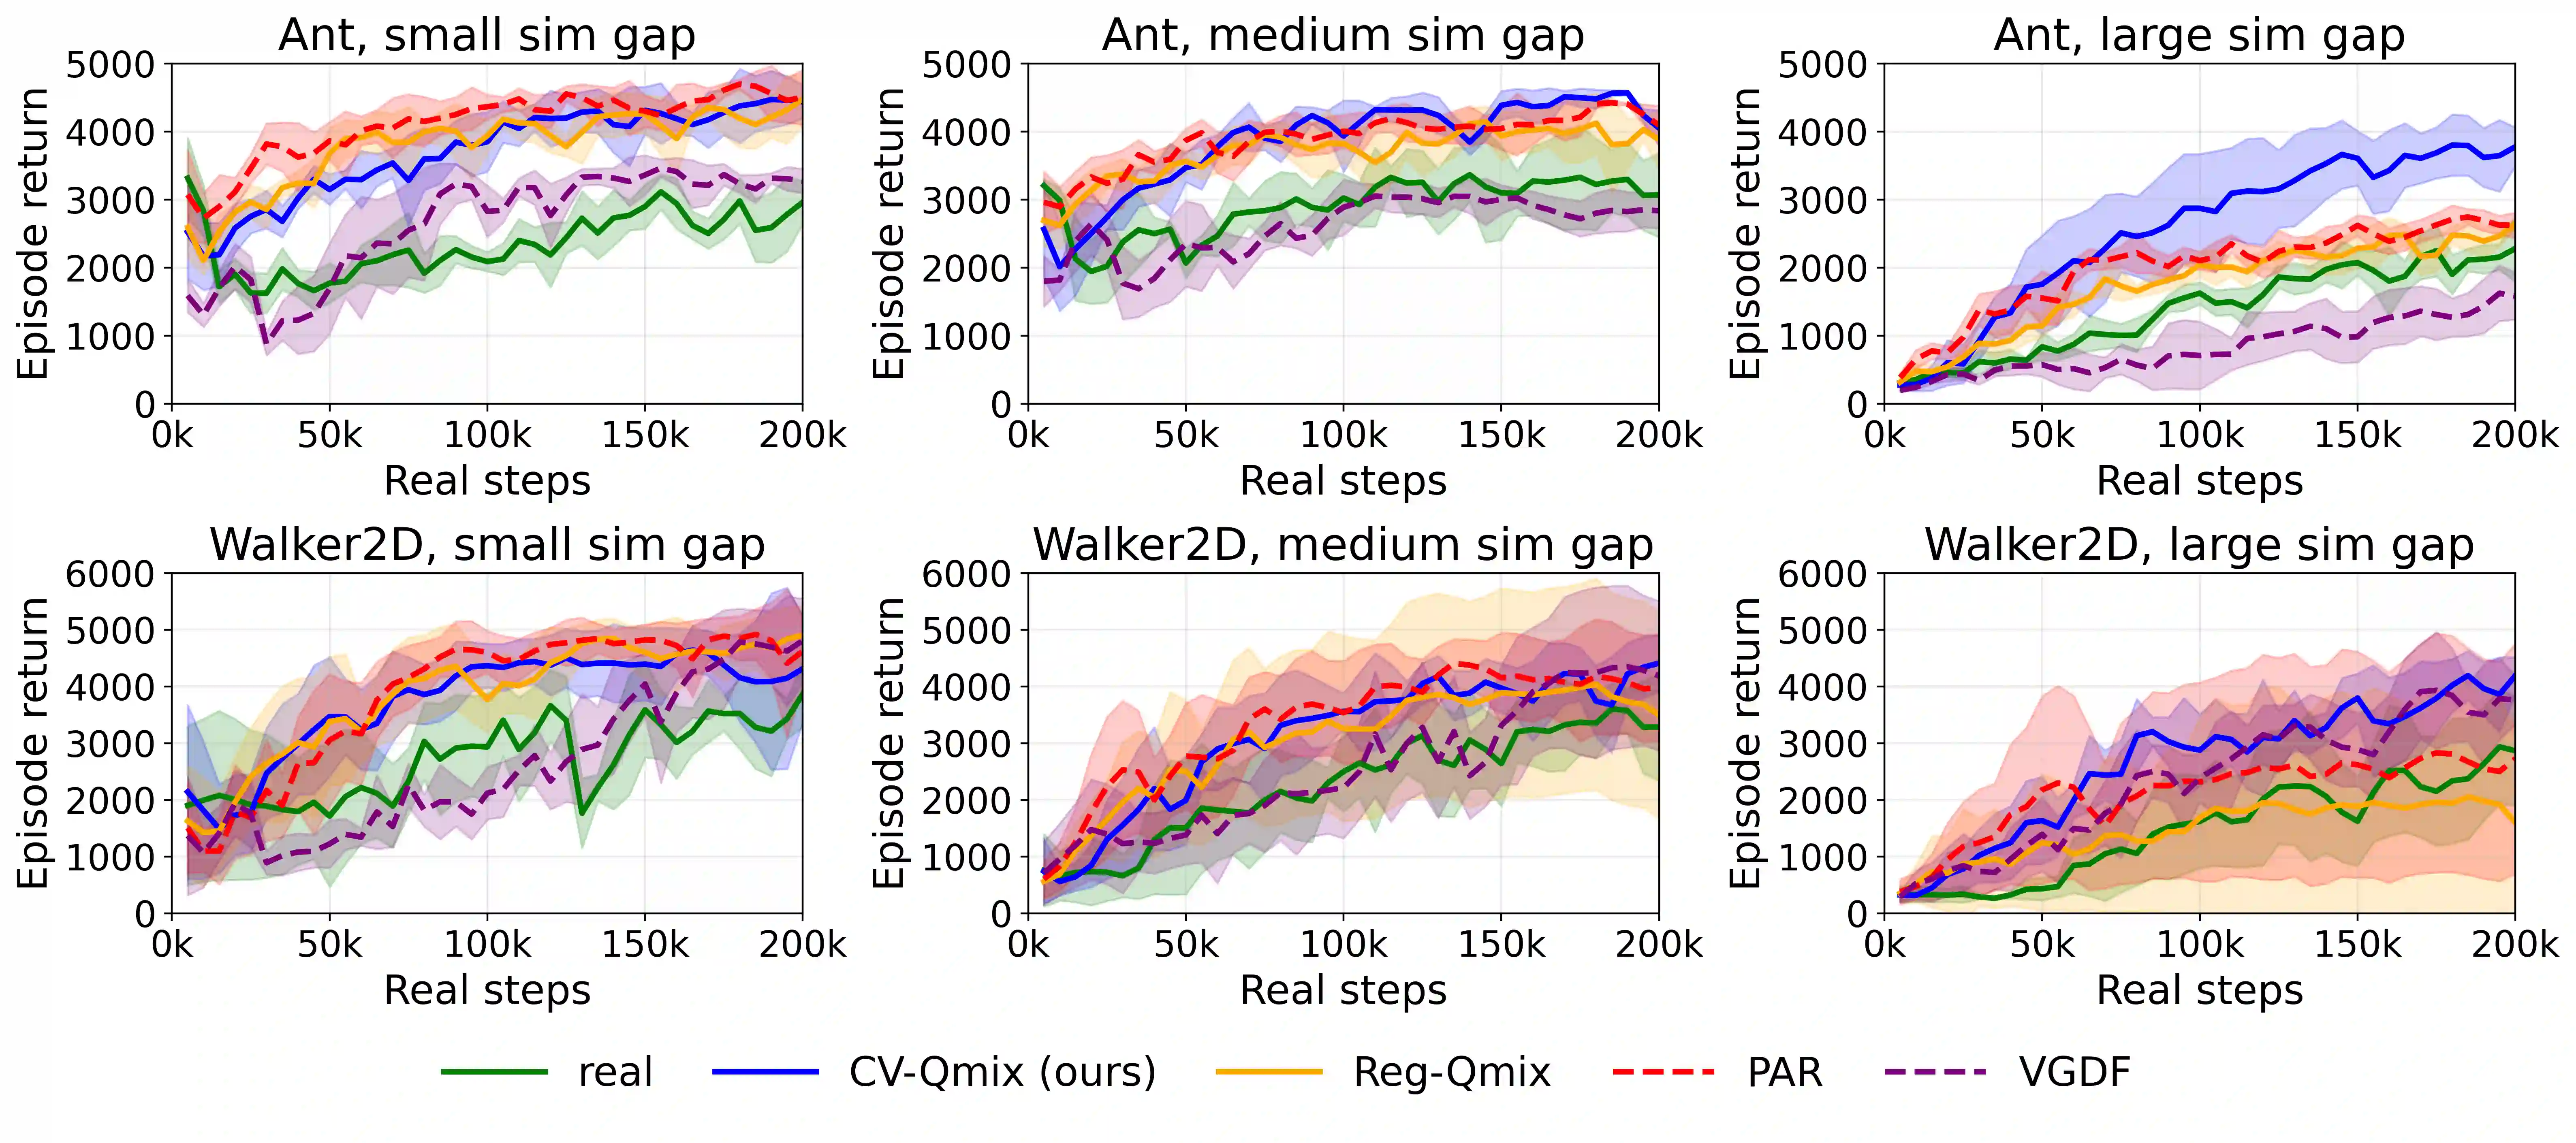
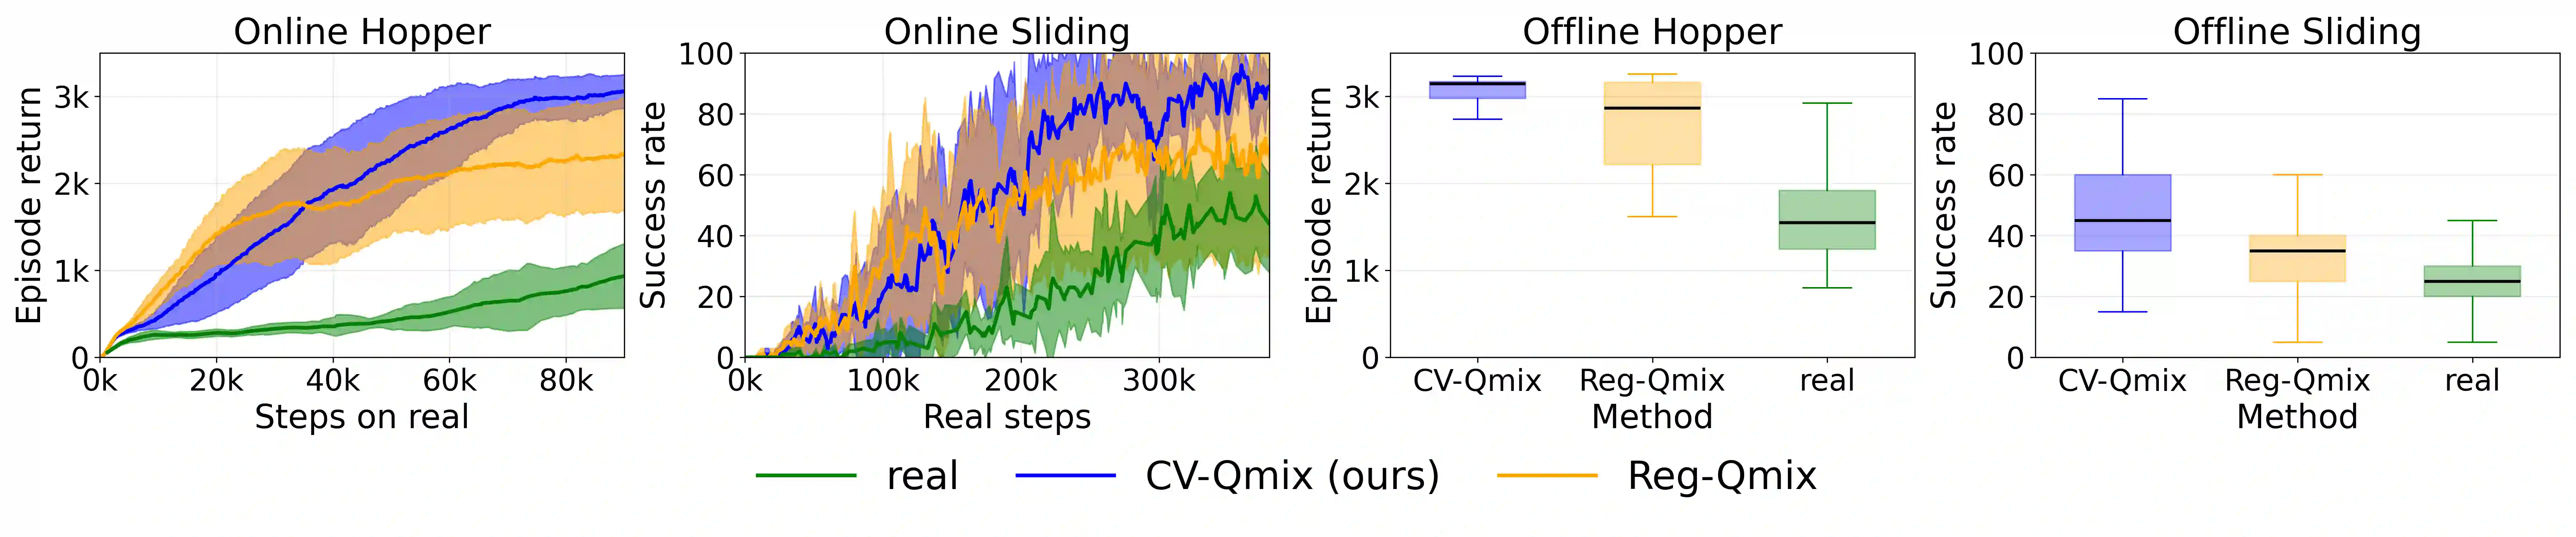
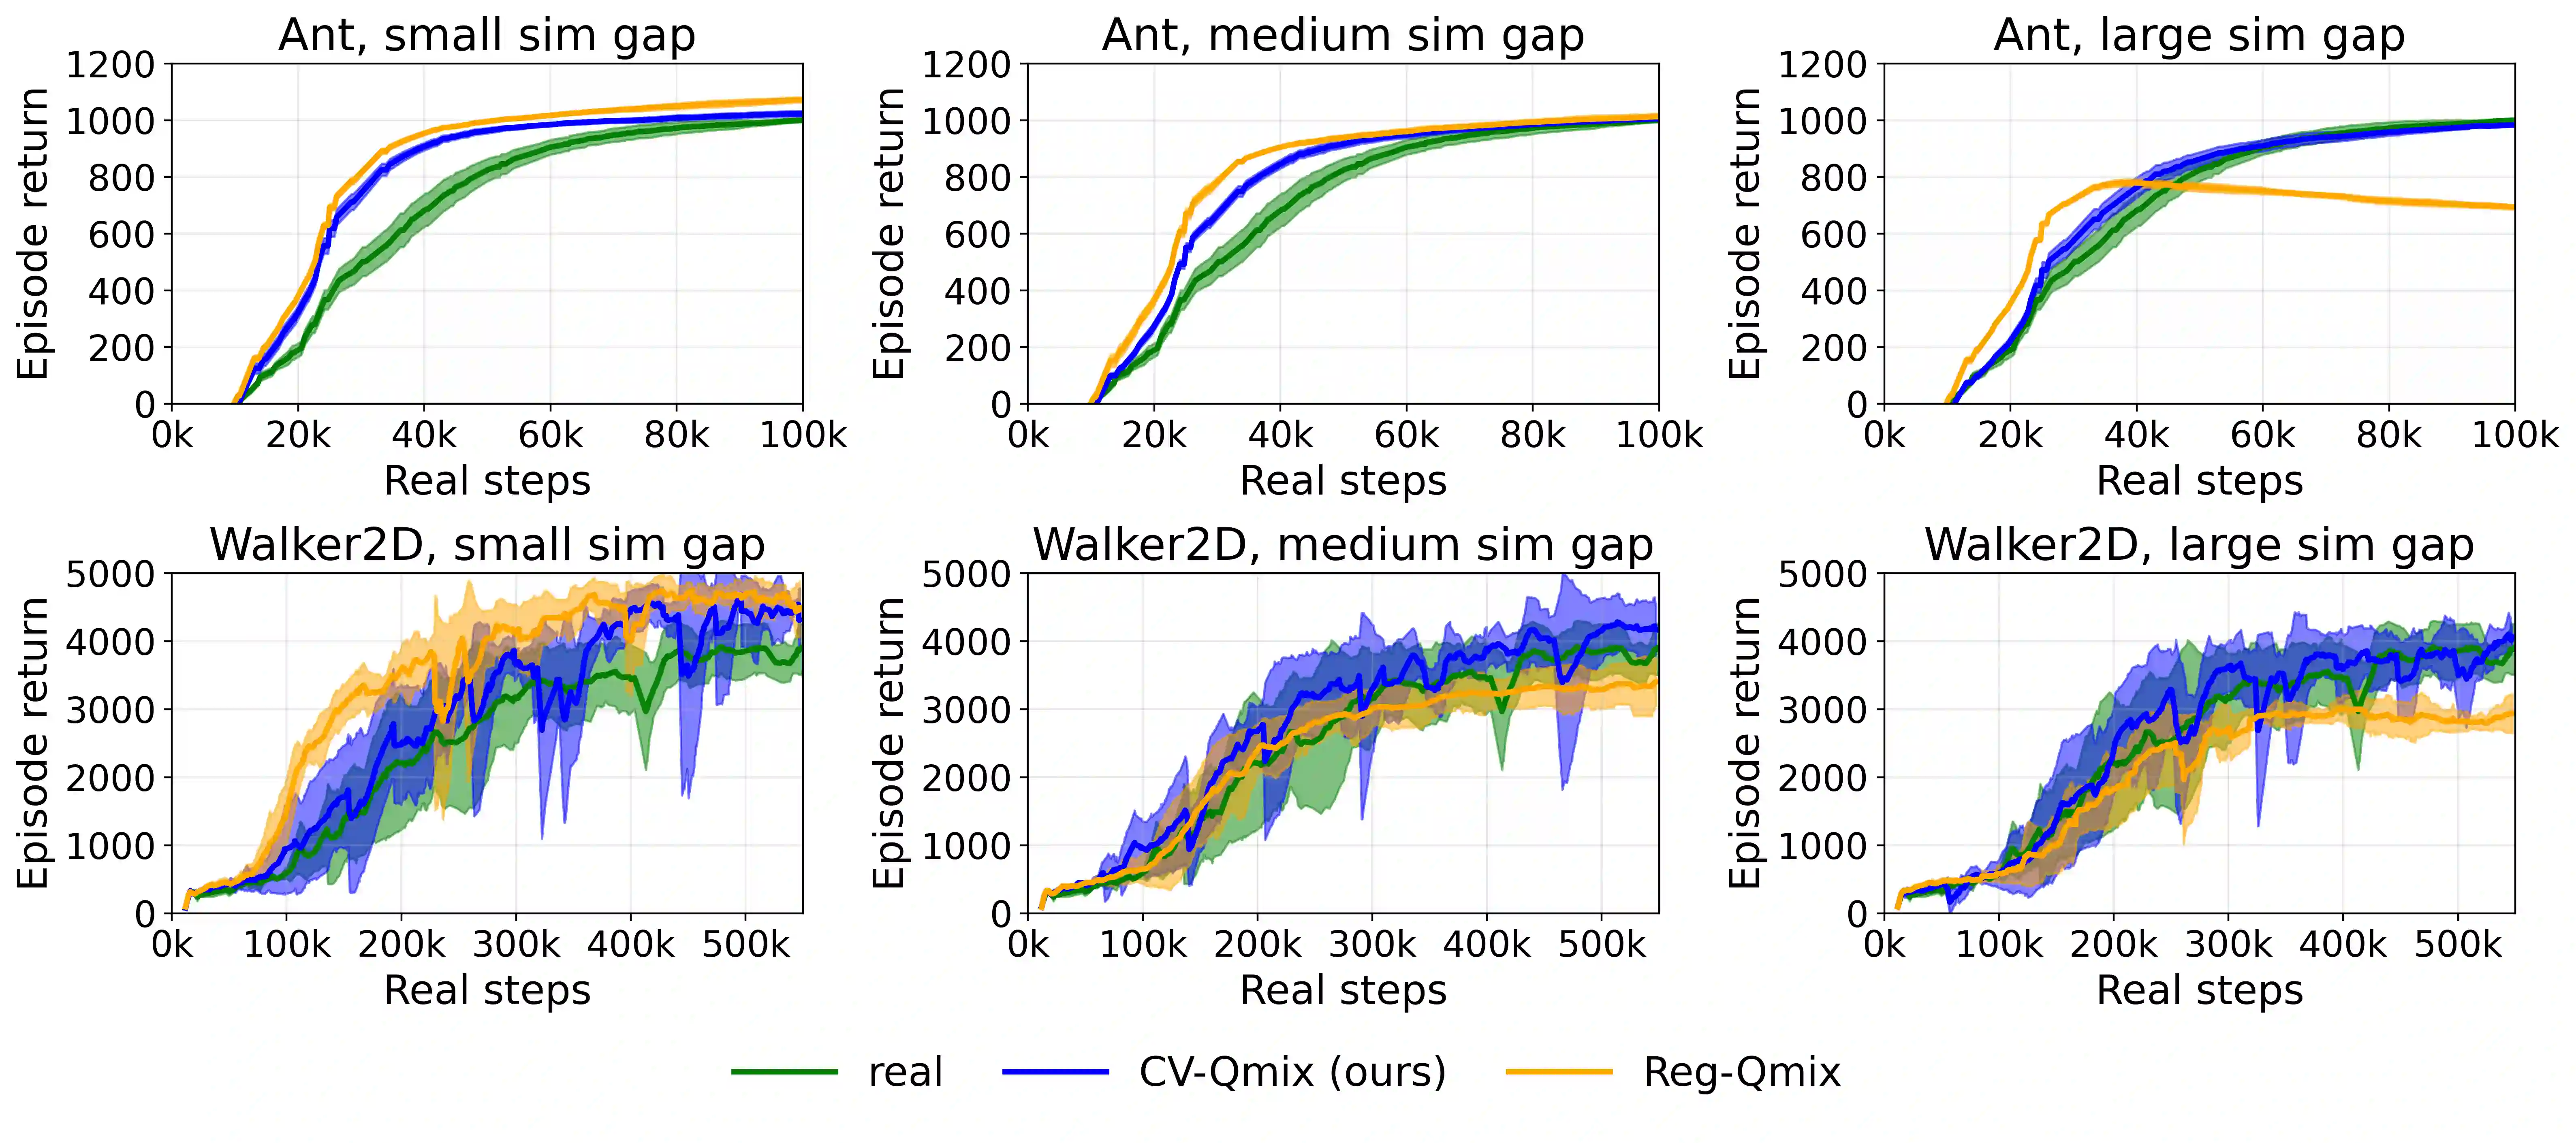
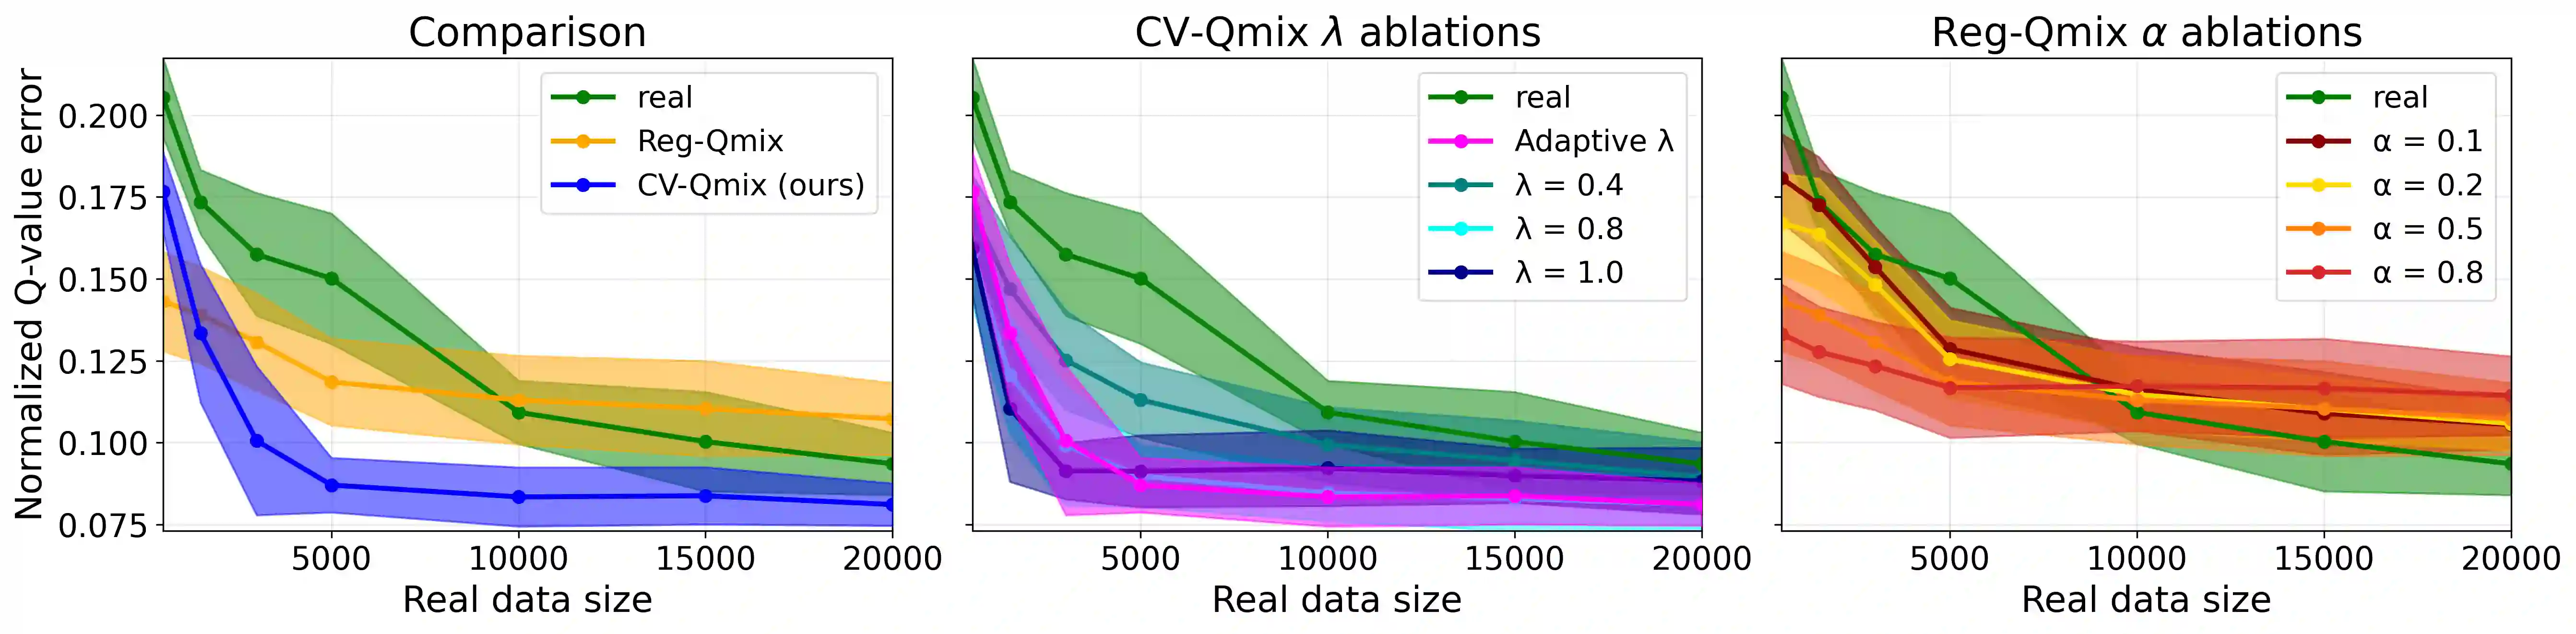
Reinforcement Learning (RL) algorithms often rely on data collected from a target environment, which can be expensive and noisy. Although simulators can generate large amounts of additional data, standard simulation mixing approaches, which directly combine simulated and real experience, can degrade performance due to simulator inaccuracies, especially when they bias the solution away from the optimal policy. We propose a conservative simulation-aided learning method based on control variates, where simulated data is used solely to reduce variance in the learning process rather than directly shaping the learning target. We develop our approach for Policy-Evaluation, which is a fundamental building block of RL algorithms. Then we combine it within the actor-critic framework towards policy improvement, as well as extend it towards offline RL scenarios. Experiments on multiple MuJoCo benchmark tasks demonstrate improvements over standard simulation mixing approaches, highlighting control variates as an effective tool for simulation-aided reinforcement learning.


翻译:暂无翻译
0
下载
关闭预览

相关内容

基于通信的多智能体强化学习进展综述
专知会员服务
114+阅读 · 2022年11月12日
【牛津大学博士论文】元强化学习的快速自适应,217页pdf
专知会员服务
106+阅读 · 2022年9月19日
【MIT博士论文】数据高效强化学习,176页pdf
专知会员服务
90+阅读 · 2022年7月11日
专知会员服务
136+阅读 · 2021年3月13日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
「基于通信的多智能体强化学习」 进展综述
基于模型的强化学习综述
专知
42+阅读 · 2022年7月13日
【MIT博士论文】数据高效强化学习,176页pdf
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Relational Deep Reinforcement Learning
Arxiv
10+阅读 · 2018年6月28日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
18+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
7+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
10+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
8+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
5+阅读 · 11月6日
相关VIP内容
基于通信的多智能体强化学习进展综述
专知会员服务
114+阅读 · 2022年11月12日
【牛津大学博士论文】元强化学习的快速自适应,217页pdf
专知会员服务
106+阅读 · 2022年9月19日
【MIT博士论文】数据高效强化学习,176页pdf
专知会员服务
90+阅读 · 2022年7月11日
专知会员服务
136+阅读 · 2021年3月13日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
相关基金
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
23+阅读 · 2009年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员