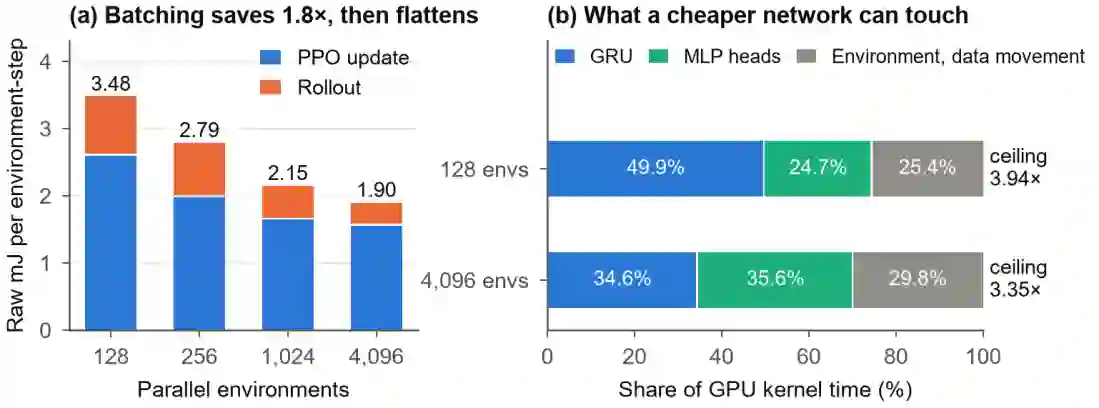
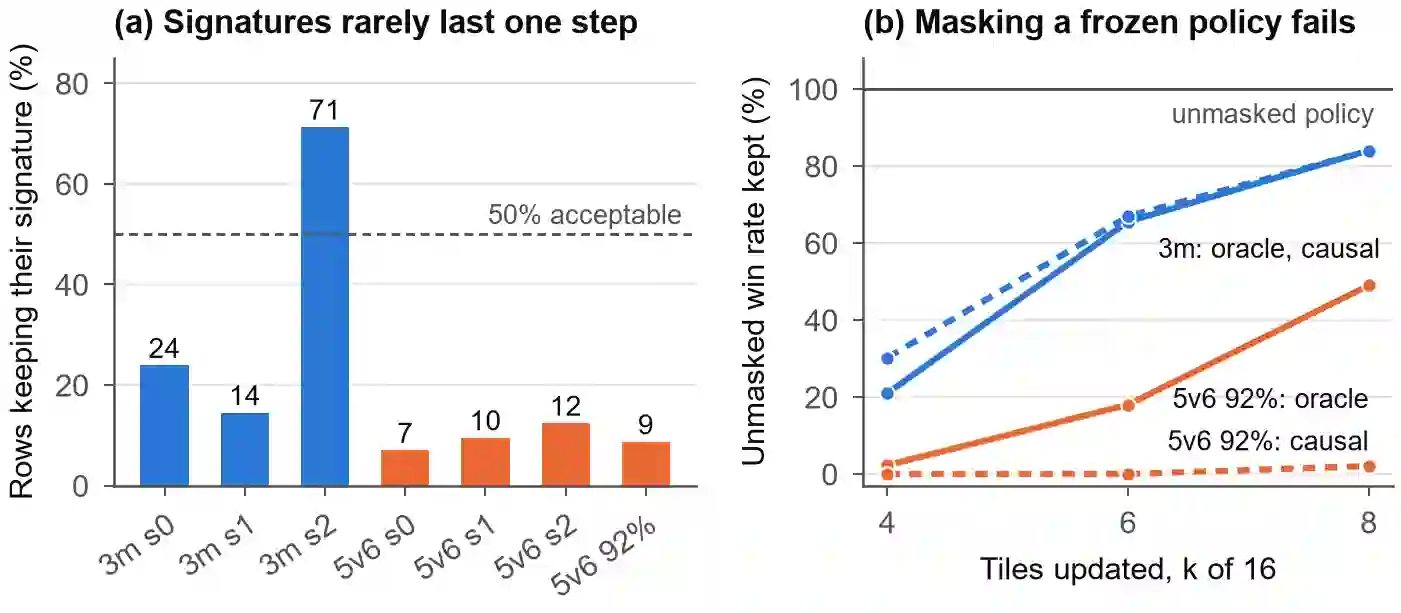
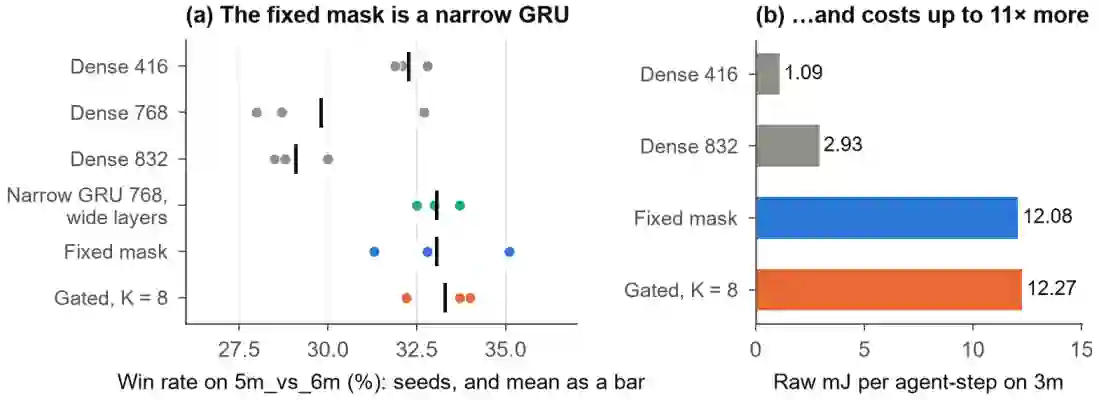
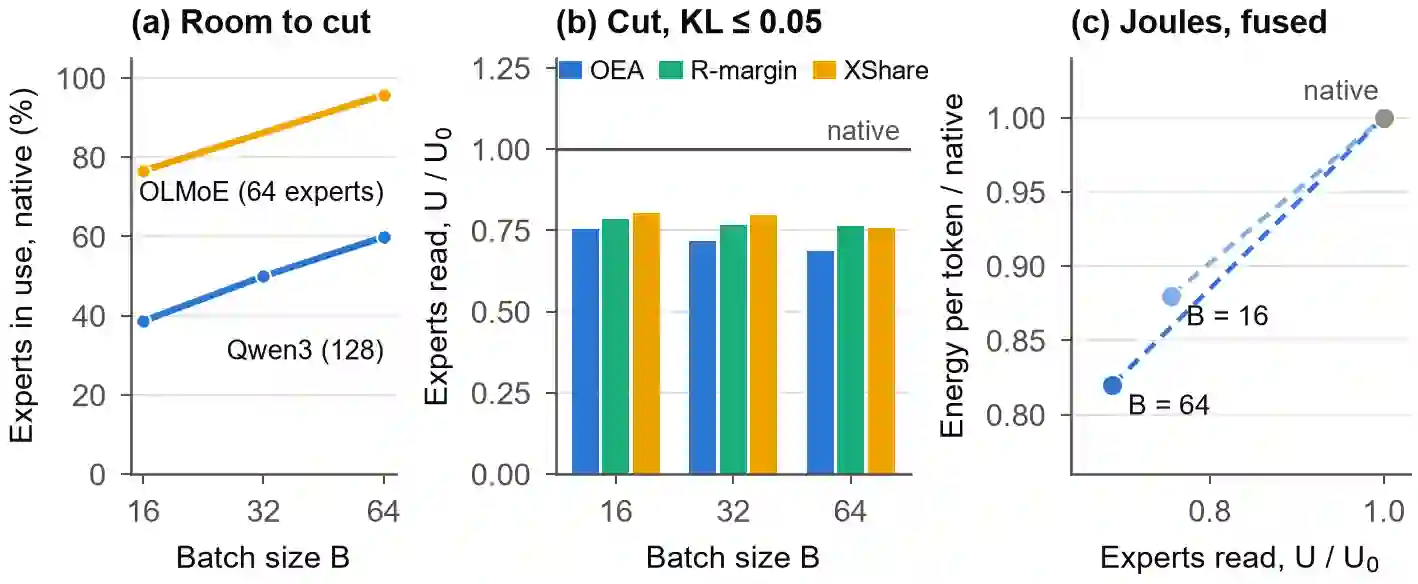
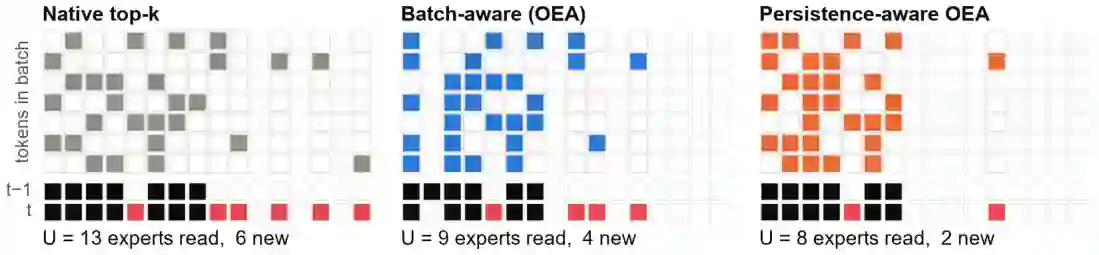
Energy claims for efficient neural networks are often inferred from operation counts. We report direct GPU energy measurements on two workloads that batch very differently, recurrent policies in GPU-vectorised multi-agent reinforcement learning (MARL) and mixture-of-experts (MoE) language models, and ask one question of both: can the rows of a batch be made to share computation, across the batch and over time, at a measured saving? On recurrent policies the answer so far is no. Shared activity patterns exist but rarely last one step, masking a frozen policy fails, and trained-in masks succeed only because a fixed mask is equivalent to a narrow GRU, at 11x the energy of a small dense policy in our implementation. Test-time steering adds nothing beyond re-picking on either workload. On MoE models the answer is yes, and granularity decides how much: on Qwen3-30B-A3B, batch-aware routing reads 25-31% fewer expert weights within KL 0.05, with benchmark changes within noise at 500 items, and uses 12-18% less energy per token on a fused forward. We also introduce persistence-aware OEA, a one-parameter rule that keeps the batch-aware cut with about 40% fewer new experts per step than native routing at batch 32-64, though its energy has not yet been measured. These are pilot measurements on one GPU type, and we state their limits.


翻译:暂无翻译
0
下载
关闭预览

相关内容

中文版 | 集中式与分布式多智能体AI协调策略
专知会员服务
24+阅读 · 2025年5月8日
《面向边缘AI应用的高性能高能效架构探索》156页
专知会员服务
37+阅读 · 2025年4月12日
能耗优化的神经网络轻量化方法研究进展
专知会员服务
27+阅读 · 2023年1月29日
面向多GPU的图神经网络训练加速
专知会员服务
24+阅读 · 2023年1月19日
盘点来自工业界的GPU共享方案
计算机视觉life
12+阅读 · 2021年9月2日
谷歌EfficientNet缩放模型,PyTorch实现登热榜
机器学习算法与Python学习
11+阅读 · 2019年6月4日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
深度学习中Attention Mechanism详细介绍:原理、分类及应用
深度学习与NLP
10+阅读 · 2019年2月18日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
论文 | 深度学习实现目标跟踪
七月在线实验室
48+阅读 · 2017年12月8日
IJCAI | Cascade Dynamics Modeling with Attention-based RNN
KingsGarden
13+阅读 · 2017年7月16日
详述DeepMind wavenet原理及其TensorFlow实现
深度学习每日摘要
12+阅读 · 2017年6月26日
国家自然科学基金
0+阅读 · 2017年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
18+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
7+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
10+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
8+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
5+阅读 · 11月6日
相关VIP内容
中文版 | 集中式与分布式多智能体AI协调策略
专知会员服务
24+阅读 · 2025年5月8日
《面向边缘AI应用的高性能高能效架构探索》156页
专知会员服务
37+阅读 · 2025年4月12日
能耗优化的神经网络轻量化方法研究进展
专知会员服务
27+阅读 · 2023年1月29日
面向多GPU的图神经网络训练加速
专知会员服务
24+阅读 · 2023年1月19日
相关资讯
盘点来自工业界的GPU共享方案
计算机视觉life
12+阅读 · 2021年9月2日
谷歌EfficientNet缩放模型,PyTorch实现登热榜
机器学习算法与Python学习
11+阅读 · 2019年6月4日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
深度学习中Attention Mechanism详细介绍:原理、分类及应用
深度学习与NLP
10+阅读 · 2019年2月18日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
论文 | 深度学习实现目标跟踪
七月在线实验室
48+阅读 · 2017年12月8日
IJCAI | Cascade Dynamics Modeling with Attention-based RNN
KingsGarden
13+阅读 · 2017年7月16日
详述DeepMind wavenet原理及其TensorFlow实现
深度学习每日摘要
12+阅读 · 2017年6月26日
相关基金
国家自然科学基金
0+阅读 · 2017年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员