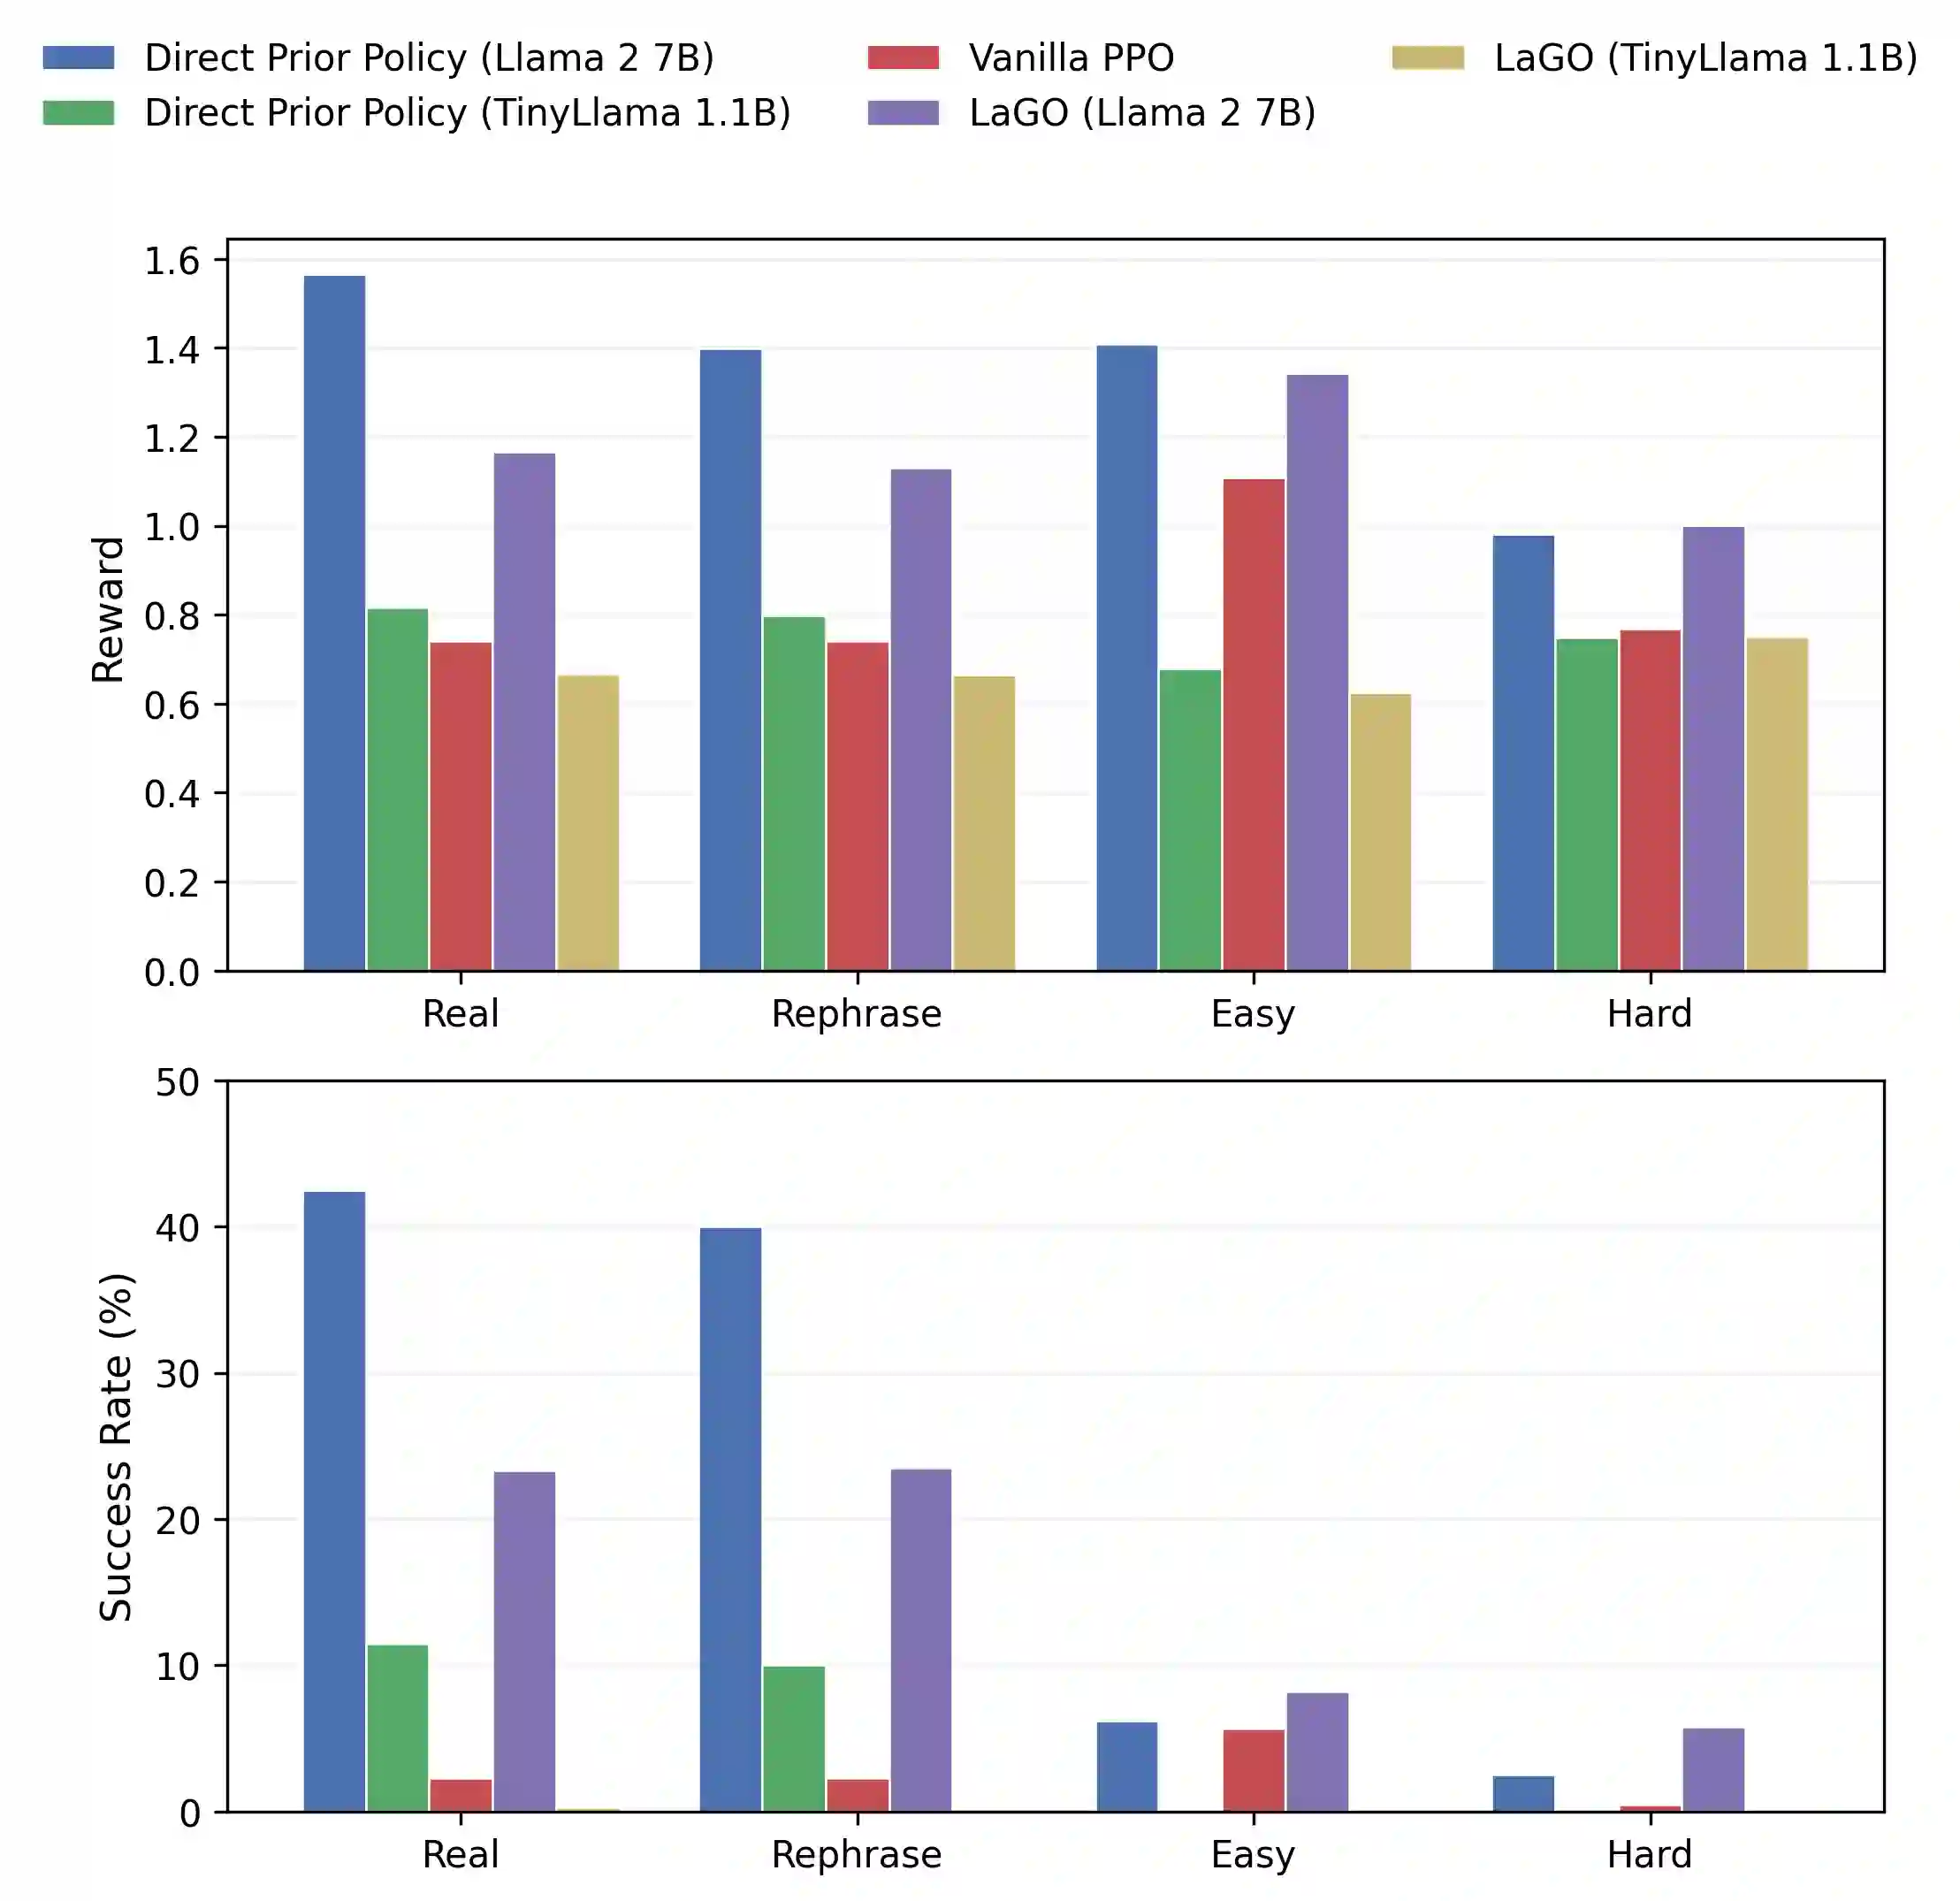
Large language models (LLMs) have shown strong potential for planning and sequential decision-making, but prior work often relies on using them as direct controllers, which requires precise action generation and can be unreliable in practice. This paper proposes Latent Action Guidance for Online Reinforcement Learning (LaGO), a framework that uses a pretrained LLM as a latent action prior to softly guide online policy optimization, rather than treating the LLM as an explicit planner or controller. Experiments on both a discrete-control benchmark, CLEVR-Robot, and a continuous-control benchmark, Meta-World, demonstrate that LaGO consistently improves both reward and success rate over Vanilla PPO. In particular, LaGO increases the average success rate from 15.1% to 27.2% on CLEVR-Robot and from 2.7% to 15.2% on Meta-World. Our analysis further shows that stronger pretrained LLMs provide more effective guidance, suggesting that LLM knowledge can improve planning and online decision-making.


翻译:暂无翻译

0
下载
关闭预览

相关内容

微软最新《检索增强生成(RAG)》综述
专知会员服务
58+阅读 · 2024年9月24日
Llama-3-SynE:实现有效且高效的大语言模型持续预训练
专知会员服务
36+阅读 · 2024年7月30日
基于大语言模型的复杂任务自主规划处理框架
专知会员服务
103+阅读 · 2024年4月12日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
【MIT博士论文】数据高效强化学习,176页pdf
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
NLP-Progress记录NLP最新数据集、论文和代码: 助你紧跟NLP前沿
中国人工智能学会
12+阅读 · 2018年11月15日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
51+阅读 · 2014年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
4+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
25+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
10+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
专知会员服务
12+阅读 · 11月8日
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
12+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
10+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
7+阅读 · 11月6日
相关VIP内容
微软最新《检索增强生成(RAG)》综述
专知会员服务
58+阅读 · 2024年9月24日
Llama-3-SynE:实现有效且高效的大语言模型持续预训练
专知会员服务
36+阅读 · 2024年7月30日
基于大语言模型的复杂任务自主规划处理框架
专知会员服务
103+阅读 · 2024年4月12日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关资讯
【MIT博士论文】数据高效强化学习,176页pdf
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
NLP-Progress记录NLP最新数据集、论文和代码: 助你紧跟NLP前沿
中国人工智能学会
12+阅读 · 2018年11月15日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
相关基金
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
7+阅读 · 2015年12月31日
国家自然科学基金
51+阅读 · 2014年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
4+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
12+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员