

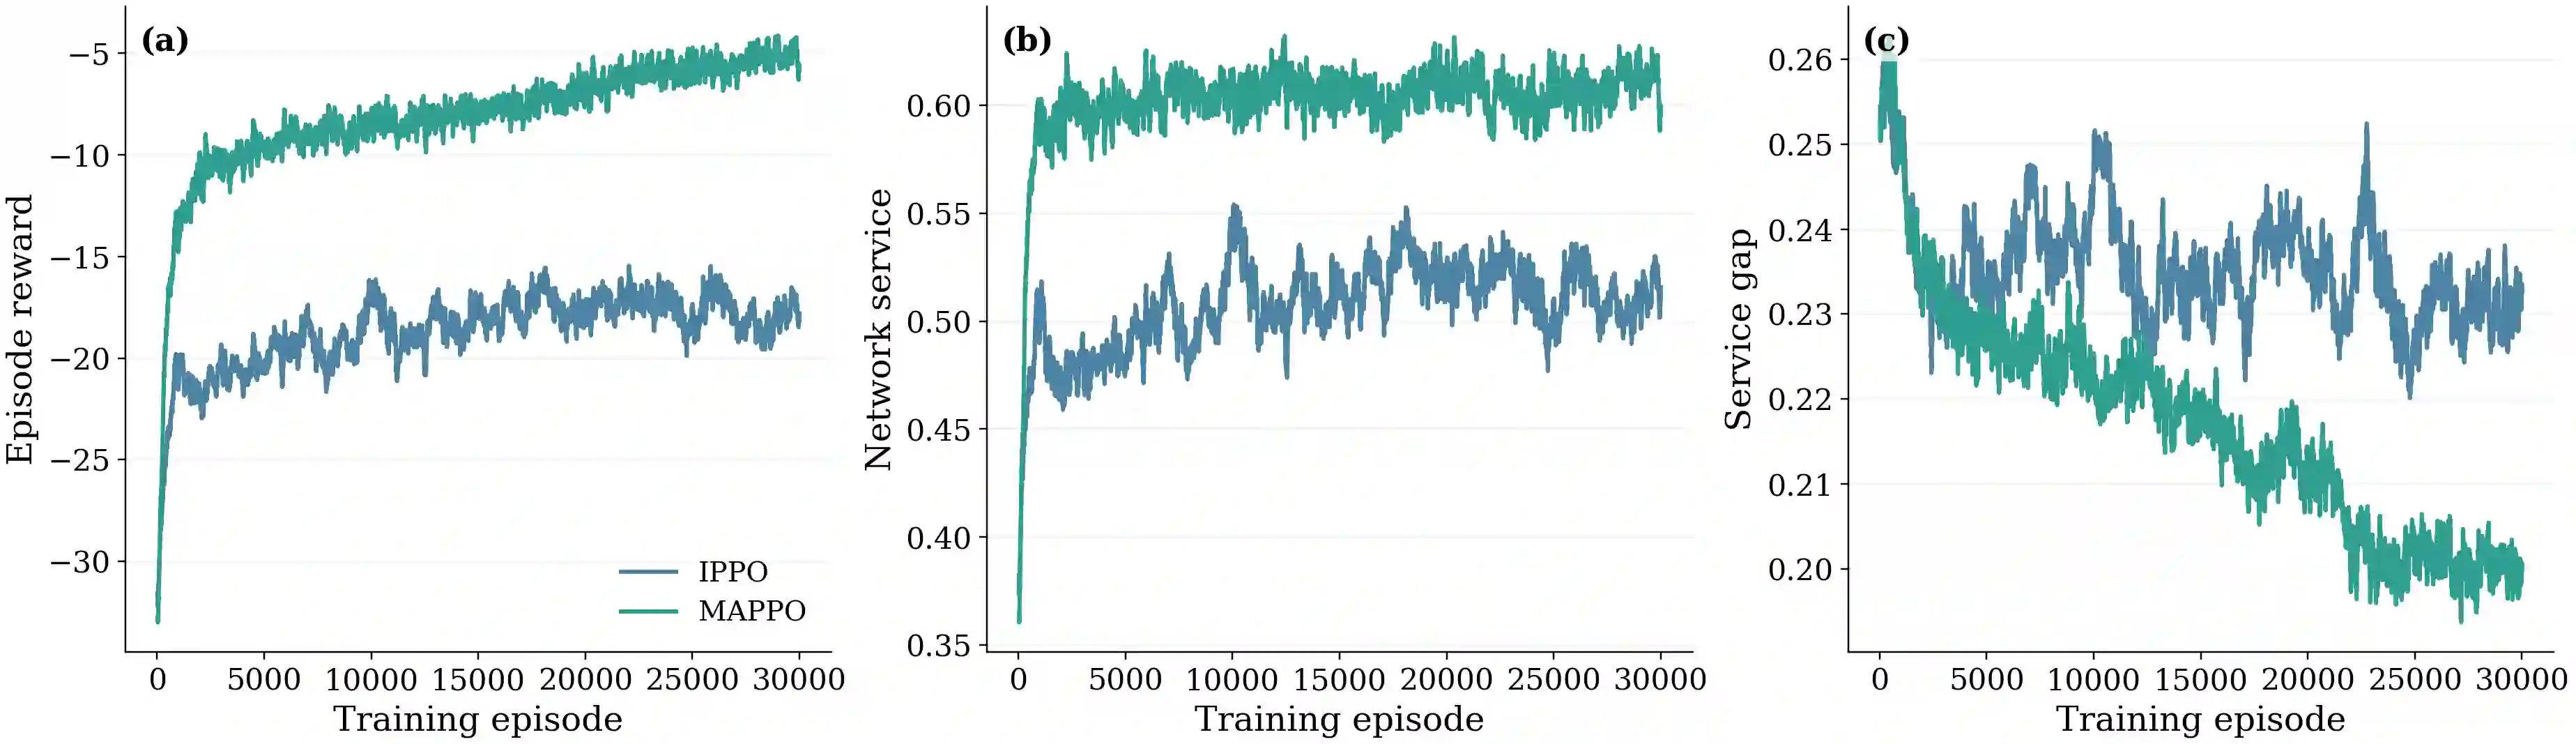
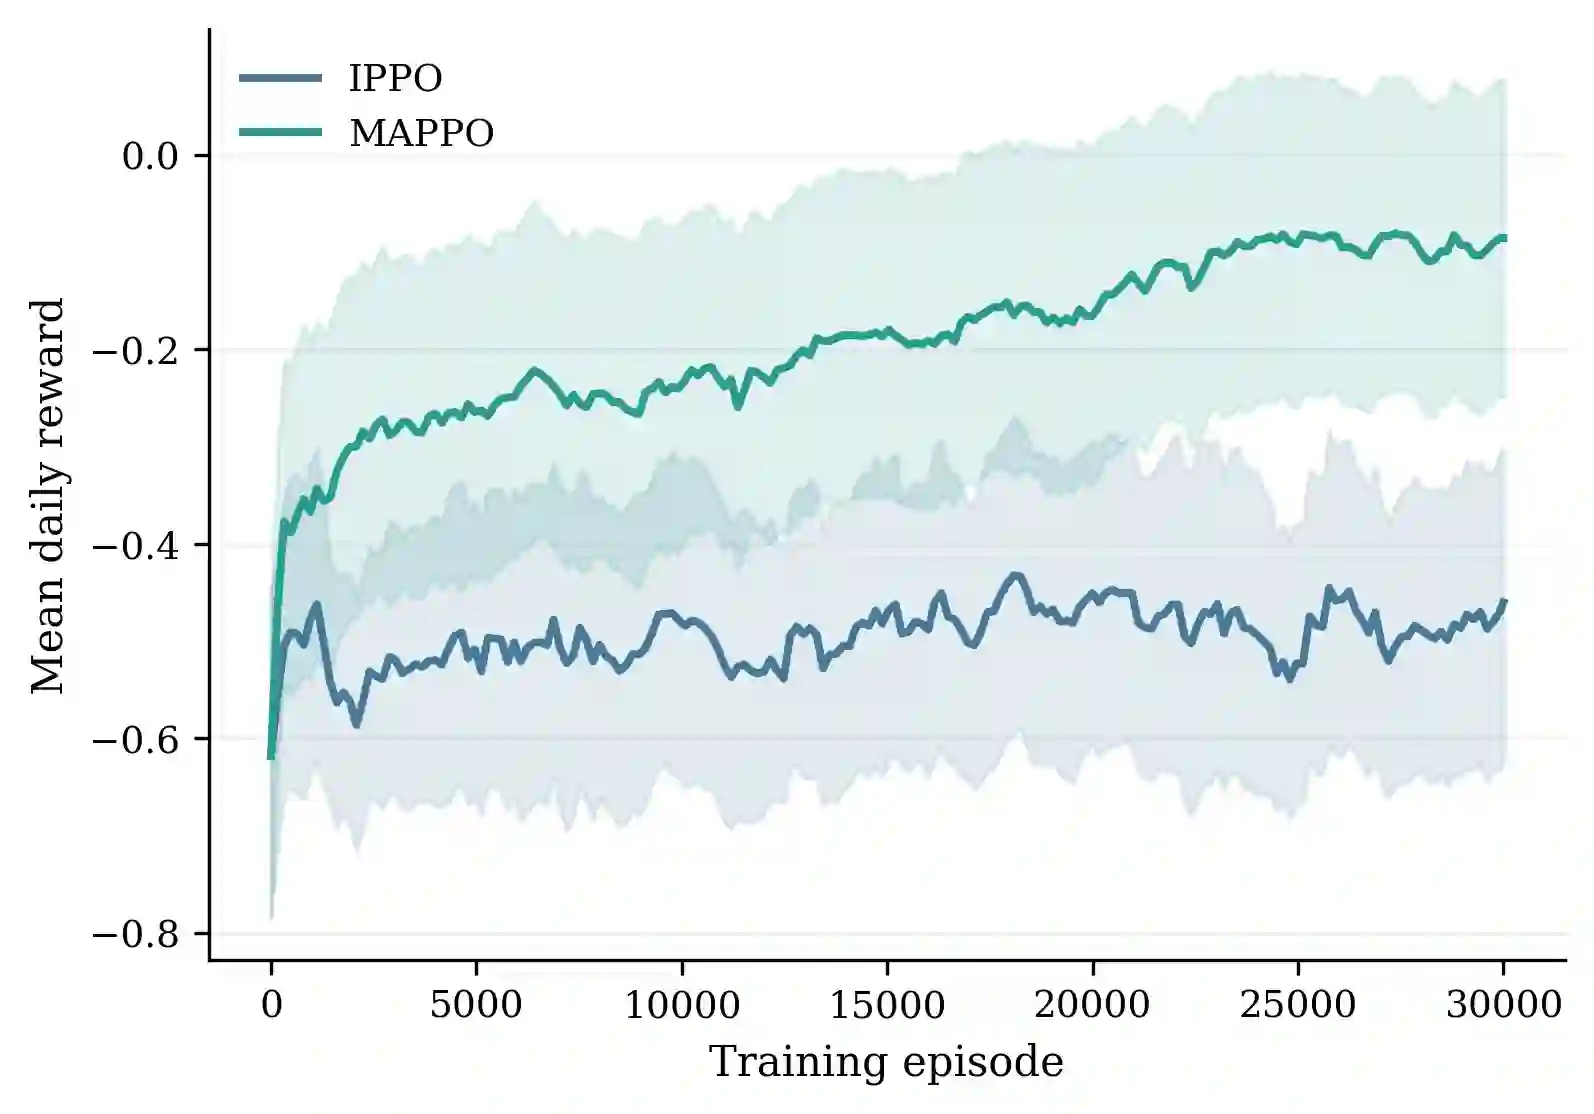
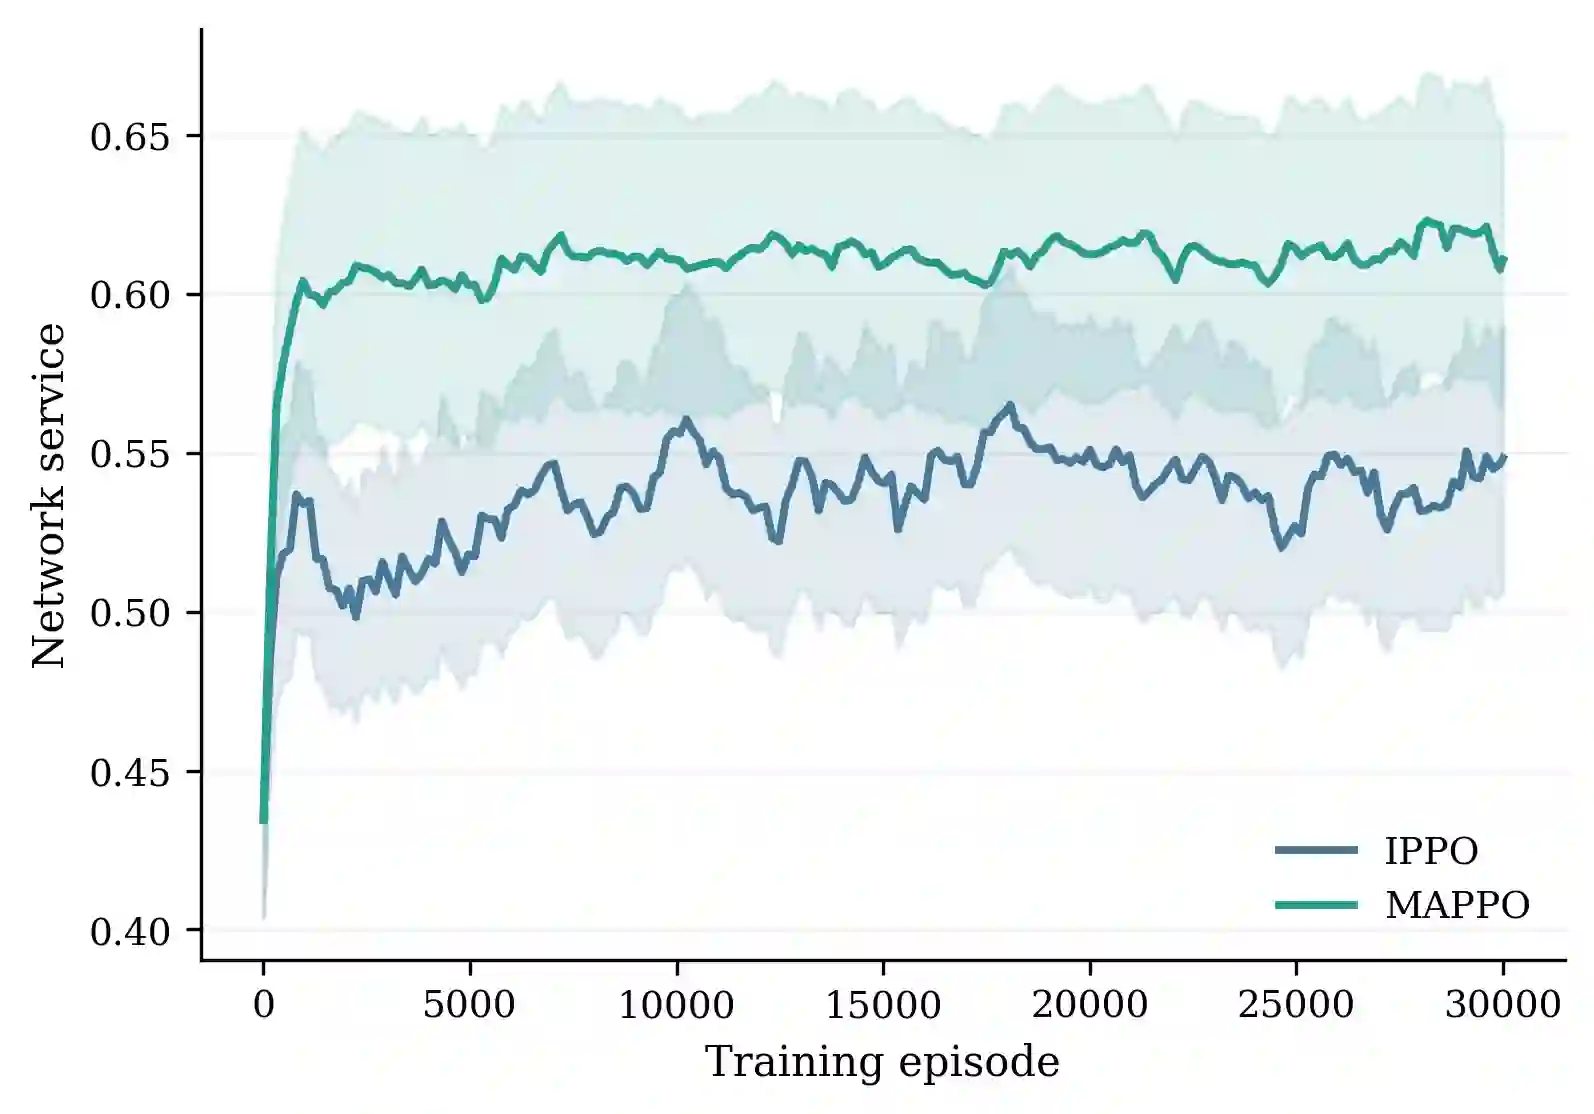
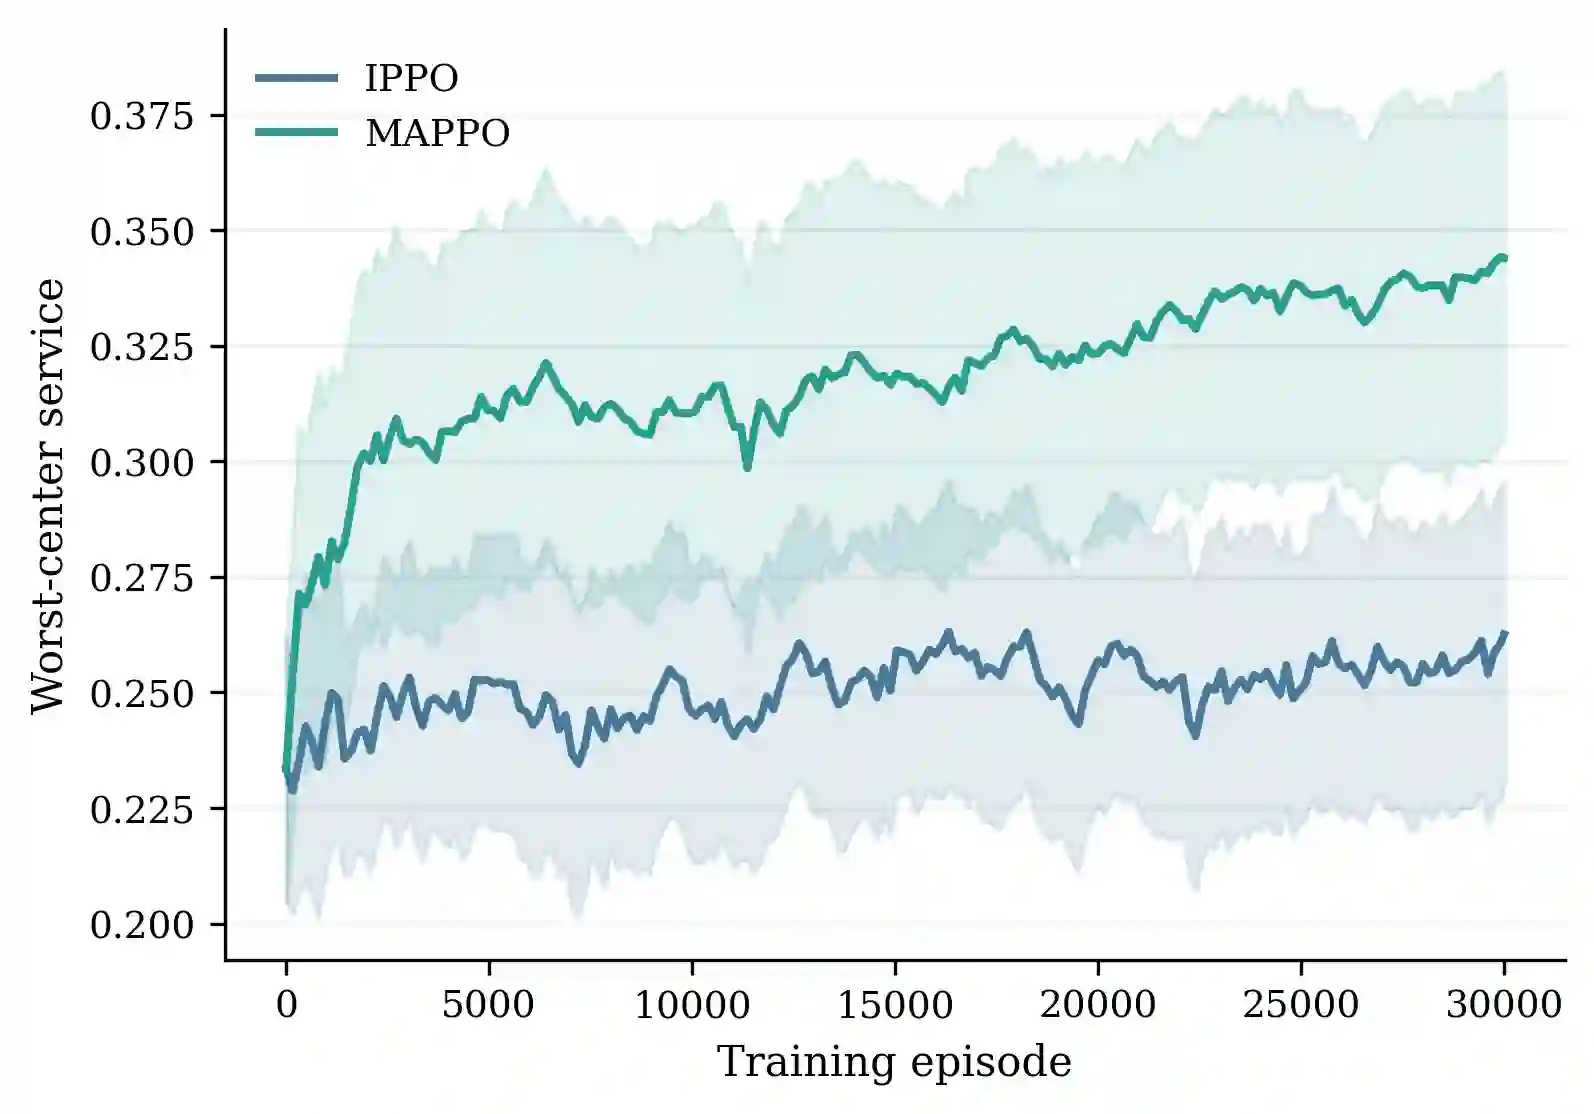
Emergency management assistance programs, such as relief distribution, are essential for delivering necessary supplies to affected communities. However, these programs operate in a decentralized network of local centers that face uncertain local demand and supply dynamics, resulting in inconsistent avail- ability of local services. Redistribution of supplies among these local centers reduces these imbalances, but the centers often make decisions independently, with limited information and disrupted transportation. This study develops CoRe-MARL, a cooperative multi-agent reinforcement learning (MARL) framework, by formulating a decentralized partially observable Markov decision process (Dec-POMDP). We treat each center as an agent that learns a redistribution policy to improve the service in the worst-case region and reduce the service gap across regions while protecting network-wide service. We incorporate a recurrent network that captures evolving supply and demand dynamics without direct observation, while multi-agent proximal policy optimization (MAPPO) enables centralized training and decentralized execution (CTDE). We evaluate the framework in a simulated environment with diverse trajectories, where exact dynamics are not observed by actors and the MAPPO critic. We compare the recurrent MAPPO with the recurrent independent PPO (IPPO) and a local only heuristic, and find that MAPPO reduces the service gap across local centers and enhances service for the worst-served center while maintaining competitive network-wide service. The recurrent MAPPO also shows consistent performance across diverse trajectory patterns, demonstrating its ability to adapt to evolving dynamics. The findings demonstrate the capability of cooperative learning for decentralized redistribution and improving equitable service under uncertain and evolving dynamics.
翻译:暂无翻译


相关内容





 微信扫码咨询专知VIP会员