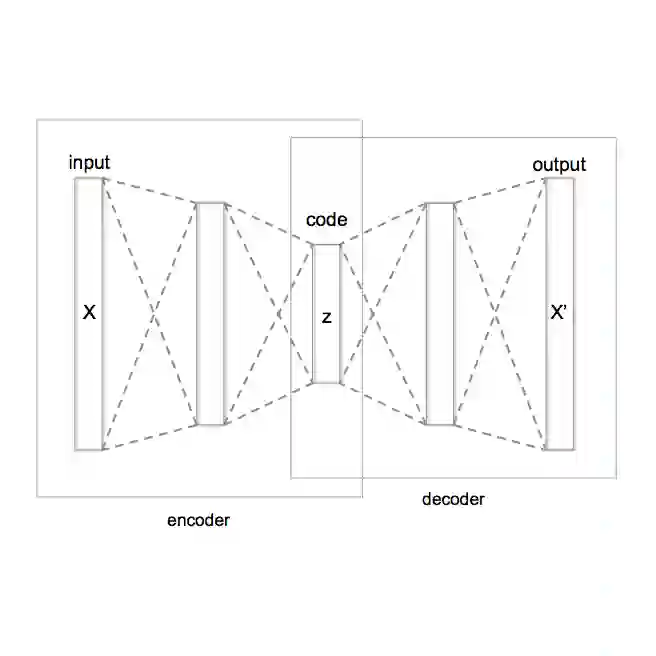
The number of attention heads in a transformer is usually set by convention or grid search. We test a simple heuristic for setting it in advance: estimate the intrinsic dimension of token representations without labels, and use roughly that many heads. We estimate intrinsic dimension with a nested-dropout VAE trained on DistilBERT embeddings of WikiText-2, choosing the KL weight at the knee of the VAE's rate-distortion curve rather than by hand. This gives $k^*=9.2$ (95% CI [8.6, 9.8]). In a small 4-layer transformer trained from scratch, 10 heads and 32 heads are statistically equivalent on SST-2 and on MRPC (paired TOST over 10 seeds, $\pm1$ point margin), with 69% fewer attention parameters for the 10-head model. Training 10 heads from the start also slightly outperforms training 32 heads and pruning to 10 (0.6 points, $p=0.008$). The evidence is narrow: two classification tasks, one small architecture, no pretrained models, and no formal link between intrinsic dimension and head count. We present the result as a practical heuristic worth testing at larger scale, not as a general principle.


翻译:暂无翻译

0
下载
关闭预览

相关内容

ICML 2026教程:用KET统一Attention与Diffusion
专知会员服务
12+阅读 · 7月10日
【ICML2024】通过动态可组合多头注意力改进Transformers
专知会员服务
21+阅读 · 2024年5月17日
【AAAI2022】锚点DETR:基于transformer检测器的查询设计
专知会员服务
13+阅读 · 2021年12月31日
一文读懂Attention机制
机器学习与推荐算法
63+阅读 · 2020年6月9日
深度学习中Attention Mechanism详细介绍:原理、分类及应用
深度学习与NLP
10+阅读 · 2019年2月18日
从Seq2seq到Attention模型到Self Attention(二)
量化投资与机器学习
23+阅读 · 2018年10月9日
从Seq2seq到Attention模型到Self Attention(一)
量化投资与机器学习
76+阅读 · 2018年10月8日
跨越注意力:Cross-Attention
我爱读PAMI
172+阅读 · 2018年6月2日
TensorFlow seq2seq中的Attention机制(续)
深度学习每日摘要
15+阅读 · 2017年11月16日
原创 | Attention Modeling for Targeted Sentiment
黑龙江大学自然语言处理实验室
25+阅读 · 2017年11月5日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Arxiv
0+阅读 · 10月13日
Talking-Heads Attention
Arxiv
15+阅读 · 2020年3月5日
VIP会员
最新内容
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
7+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
8+阅读 · 10月15日
综述|谁来改进机器人?迈向物理递归自我改进
专知会员服务
9+阅读 · 10月14日
软件定义无人机蜂群给防空带来全新压力
专知会员服务
10+阅读 · 10月13日
《半自主无人地面战车的互操作性》66页
专知会员服务
13+阅读 · 10月13日
相关VIP内容
ICML 2026教程:用KET统一Attention与Diffusion
专知会员服务
12+阅读 · 7月10日
【ICML2024】通过动态可组合多头注意力改进Transformers
专知会员服务
21+阅读 · 2024年5月17日
【AAAI2022】锚点DETR:基于transformer检测器的查询设计
专知会员服务
13+阅读 · 2021年12月31日
相关资讯
一文读懂Attention机制
机器学习与推荐算法
63+阅读 · 2020年6月9日
深度学习中Attention Mechanism详细介绍:原理、分类及应用
深度学习与NLP
10+阅读 · 2019年2月18日
从Seq2seq到Attention模型到Self Attention(二)
量化投资与机器学习
23+阅读 · 2018年10月9日
从Seq2seq到Attention模型到Self Attention(一)
量化投资与机器学习
76+阅读 · 2018年10月8日
跨越注意力:Cross-Attention
我爱读PAMI
172+阅读 · 2018年6月2日
TensorFlow seq2seq中的Attention机制(续)
深度学习每日摘要
15+阅读 · 2017年11月16日
原创 | Attention Modeling for Targeted Sentiment
黑龙江大学自然语言处理实验室
25+阅读 · 2017年11月5日
相关基金
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员