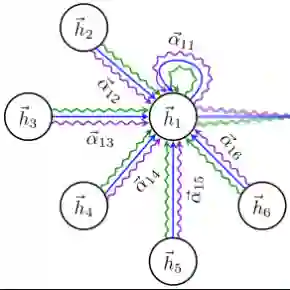
Achieving safety in autonomous driving through Multi-Agent Reinforcement Learning (MARL) is a critical yet challenging task due to non-stationarity, partial observability, and the need for effective coordination among agents. Although earlier cooperative MARL methods have aimed to improve coordination by sharing encoded state observations, we find these strategies are insufficient in safety-critical scenarios. To address this gap, we present IntNet, a novel MARL framework that enhances safety by incorporating the transmission of vehicle intent and adaptive communication scheduling into a unified end-to-end learning paradigm, jointly optimising all components for safe coordination. Central to our approach is an observation prediction module that enables agents to forecast subsequent policy outputs, which they can then share across a vehicle-to-vehicle network. Our model-free architecture employs a Graph Attention Network to process incoming messages and a scheduler component to dynamically optimise the communication graph for bandwidth efficiency. We compare IntNet against state-of-the-art communicative MARL methods in complex urban environments with both autonomous and human-operated vehicles, achieving improved coordination, lower collision rates, and reducing communication efforts by up to 60\%. Through extensive experiments, we assess the framework's learning efficiency, scalability, and the balance between information sharing and bandwidth usage for collision-free trajectories.


翻译:暂无翻译

0
下载
关闭预览

相关内容

多智能体强化学习中的稳健且高效的通信
专知会员服务
27+阅读 · 2025年11月17日
开放环境下的协作多智能体强化学习进展综述
专知会员服务
36+阅读 · 2025年1月19日
自动驾驶中的多智能体强化学习综述
专知会员服务
49+阅读 · 2024年8月20日
「博弈论视角下多智能体强化学习」研究综述
专知会员服务
186+阅读 · 2022年4月30日
【综述】多智能体强化学习算法理论研究
深度强化学习实验室
18+阅读 · 2020年9月9日
博士万字总结 || 多智能体强化学习(MARL)大总结与论文详细解读
深度强化学习实验室
10+阅读 · 2020年4月14日
多智能体强化学习(MARL)近年研究概览
PaperWeekly
39+阅读 · 2020年3月15日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
24+阅读 · 2011年12月31日
国家自然科学基金
18+阅读 · 2009年12月31日
国家自然科学基金
19+阅读 · 2008年12月31日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
11+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
4+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
7+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
4+阅读 · 11月6日
相关资讯
【综述】多智能体强化学习算法理论研究
深度强化学习实验室
18+阅读 · 2020年9月9日
博士万字总结 || 多智能体强化学习(MARL)大总结与论文详细解读
深度强化学习实验室
10+阅读 · 2020年4月14日
多智能体强化学习(MARL)近年研究概览
PaperWeekly
39+阅读 · 2020年3月15日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
相关基金
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
24+阅读 · 2011年12月31日
国家自然科学基金
18+阅读 · 2009年12月31日
国家自然科学基金
19+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员