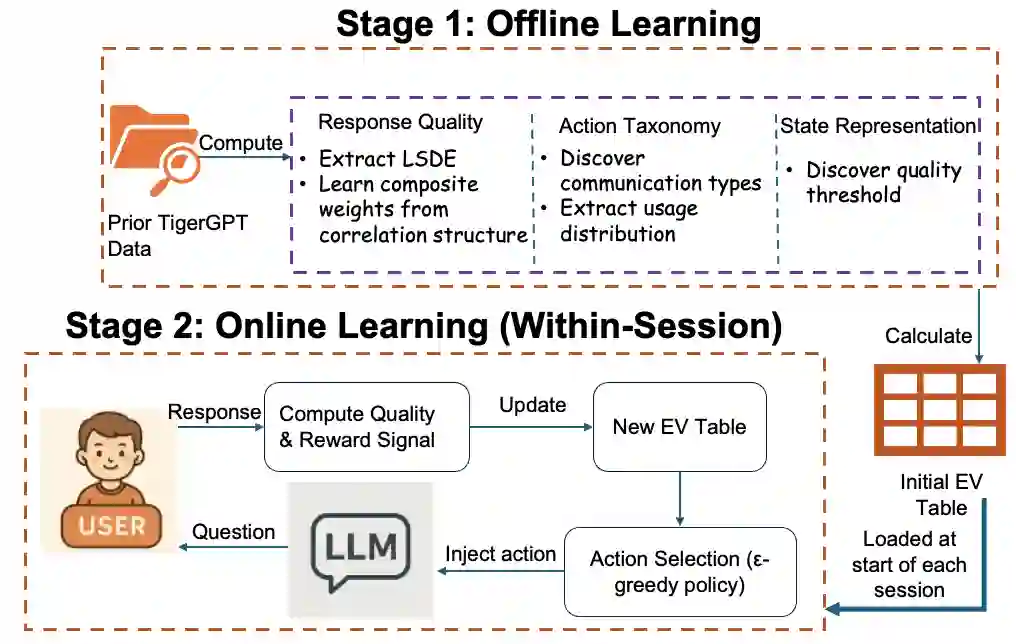
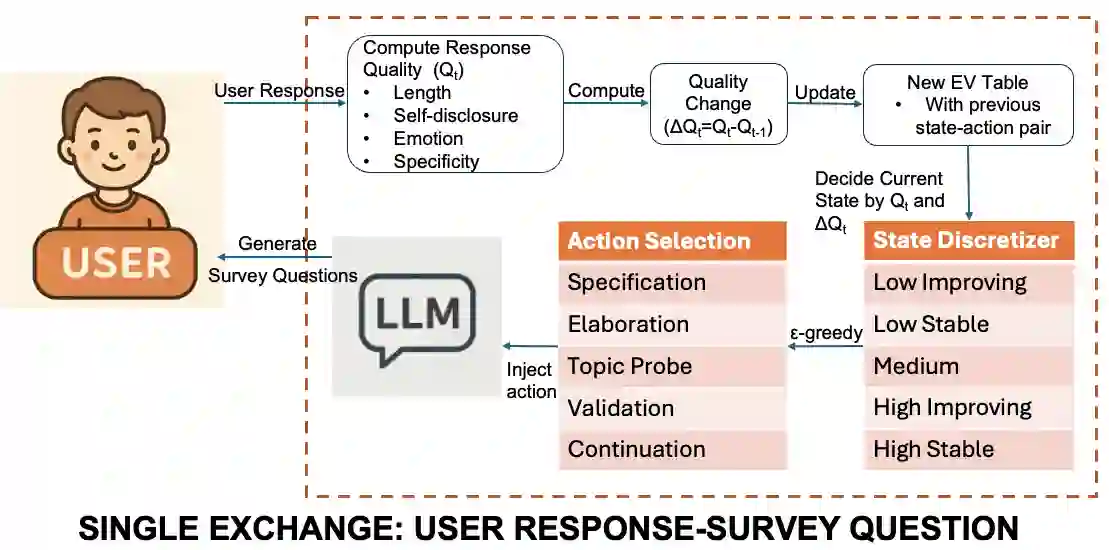
Conventional online surveys provide limited personalization, often resulting in low engagement and superficial responses. Although AI survey chatbots improve convenience, most are still reactive: they rely on fixed dialogue trees or static prompt templates and therefore cannot adapt within a session to fit individual users, which leads to generic follow-ups and weak response quality. We address these limitations with AURA (Adaptive Understanding through Reinforcement Learning for Assessment), a reinforcement learning framework for AI-driven adaptive conversational surveys. AURA quantifies response quality using a four-dimensional LSDE metric (Length, Self-disclosure, Emotion, and Specificity) and selects follow-up question types via an epsilon-greedy policy that updates the expected quality gain within each session. Initialized with priors extracted from 96 prior campus-climate conversations (467 total chatbot-user exchanges), the system balances exploration and exploitation across 10-15 dialogue exchanges, dynamically adapting to individual participants in real time. In controlled evaluations, AURA achieved a +0.076 mean gain in response quality and a statistically significant improvement over non-adaptive baselines (p=0.044, d=0.66), driven by a 63% reduction in specification prompts and a 10x increase in validation behavior. These results demonstrate that reinforcement learning can give survey chatbots improved adaptivity, transforming static questionnaires into interactive, self-improving assessment systems.


翻译:暂无翻译
0
下载
关闭预览

相关内容

「基于联邦学习的推荐系统」最新2022研究综述
专知会员服务
75+阅读 · 2022年5月21日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
南洋理工大学,深度学习推荐系统综述
专知会员服务
178+阅读 · 2019年10月14日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
国家自然科学基金
348+阅读 · 2017年12月31日
国家自然科学基金
23+阅读 · 2016年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
Arxiv
92+阅读 · 2020年2月28日
Arxiv
26+阅读 · 2018年9月21日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
22+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
9+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
专知会员服务
10+阅读 · 11月8日
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
11+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
9+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
6+阅读 · 11月6日
相关VIP内容
「基于联邦学习的推荐系统」最新2022研究综述
专知会员服务
75+阅读 · 2022年5月21日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
南洋理工大学,深度学习推荐系统综述
专知会员服务
178+阅读 · 2019年10月14日
相关基金
国家自然科学基金
348+阅读 · 2017年12月31日
国家自然科学基金
23+阅读 · 2016年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
12+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
5+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员