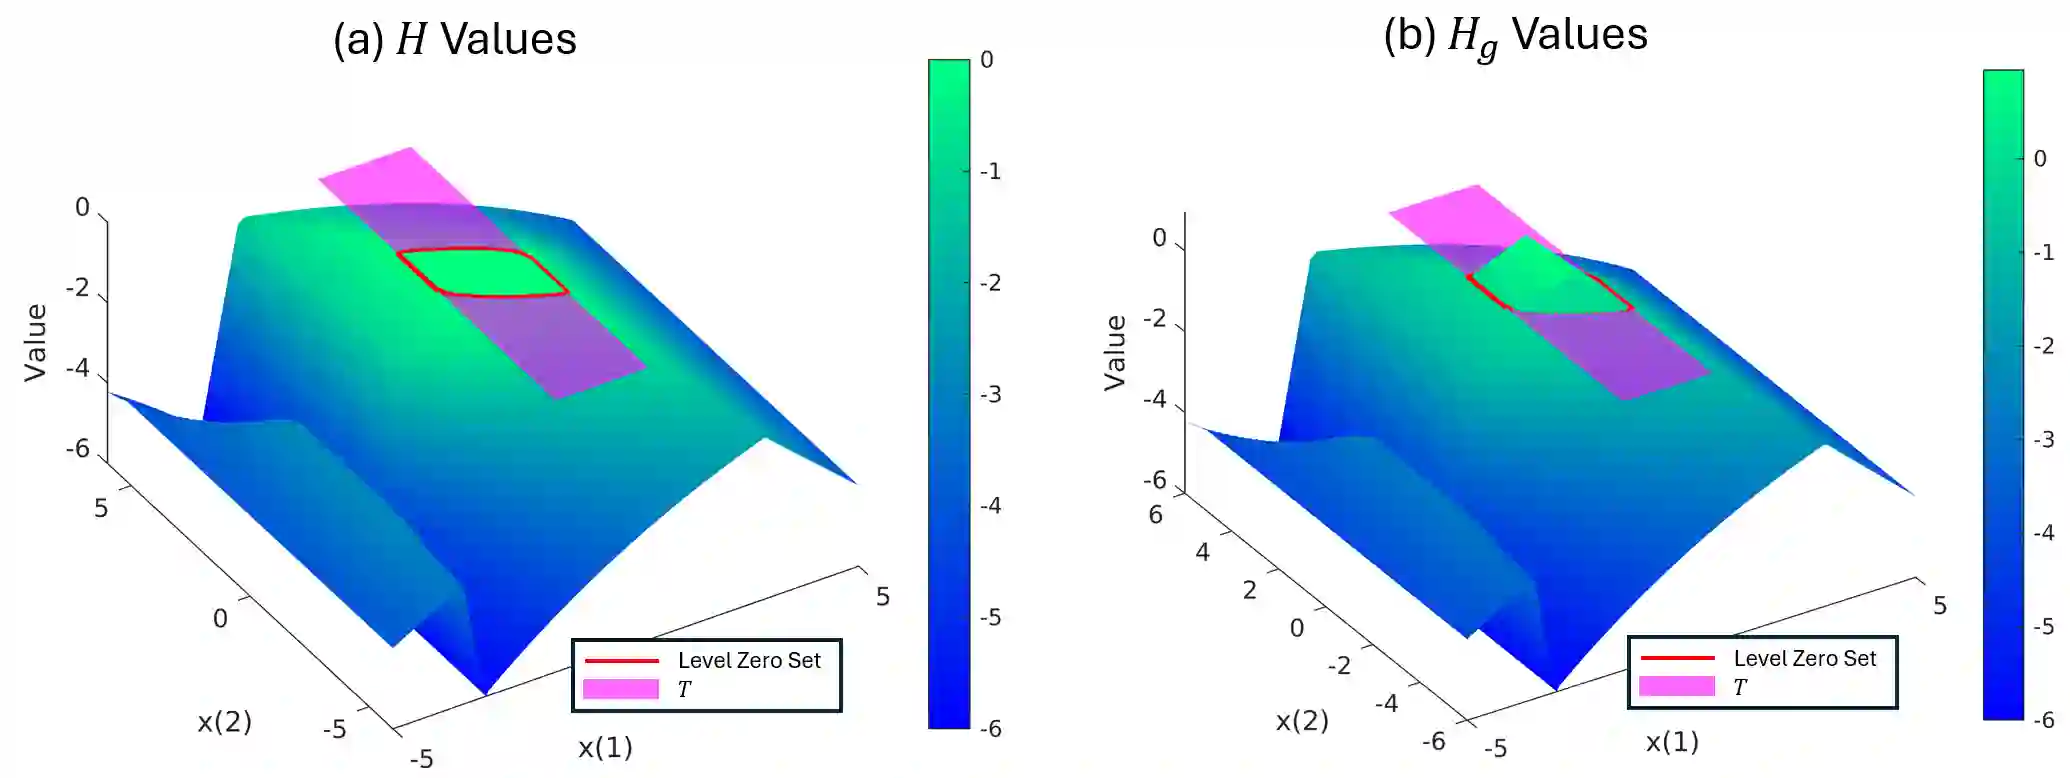
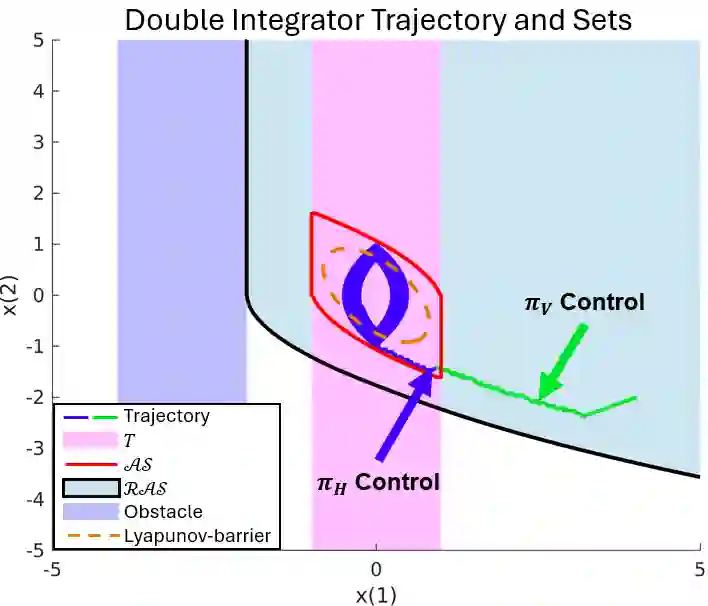
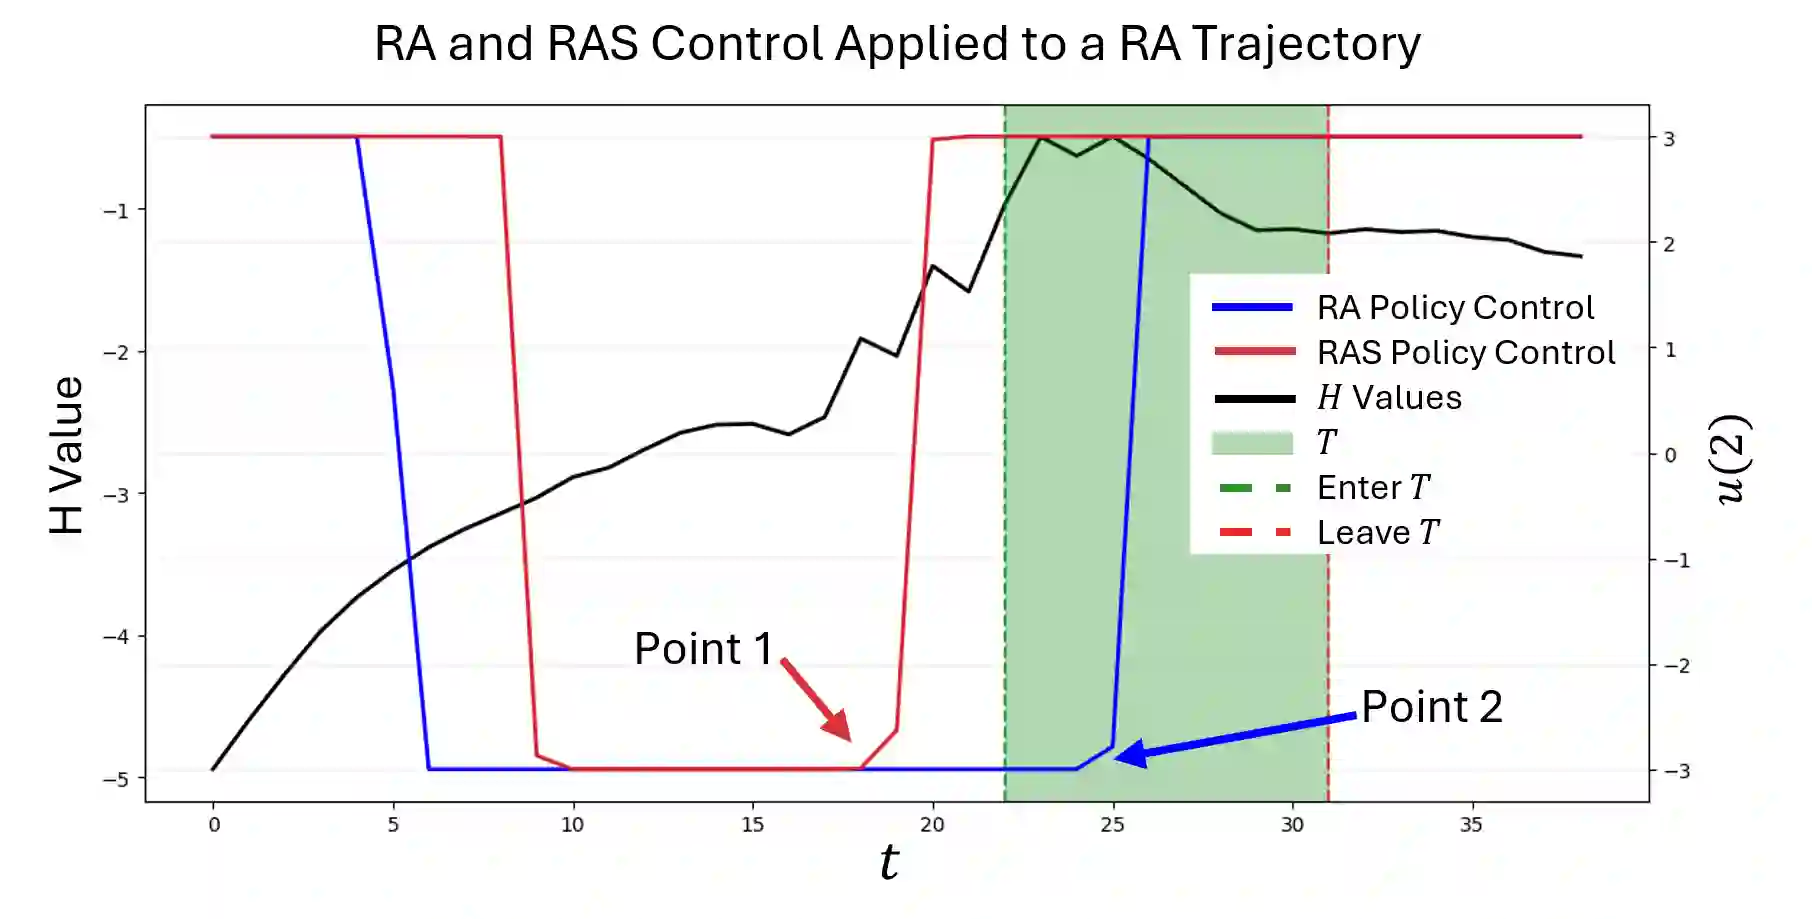
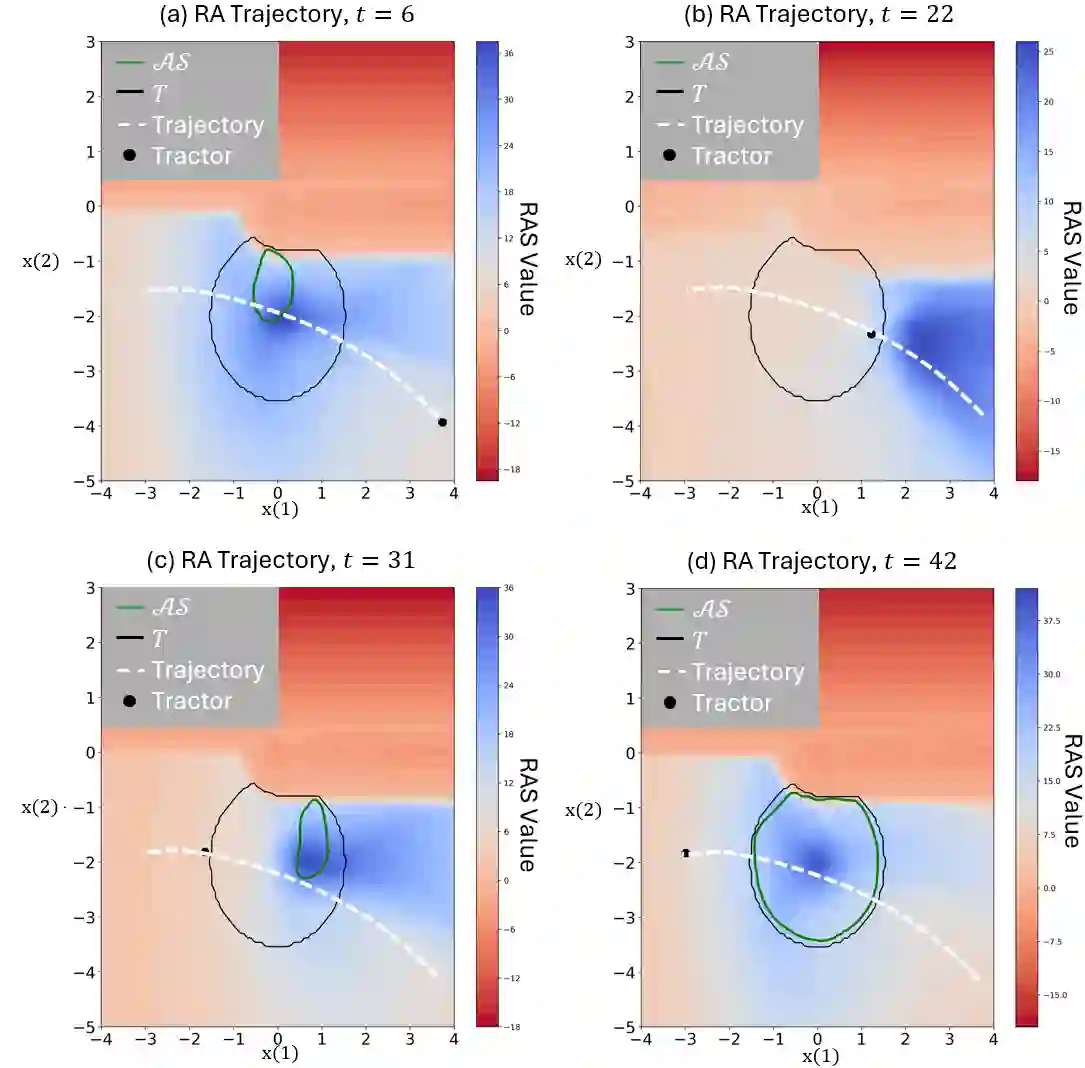
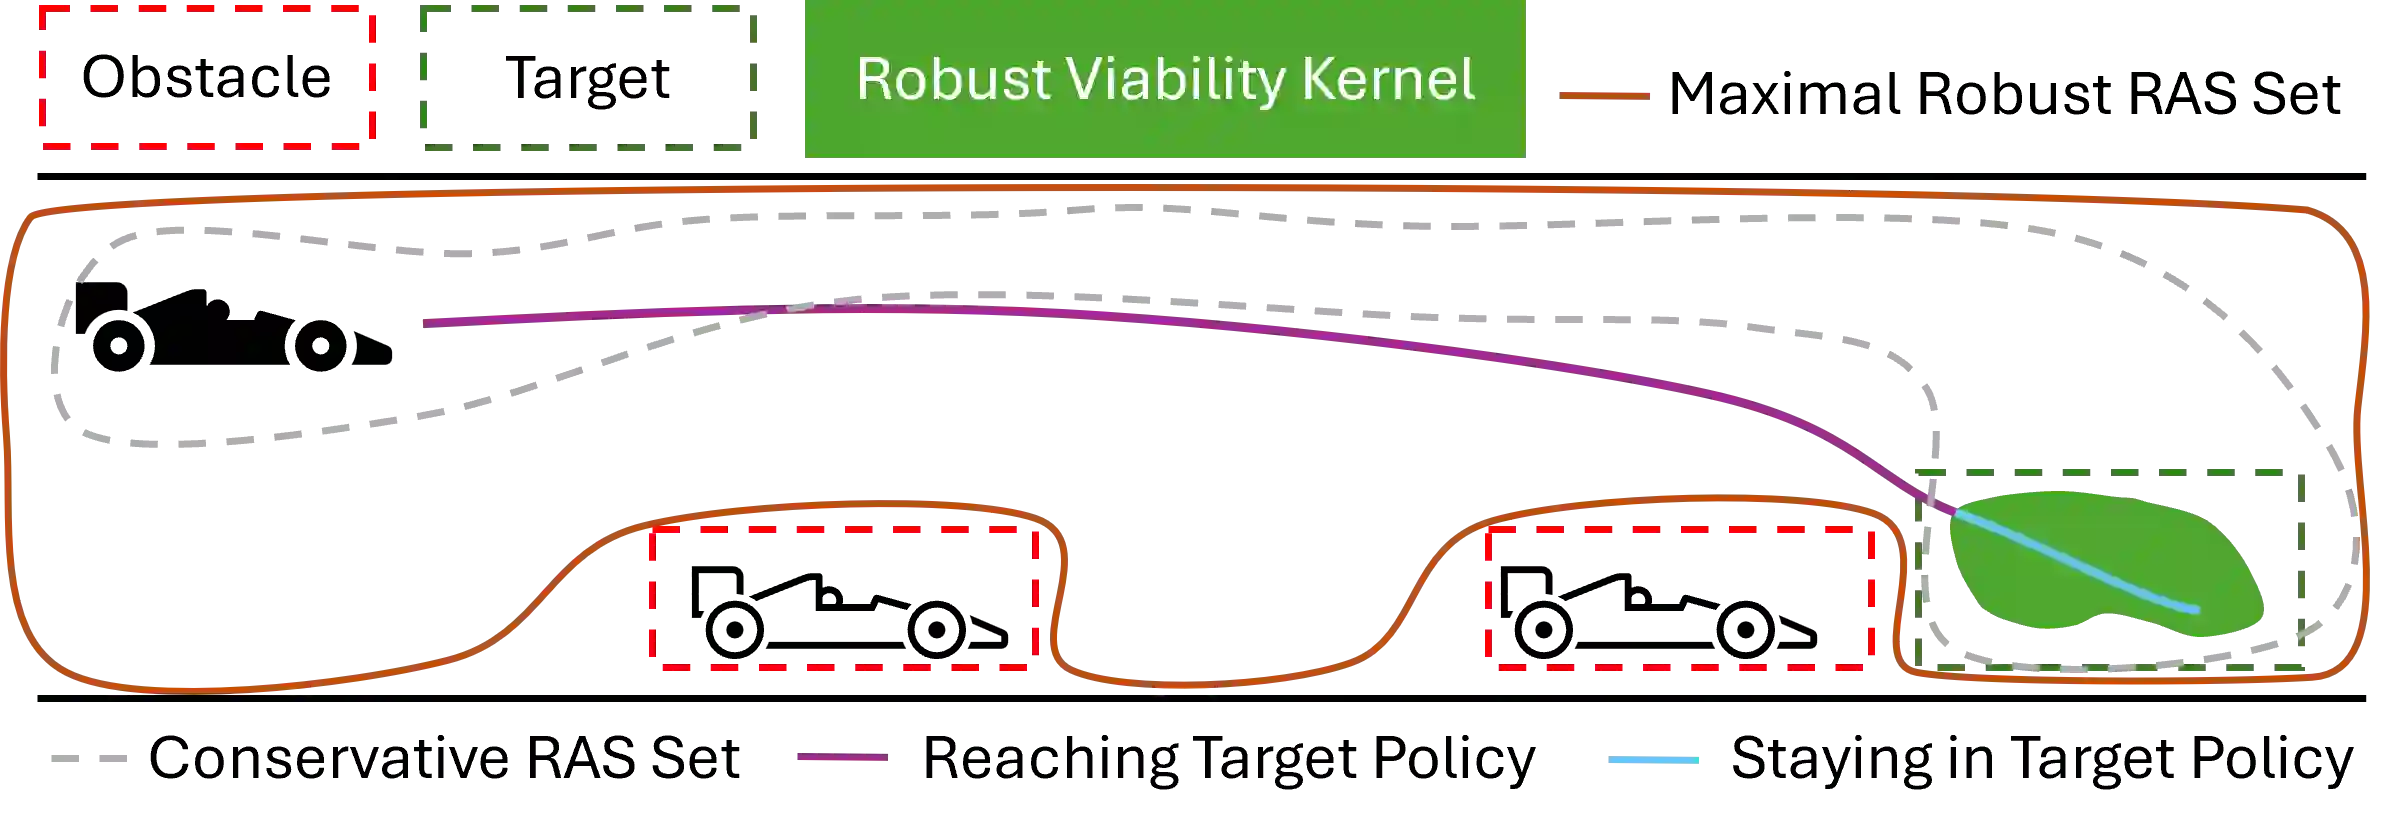
Reach-Avoid-Stay (RAS) tasks are essential in applications where systems must safely reach a target set and remain within it under all bounded disturbances. Existing approaches either struggle to compute the maximal robust RAS set, the set of all states from which the RAS task is achievable, or are limited in handling general dynamic systems. To address these challenges, this paper proposes a two-step deep reinforcement learning framework that jointly learns the maximal robust RAS set and the corresponding control policy. The first step identifies the maximal robust control-invariant set within the target set and derives a policy that ensures the system remains within it. The second step computes the maximal robust reach-avoid (RA) set using this invariant set as the target, and it is proven that this RA set is equivalent to the maximal robust RAS set. Leveraging this result, a switching policy is constructed from the two step-wise policies, which constitutes a valid policy guaranteeing completion of the RAS task. Simulation results demonstrate that the proposed framework (1) computes the exact maximal robust RAS set in the absence of training errors, yielding the least restrictive RAS policy, and (2) identifies the RAS set with high accuracy while outperforming baseline methods on RAS tasks.


翻译:暂无翻译
0
下载
关闭预览

相关内容

148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
【深度强化学习】深度强化学习揭秘
产业智能官
21+阅读 · 2017年11月13日
国家自然科学基金
348+阅读 · 2017年12月31日
国家自然科学基金
1+阅读 · 2017年12月31日
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
6+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
Arxiv
21+阅读 · 2022年11月8日
Deep Reinforcement Learning: An Overview
Arxiv
17+阅读 · 2018年11月26日
Relational Deep Reinforcement Learning
Arxiv
10+阅读 · 2018年6月28日
VIP会员
最新内容
世界模型入门:从序贯决策到通用智能体
专知会员服务
8+阅读 · 10月24日
军事域更好使用人工智能的实用指南
专知会员服务
10+阅读 · 10月22日
《衡量语言模型中的作战规划能力》
专知会员服务
14+阅读 · 10月20日
Maven智能系统:帕兰提尔军事人工智能平台详解
专知会员服务
17+阅读 · 10月20日
《测试自动化框架在敏捷软件开发中的角色》
专知会员服务
9+阅读 · 10月20日
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
13+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
19+阅读 · 10月15日
相关VIP内容
148页最新《深度强化学习》教程,148页ppt
专知会员服务
77+阅读 · 2023年4月29日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关资讯
相关基金
国家自然科学基金
348+阅读 · 2017年12月31日
国家自然科学基金
1+阅读 · 2017年12月31日
国家自然科学基金
6+阅读 · 2017年12月31日
国家自然科学基金
44+阅读 · 2015年12月31日
国家自然科学基金
41+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
6+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
Top
微信扫码咨询专知VIP会员