

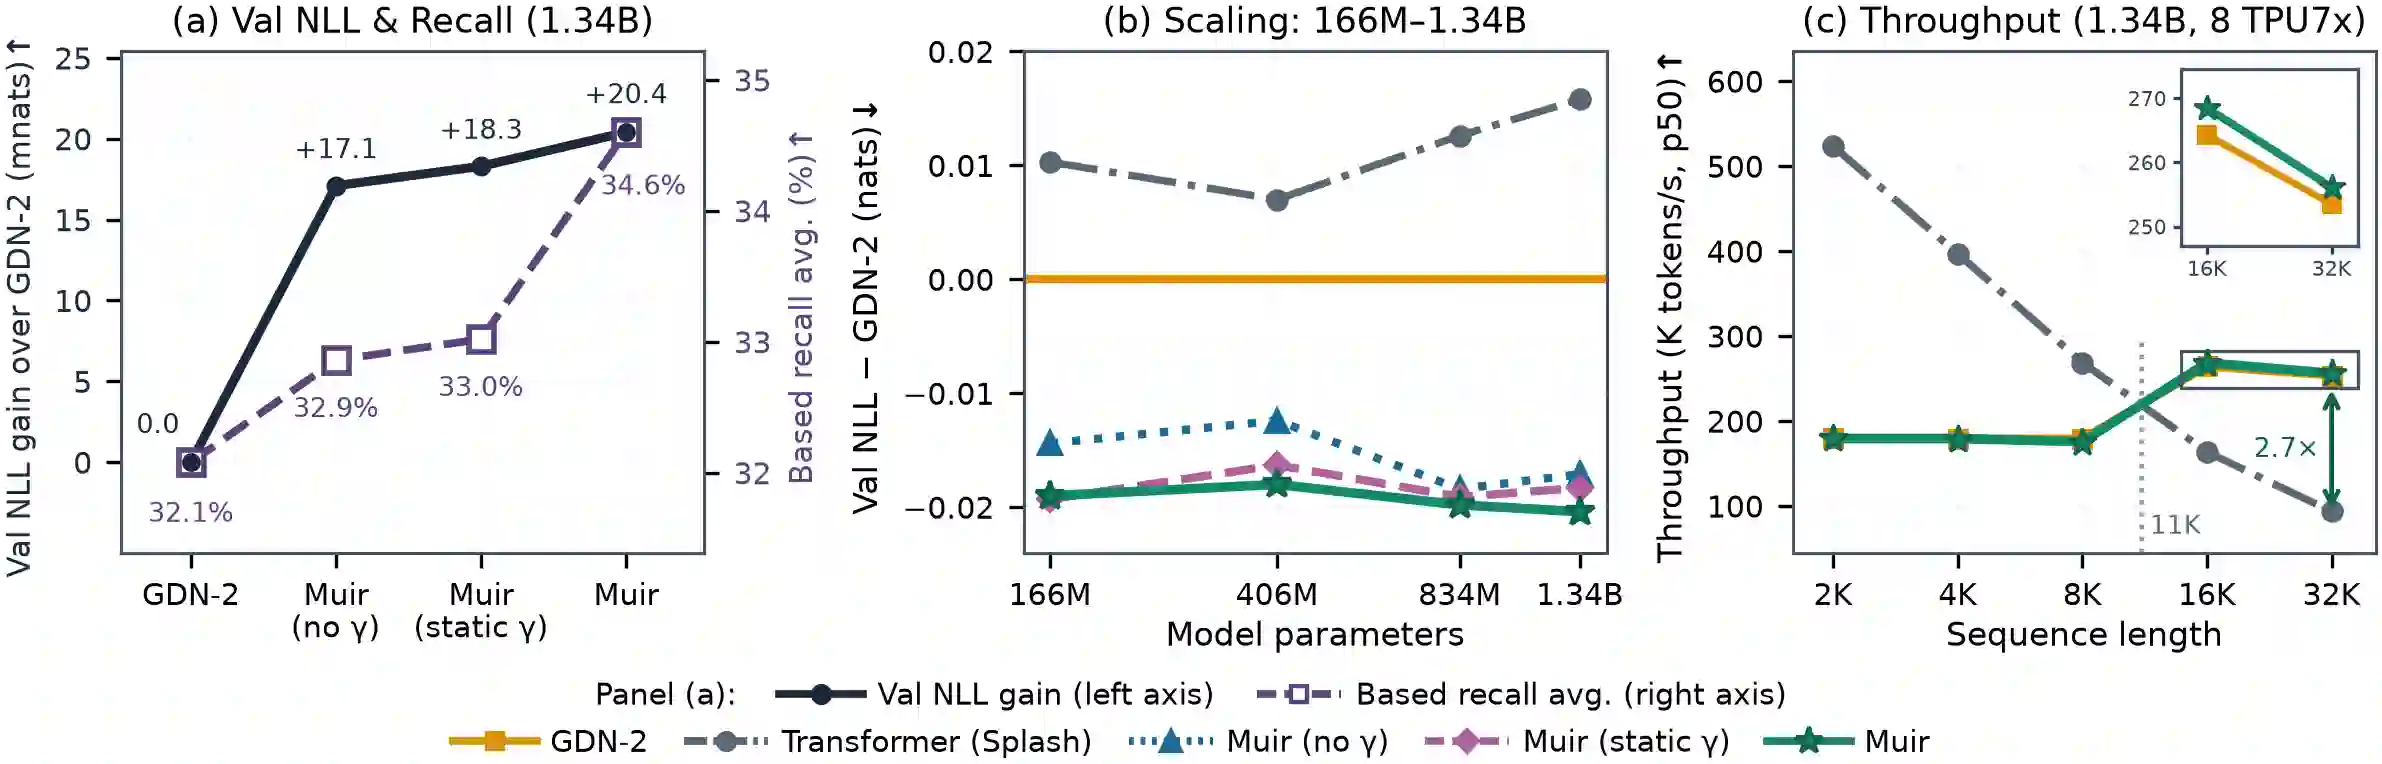
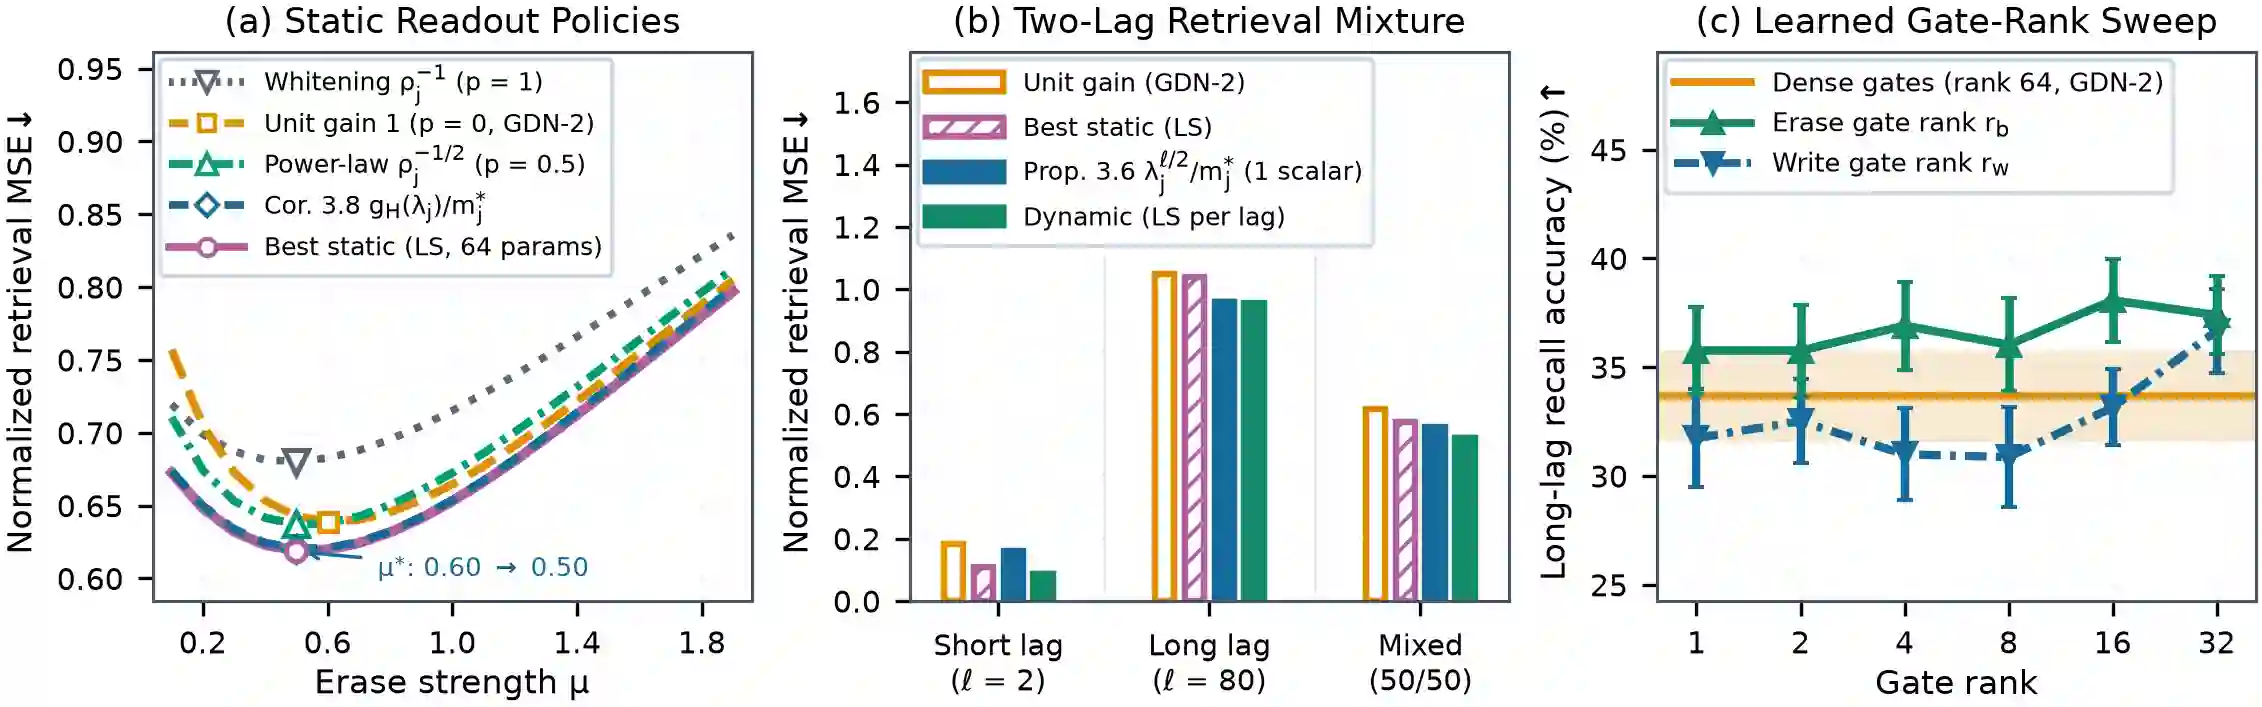
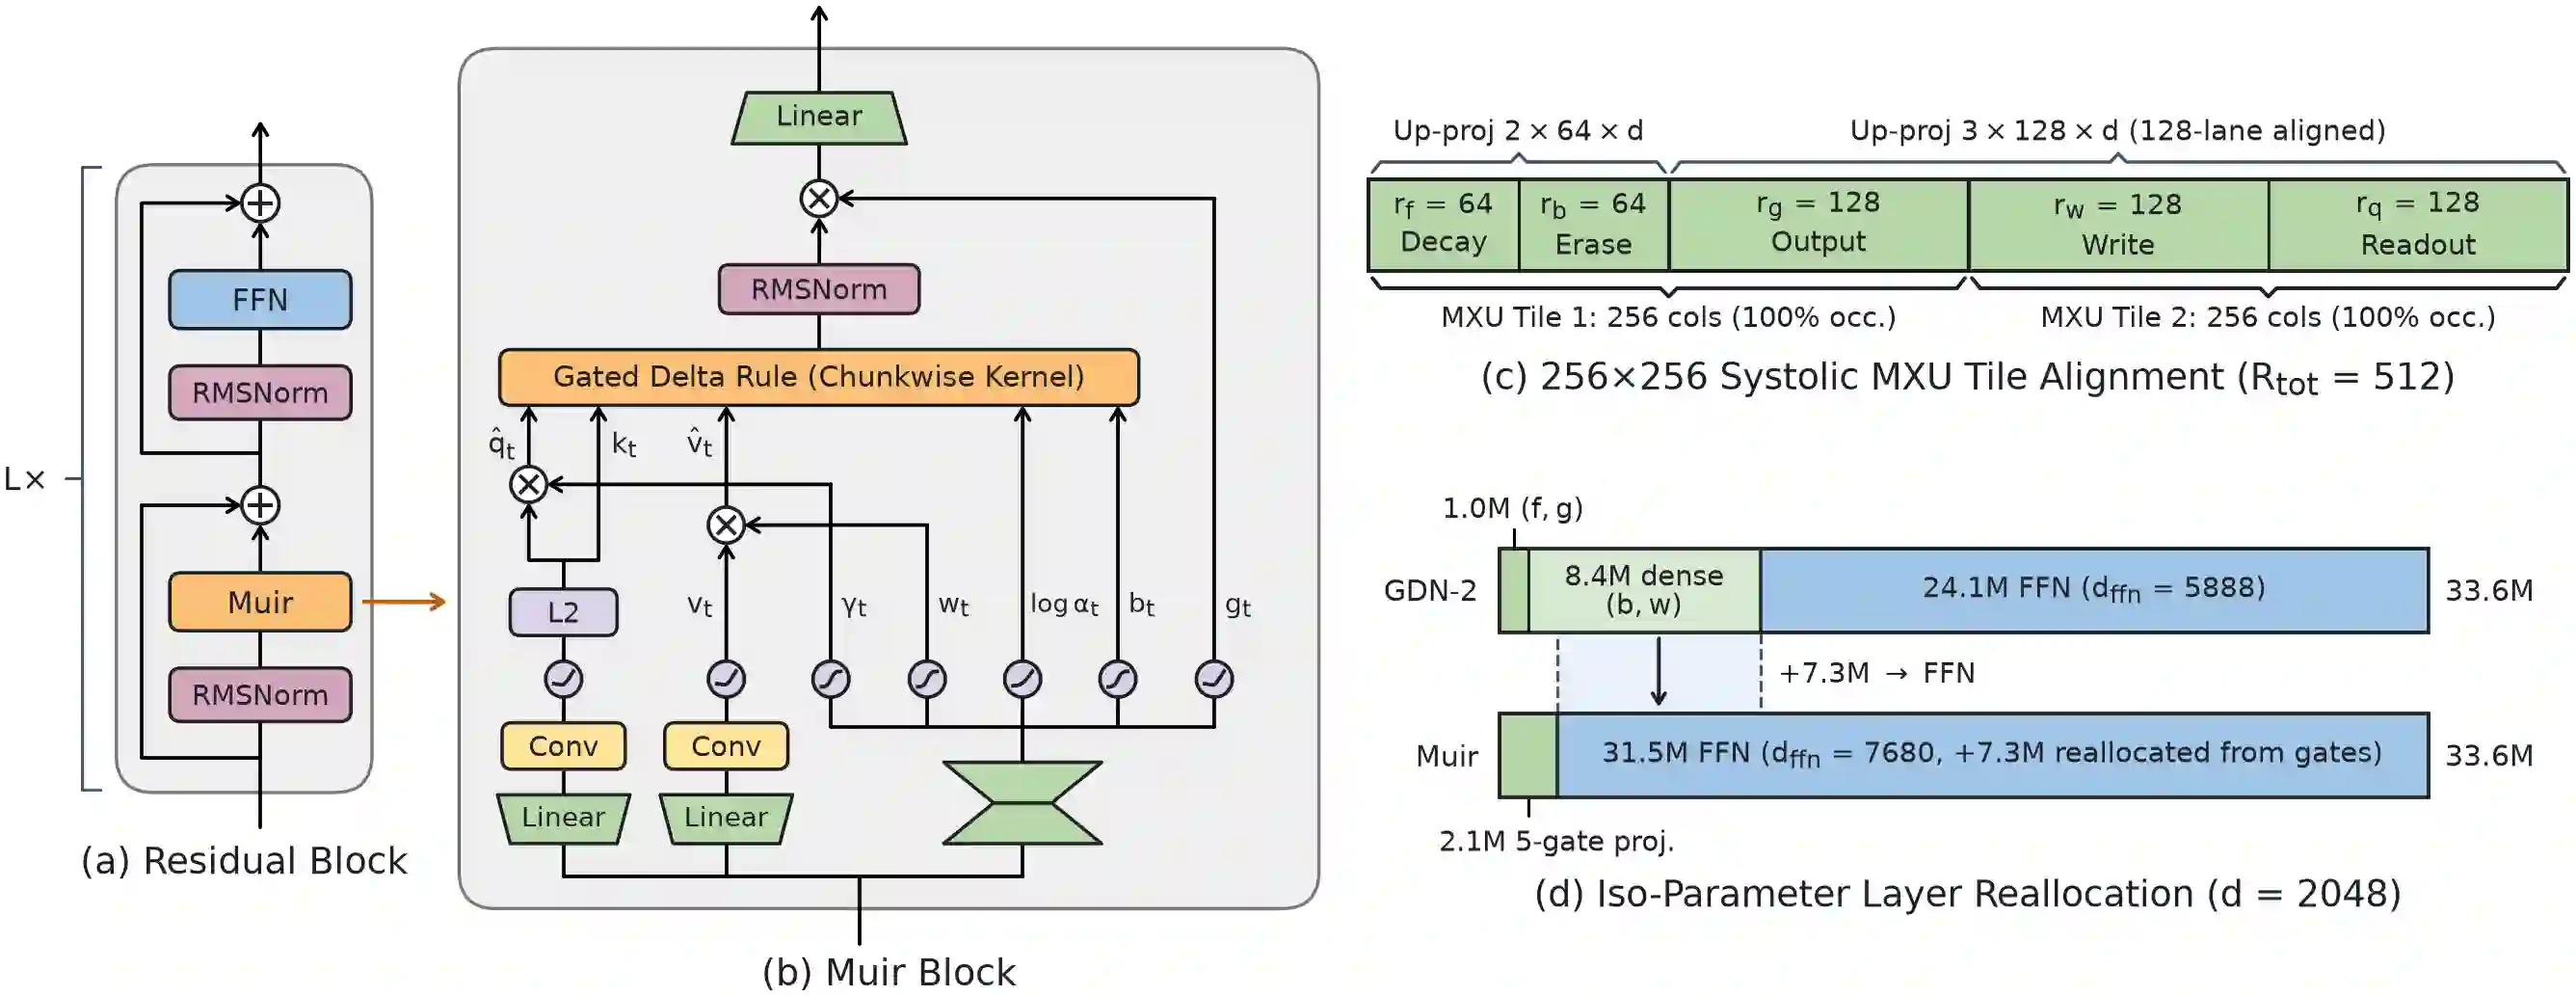
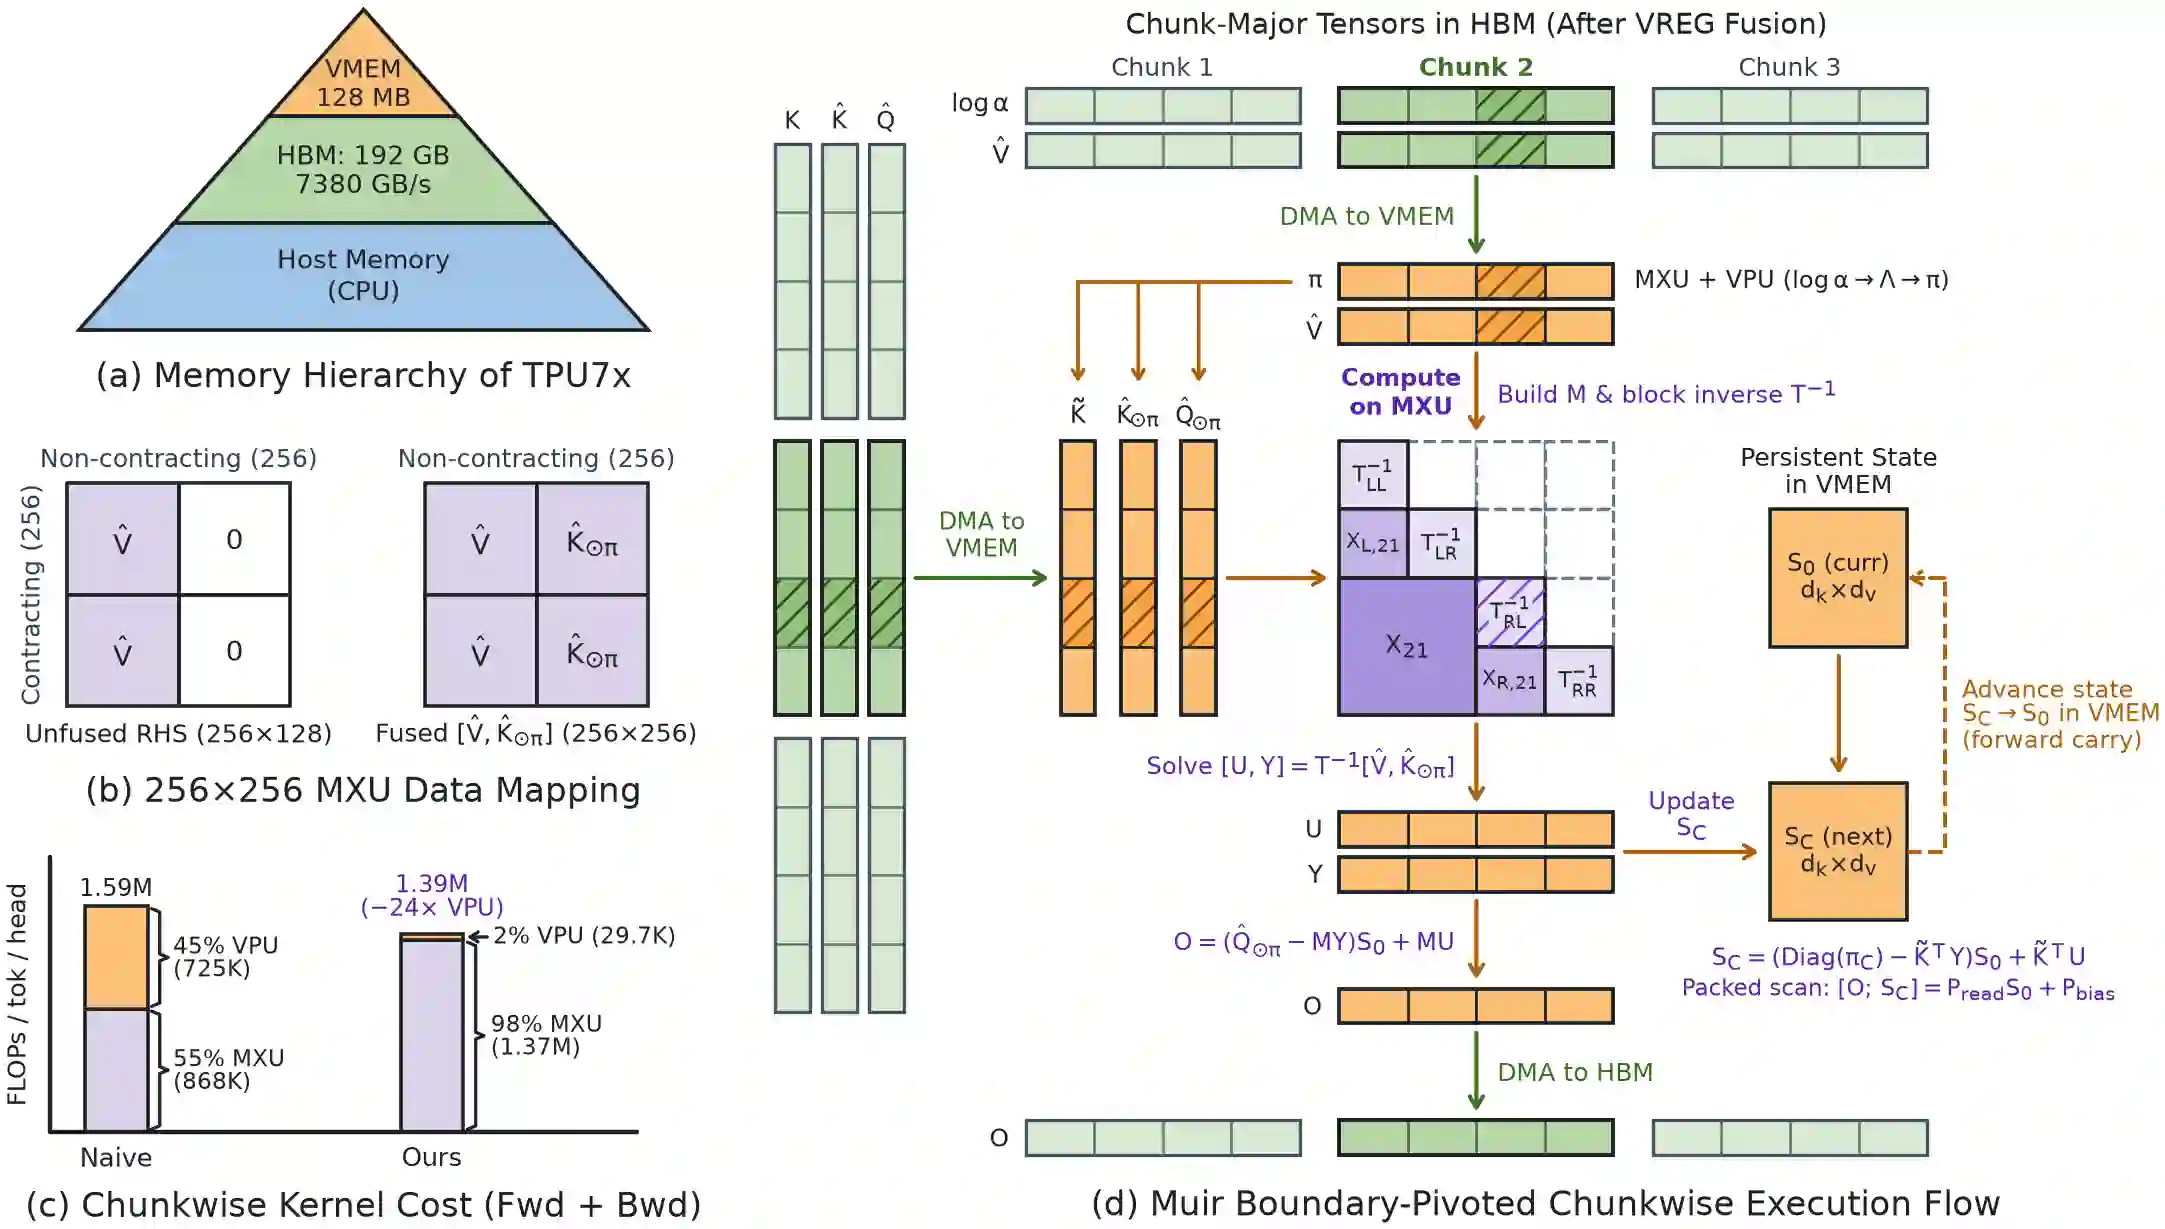
Linear attention compresses context into a fixed-size key-value state for linear-time training and constant-memory inference. Gated delta-rule models decay this state and erase its prediction for an incoming key before writing a new value; Gated DeltaNet-2 (GDN-2) generalizes this with channel-wise decay and decoupled, full-rank erase and write gates. However, we show that state updates are far less sensitive to erasure than to writes: key activation and unit normalization concentrate key energy onto a sparse subset of channels, whereas value writes scale all channels, so the erase gate can be parameterized at lower rank. Furthermore, slow-decaying state rows accumulate much larger norms than fast rows, dominating unweighted readout and forcing stronger write-time erasure to suppress interference. Guided by this analysis, we introduce Muir, which fuses all gates into a sensitivity-allocated low-rank projection, re-weights state rows with a matched-filter readout gate, and reinvests the saved parameters in a wider feed-forward network. Because standard chunkwise algorithms become numerically unstable at the large chunk sizes needed to saturate wide matrix units, we design a parallel update for stable, efficient training. Across 166M-1.34B parameters, Muir lowers perplexity by 1.8-2.0% over GDN-2 and 2.5-3.6% over Transformer, raises commonsense accuracy by up to 1.9 points, and improves extractive recall over GDN-2. At 1.34B, Muir outperforms both baselines on multi-hop and multi-needle recall, extrapolates 2,560x from its 4K training length to 10M-token streams without perplexity drift, and maintains near-100% passkey retrieval to 1M tokens with static readout. Muir achieves these gains while matching GDN-2 throughput, reaching its 100B-token validation loss 1.2x faster, and training 2.7x faster than Transformer at 32K.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员