

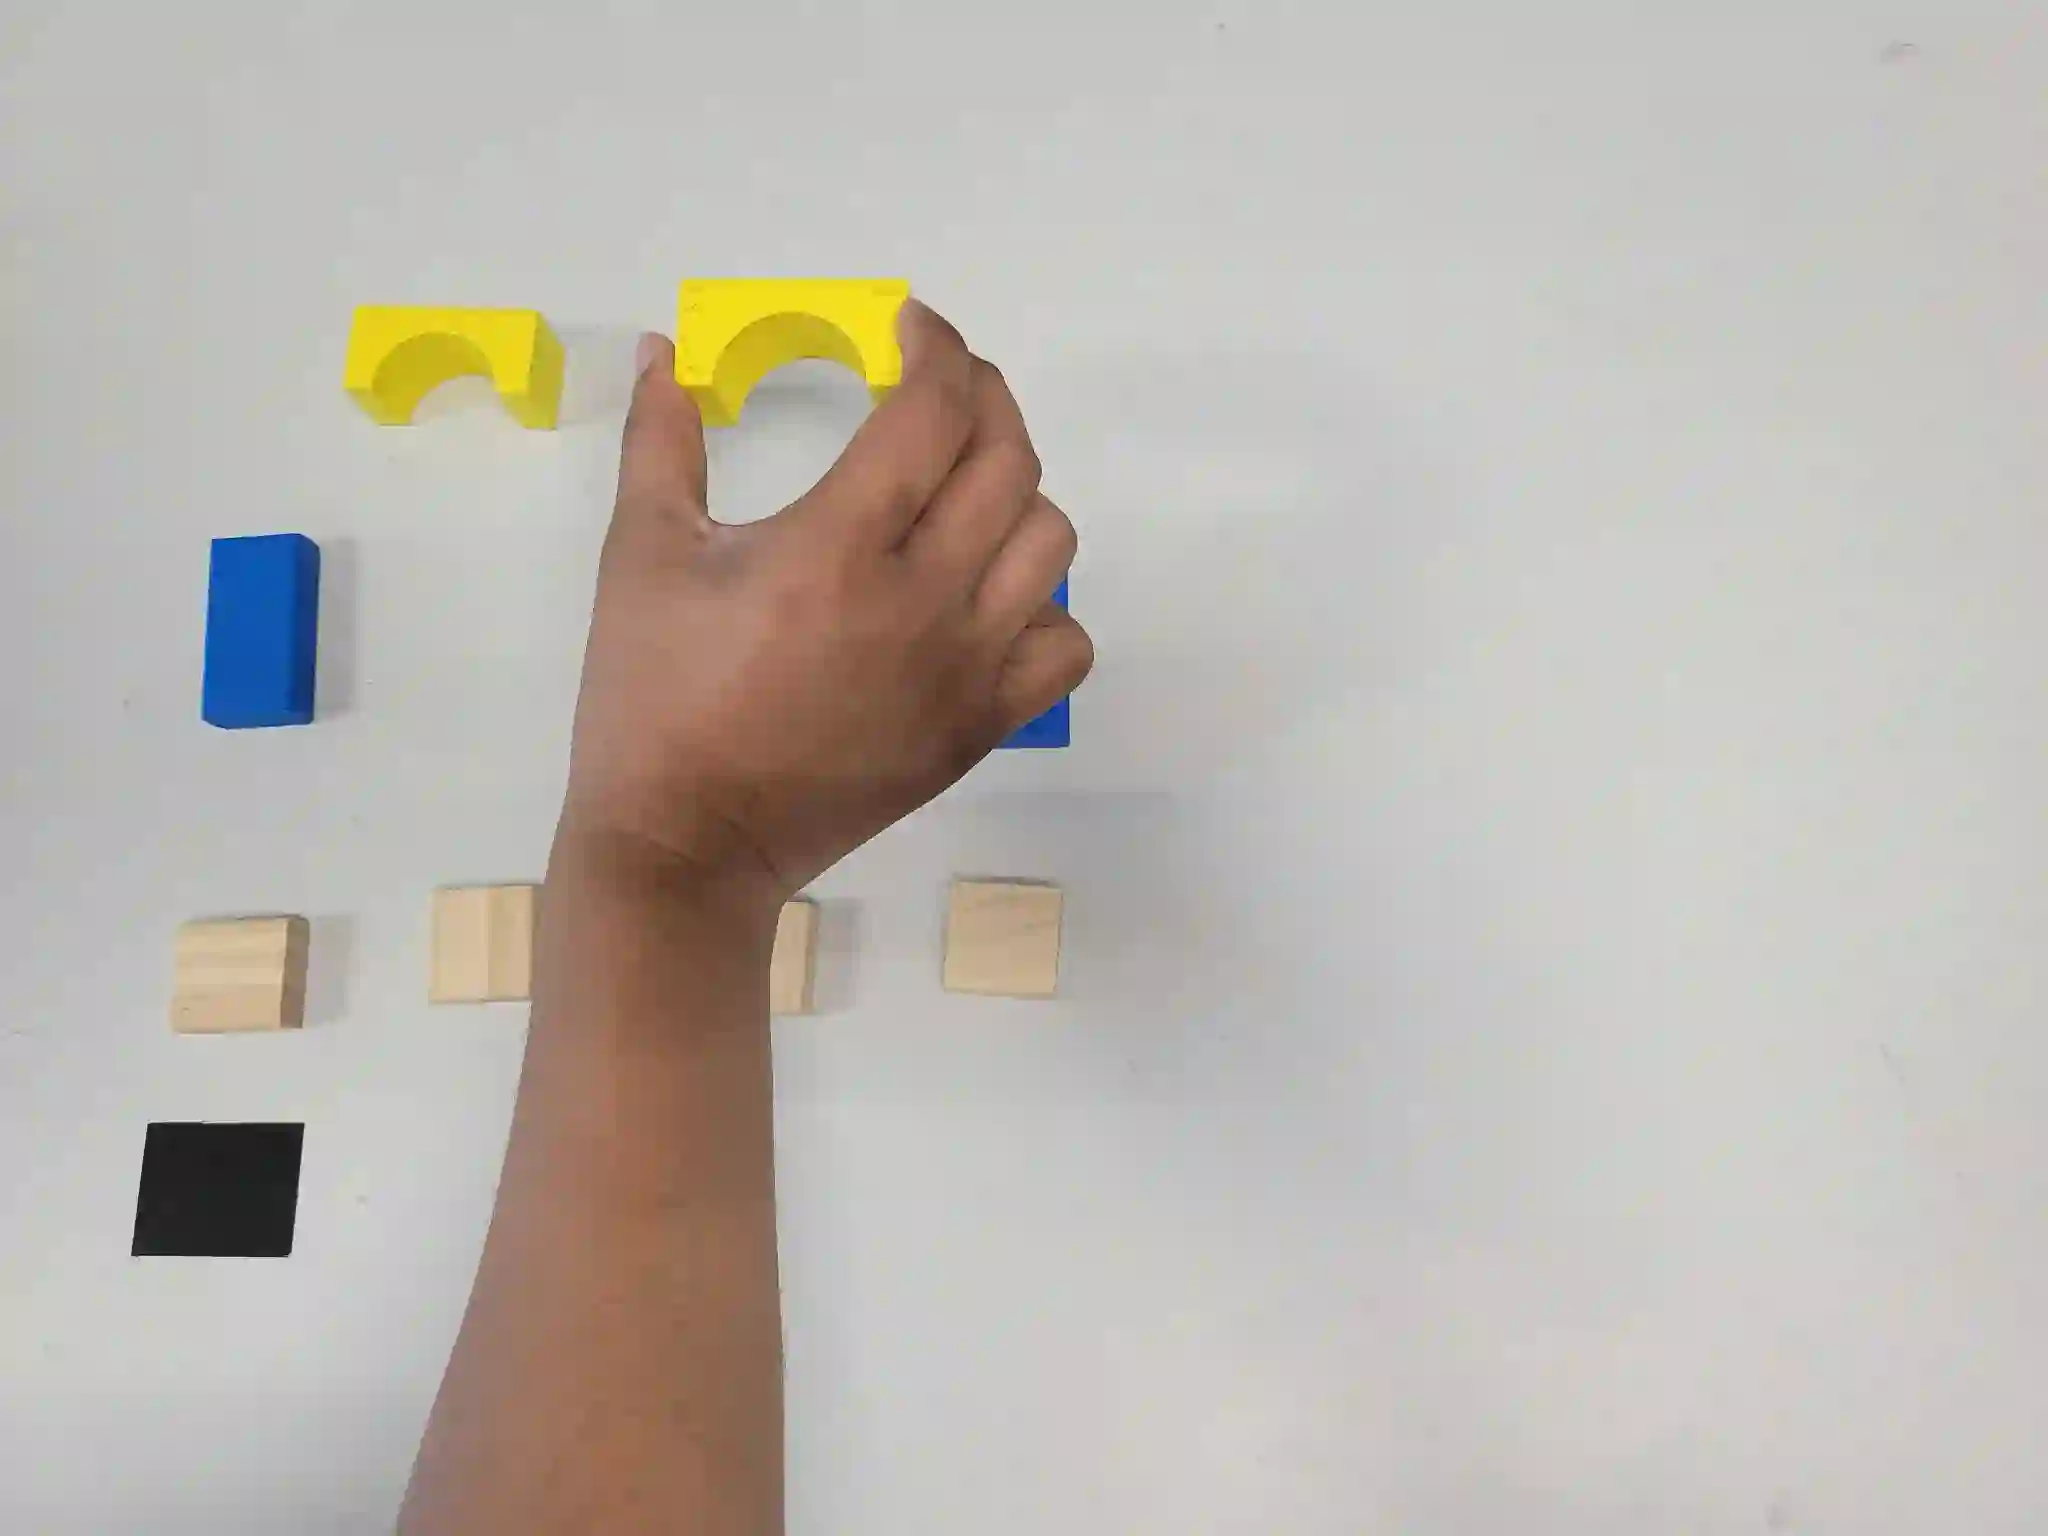
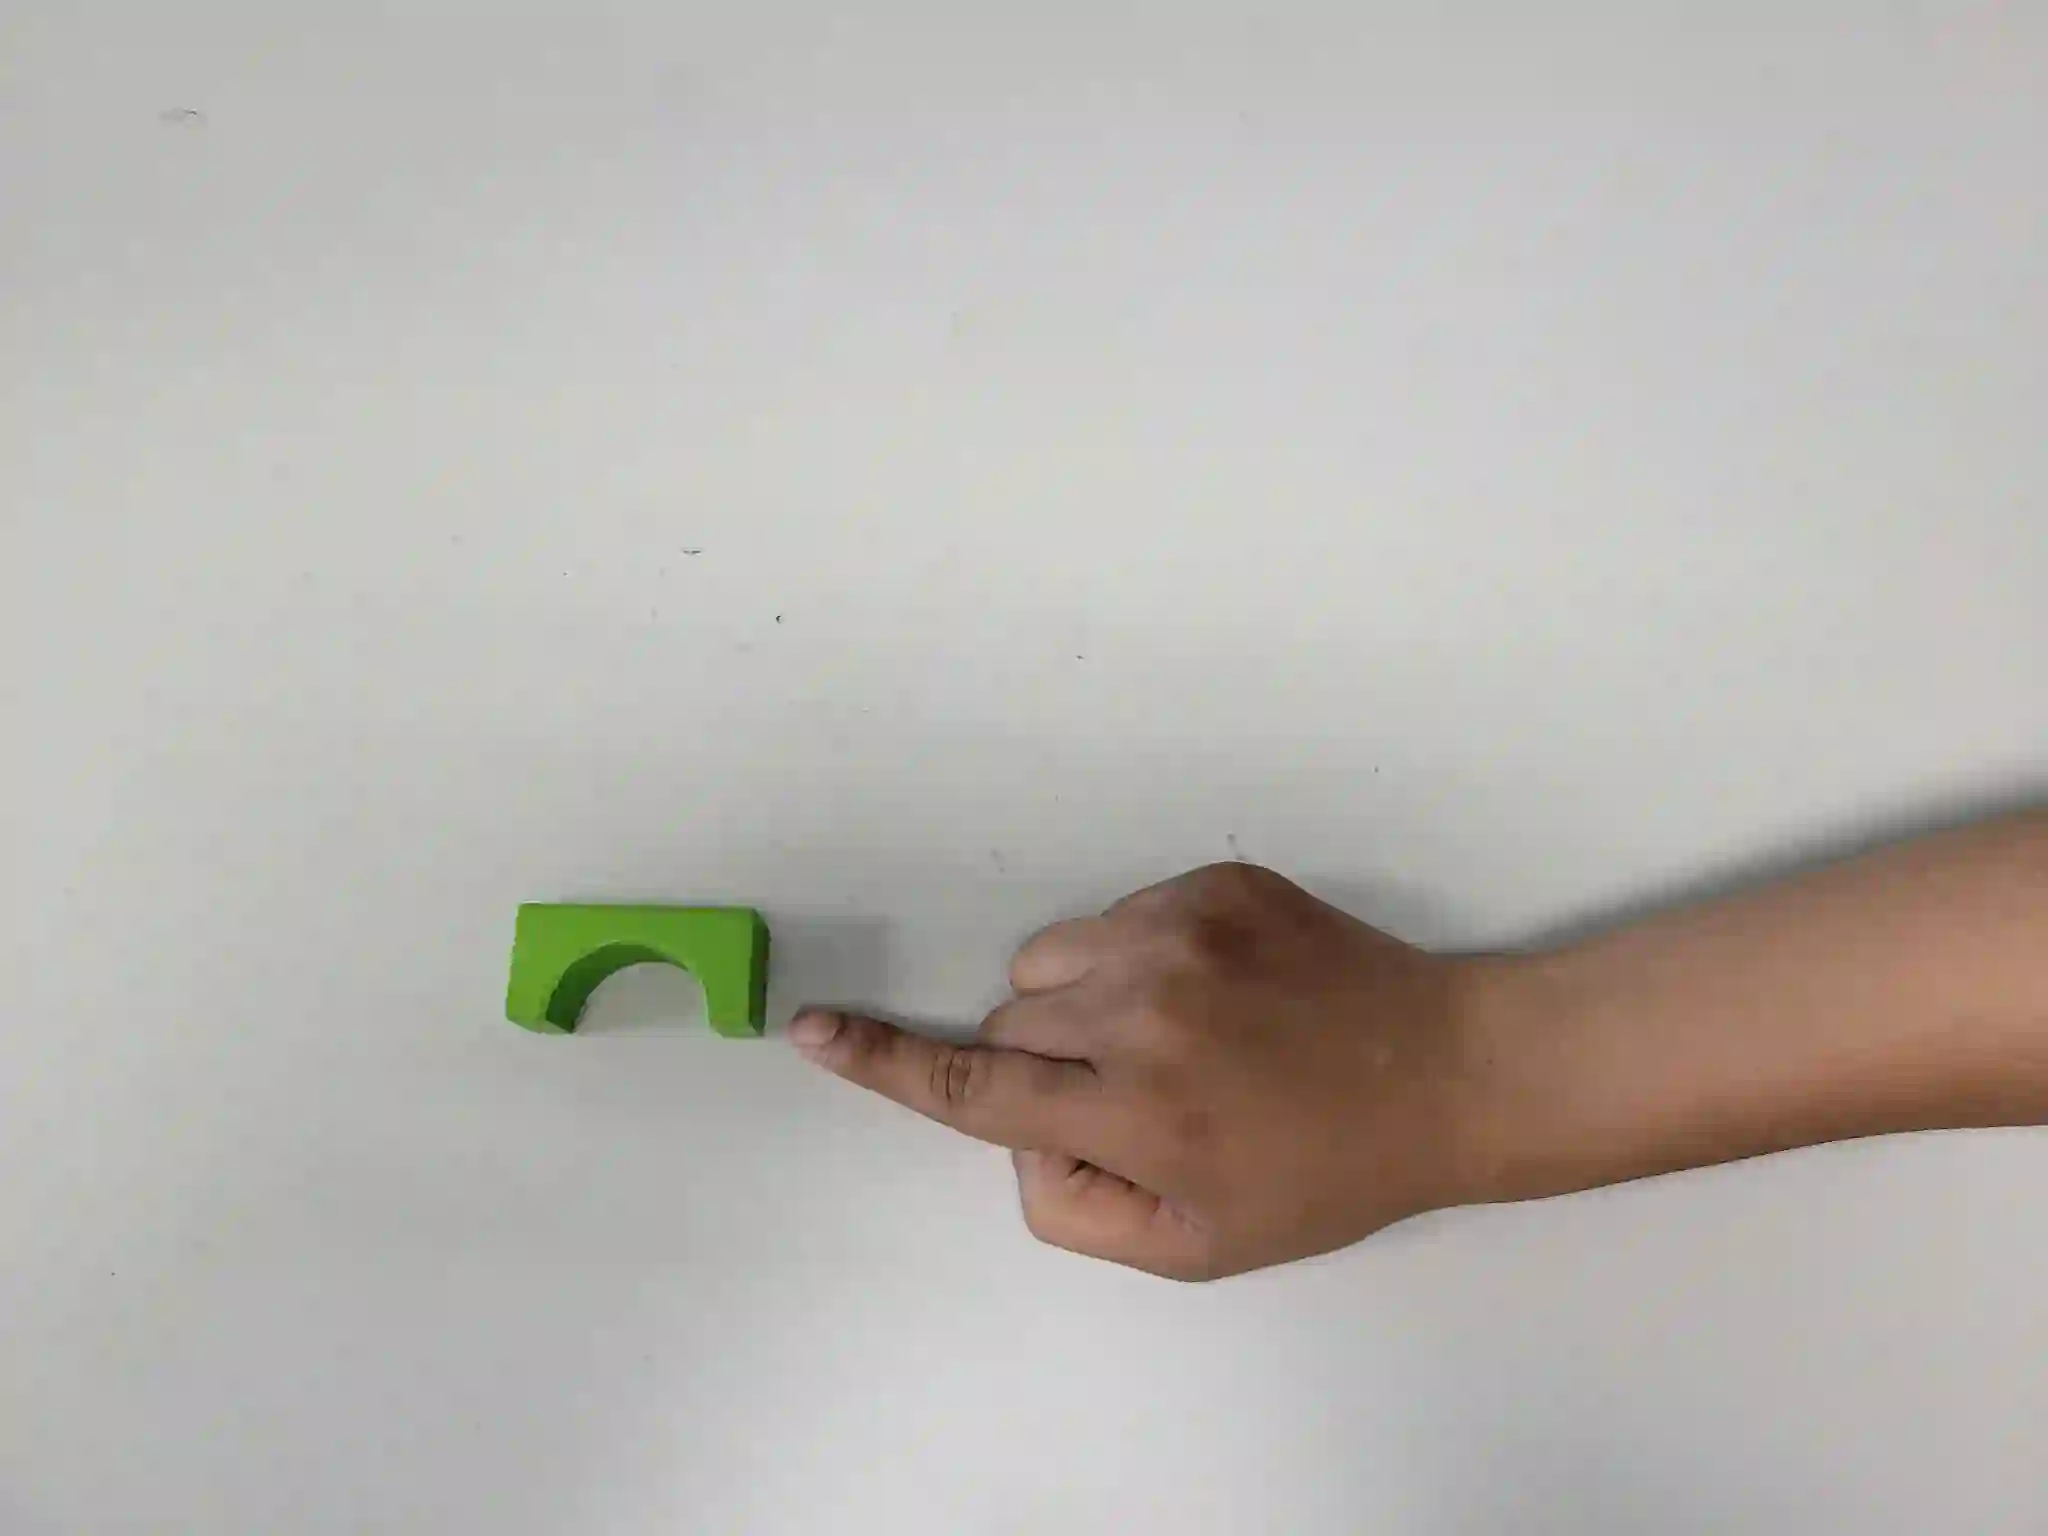
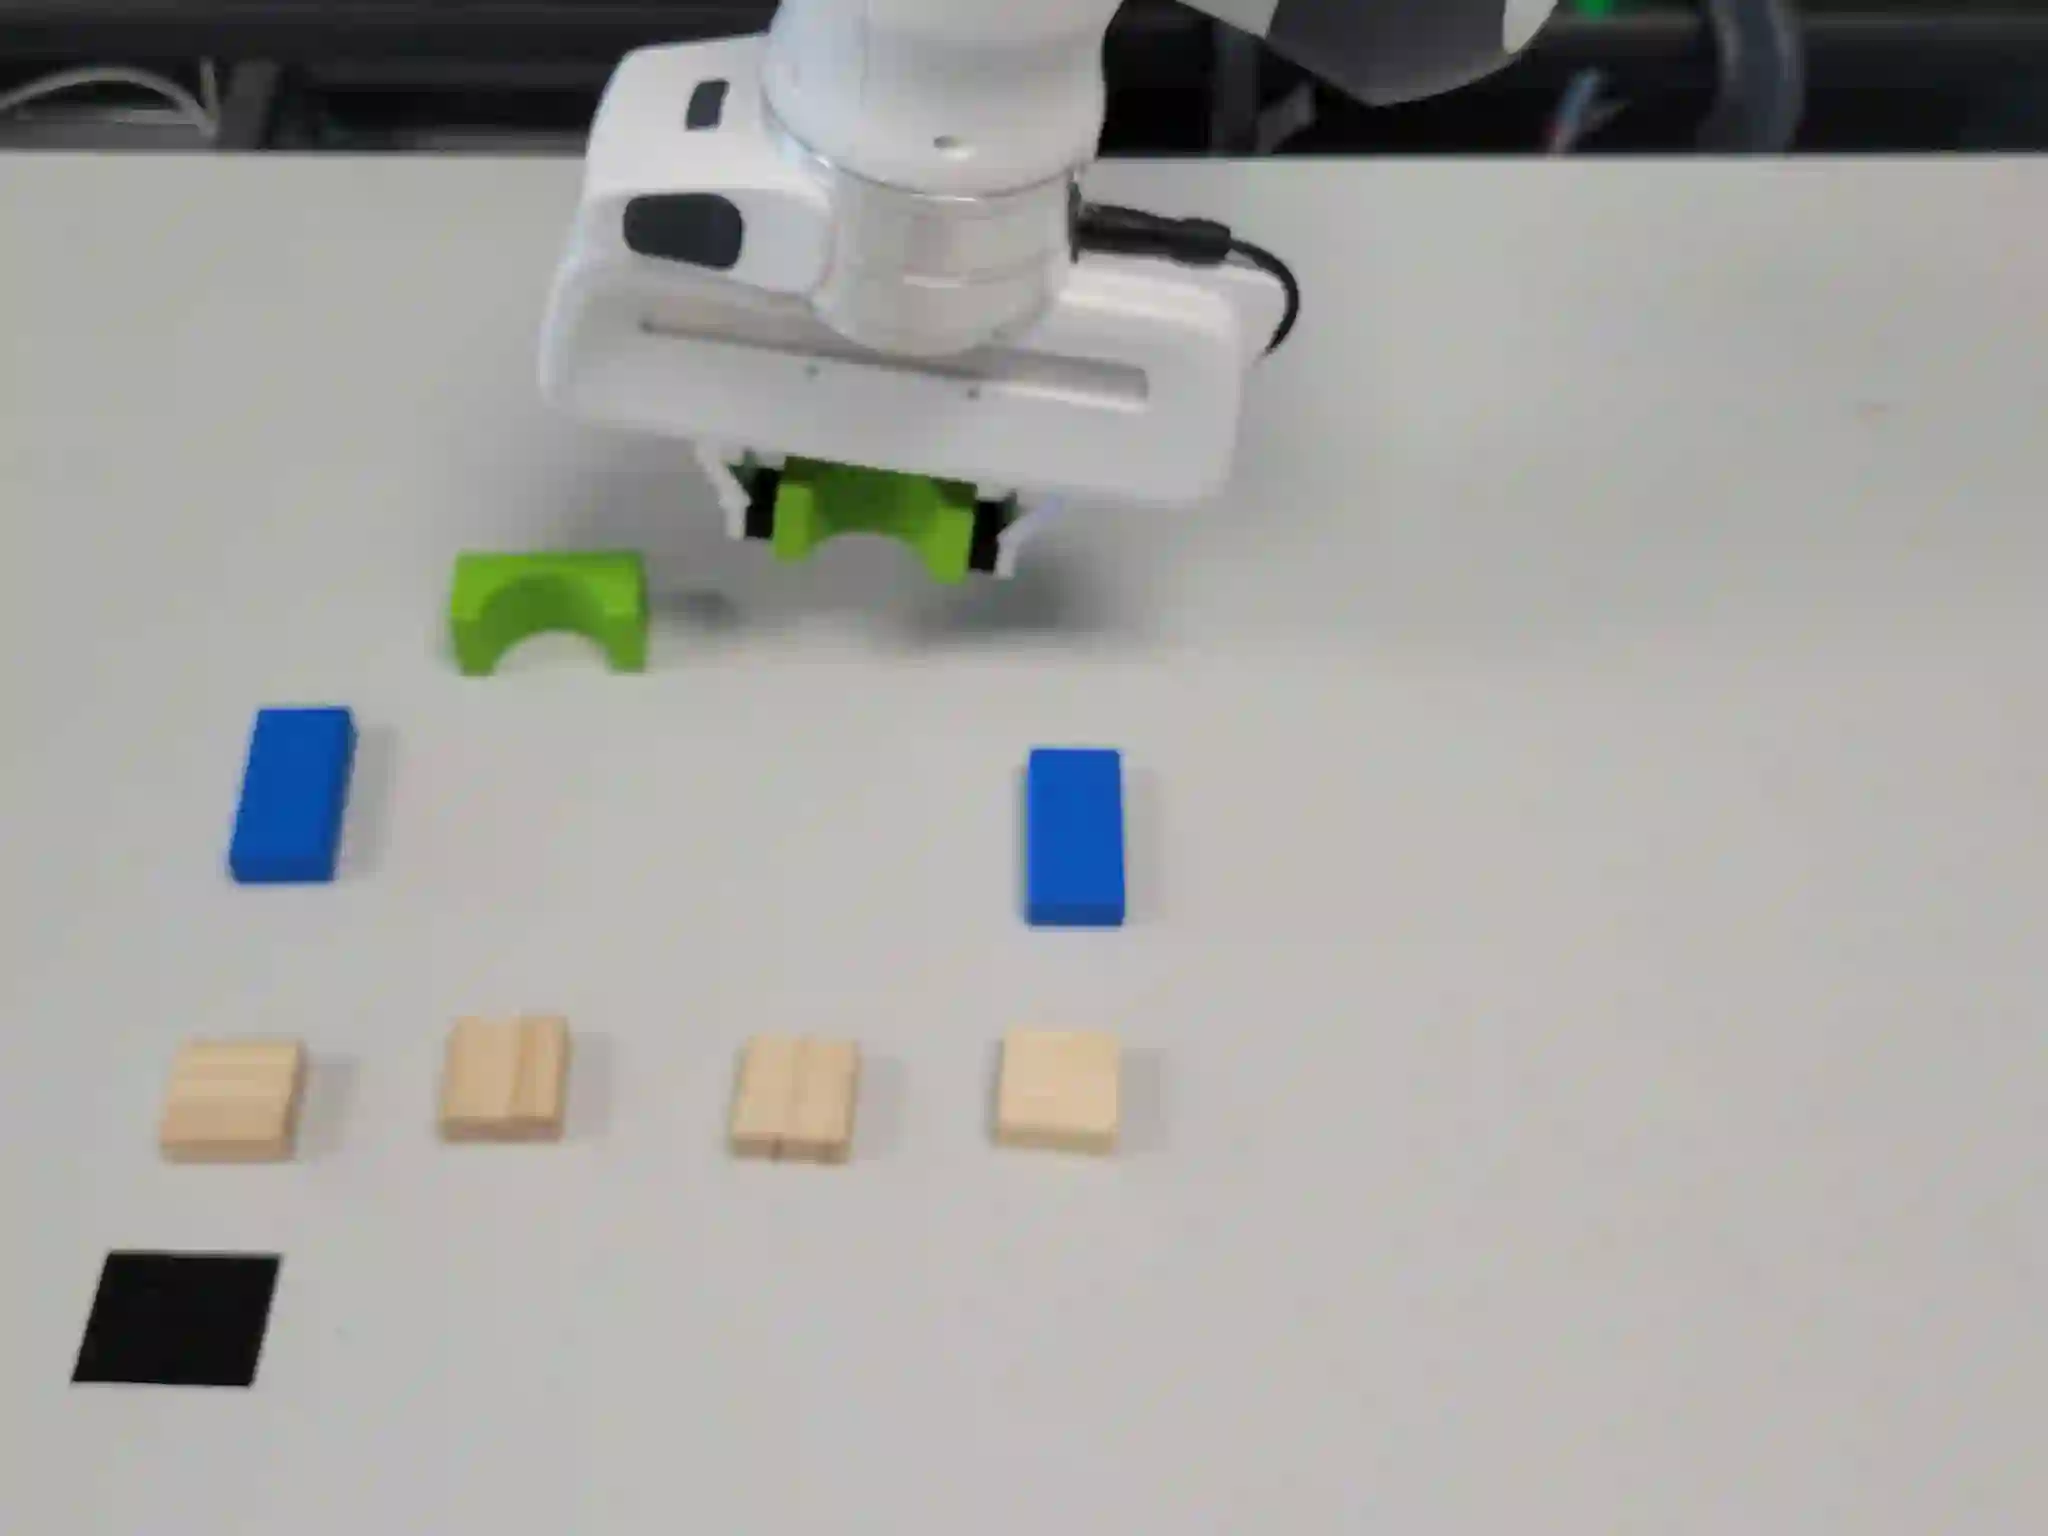
We present a framework for robots to learn novel visual concepts and tasks via in-situ linguistic interactions with human users. Previous approaches have either used large pre-trained visual models to infer novel objects zero-shot, or added novel concepts along with their attributes and representations to a concept hierarchy. We extend the approaches that focus on learning visual concept hierarchies by enabling them to learn novel concepts and solve unseen robotics tasks with them. To enable a visual concept learner to solve robotics tasks one-shot, we developed two distinct techniques. Firstly, we propose a novel approach, Hi-Viscont(HIerarchical VISual CONcept learner for Task), which augments information of a novel concept to its parent nodes within a concept hierarchy. This information propagation allows all concepts in a hierarchy to update as novel concepts are taught in a continual learning setting. Secondly, we represent a visual task as a scene graph with language annotations, allowing us to create novel permutations of a demonstrated task zero-shot in-situ. We present two sets of results. Firstly, we compare Hi-Viscont with the baseline model (FALCON) on visual question answering(VQA) in three domains. While being comparable to the baseline model on leaf level concepts, Hi-Viscont achieves an improvement of over 9% on non-leaf concepts on average. We compare our model's performance against the baseline FALCON model. Our framework achieves 33% improvements in success rate metric, and 19% improvements in the object level accuracy compared to the baseline model. With both of these results we demonstrate the ability of our model to learn tasks and concepts in a continual learning setting on the robot.
翻译:我们提出了一种框架,使机器人能够通过与人类用户的原位语言交互来学习新颖的视觉概念和任务。以往的方法要么使用大规模预训练视觉模型以零样本方式推断新物体,要么将新概念及其属性和表示添加到概念层次结构中。我们扩展了专注于学习视觉概念层次结构的方法,使其能够学习新概念,并利用这些概念解决未见过的机器人任务。为使视觉概念学习器能够一次性解决机器人任务,我们开发了两种不同技术。首先,我们提出了一种新颖方法Hi-Viscont(用于任务的层次化视觉概念学习器),该方法将新概念的信息增强到其概念层次结构中的父节点。这种信息传播使得层次结构中的所有概念能够在持续学习环境下随着新概念的教学而更新。其次,我们将视觉任务表示为带有语言注释的场景图,从而能够原位生成演示任务的零样本新型排列。我们展示了两组结果。首先,我们在三个领域的视觉问答(VQA)任务上将Hi-Viscont与基线模型(FALCON)进行了比较。在叶级概念上与基线模型性能相当的同时,Hi-Viscont在非叶概念上平均提升了超过9%。我们还将模型性能与基线FALCON模型进行了比较。与基线模型相比,我们的框架在成功率指标上实现了33%的提升,在物体级准确率上实现了19%的提升。通过这两组结果,我们展示了模型在机器人上持续学习环境中学习任务和概念的能力。


相关内容




 微信扫码咨询专知VIP会员