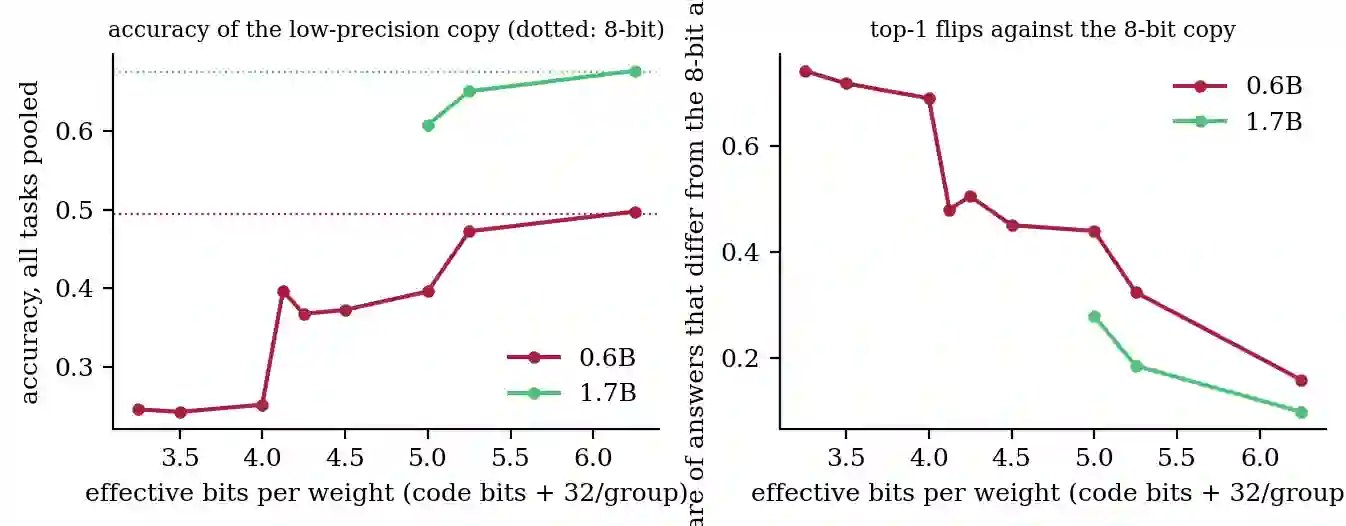
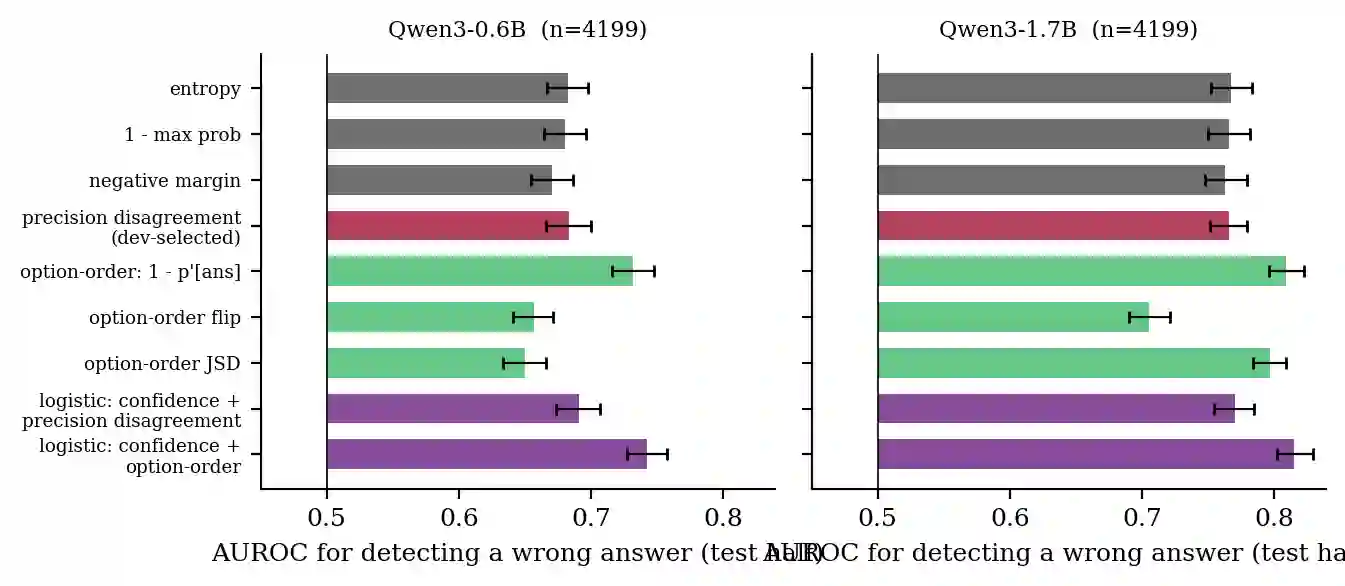
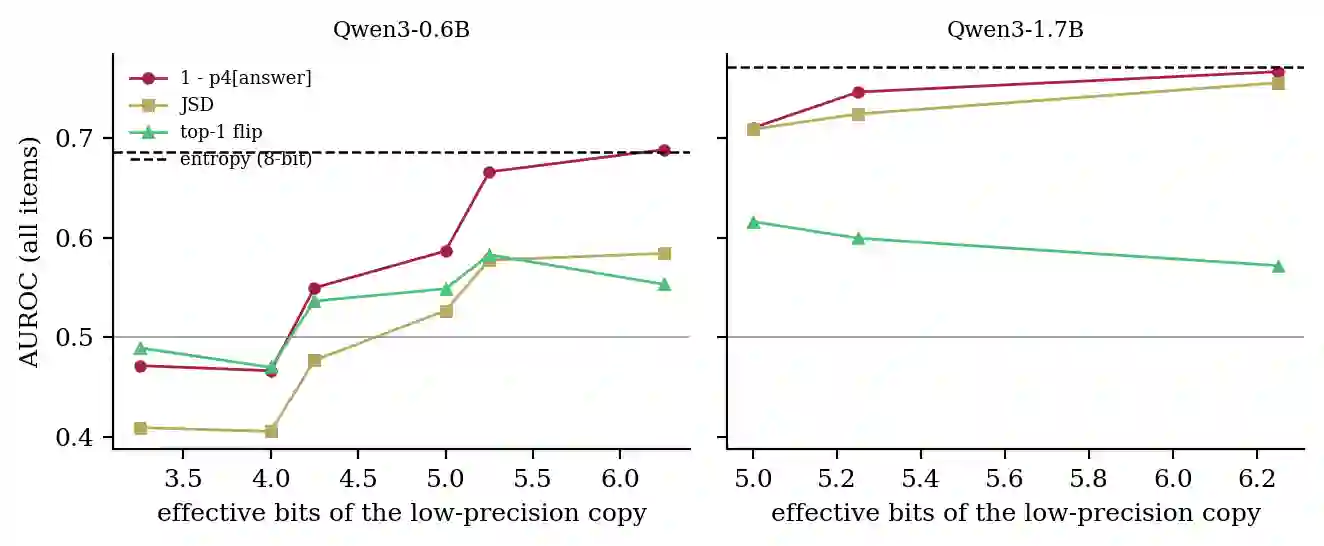
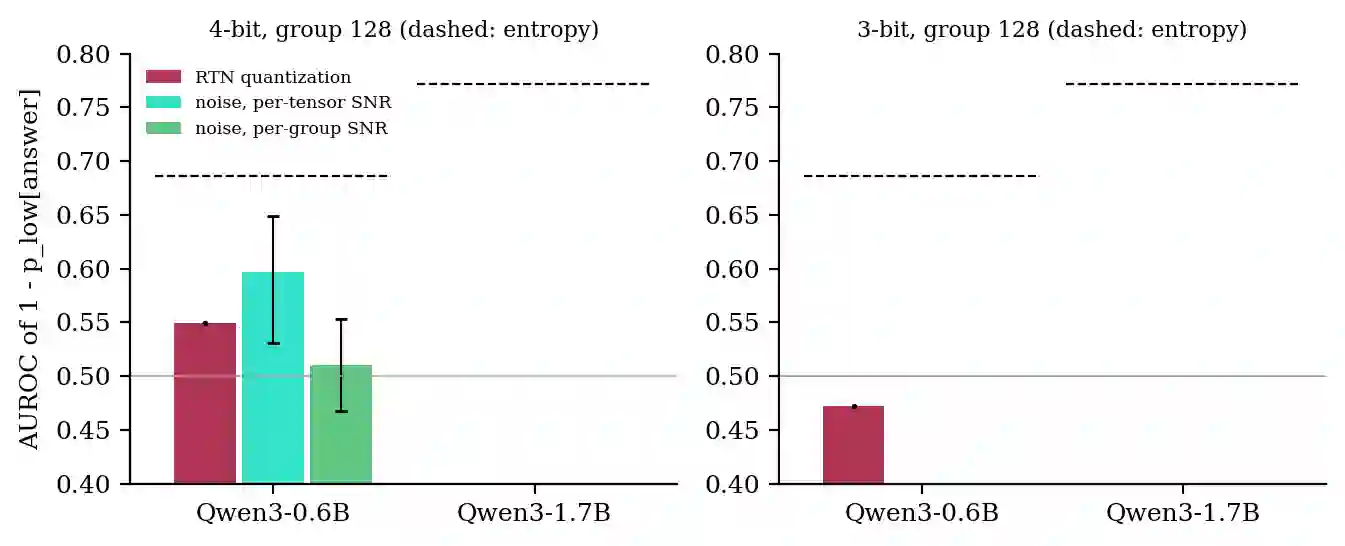
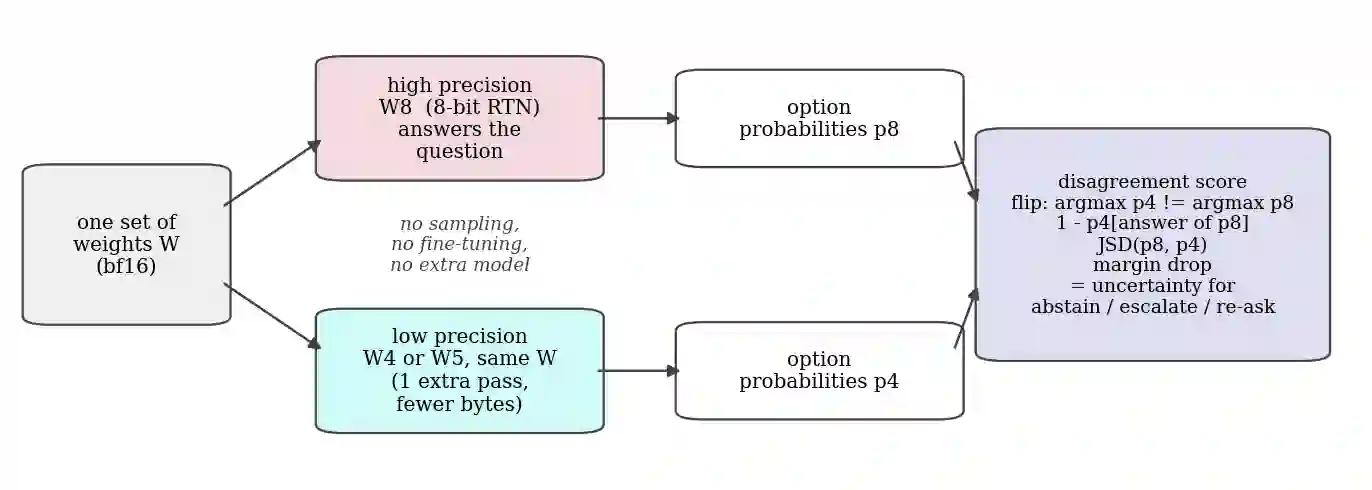
Local language models often exist at several precisions, and quantization is known to change individual answers. This study asks whether the disagreement between two precisions of the same weights, an 8-bit copy that answers and a lower-precision copy that reads the same prompt, works as a per-question error score for abstention, escalation and re-asking. The cost is one extra forward pass over fewer bytes, with no sampling and no training. We simulate round-to-nearest quantization with per-group scales (3 to 6 bits, groups of 32 to 256) on Qwen3-0.6B and Qwen3-1.7B and score 8,398 multiple-choice questions from ARC-Easy, ARC-Challenge, MMLU and HellaSwag subsets. Error detection is measured by AUROC, risk-coverage curves and ECE on a held-out half, with paired bootstrap intervals over questions. For Qwen3-0.6B, the entropy of the 8-bit answer reaches AUROC 0.682; the best disagreement score, selected on a development half, reaches 0.684 (+0.001 [-0.009, +0.011]), and combining it with the confidence features adds +0.009 [+0.002, +0.015], mostly on ARC. On Qwen3-1.7B the selected score is -0.001 [-0.009, +0.006] from entropy and the combination +0.003 [-0.001, +0.006] on the test half. Gaussian weight noise at matched error energy is about as informative as rounding (0.6B only), so we find no evidence that the signal is specific to quantization, and shuffling the features within task and entropy cells removes the gain. One extra 8-bit pass that shifts the option order does better (+0.049 [+0.031, +0.067] over entropy) at about a third more weight traffic; routing to a larger model on free entropy beats both extra-pass scores at equal total traffic. After logistic recalibration the 0.6B confidences are calibrated within a few points of ECE. A deployment recipe and the cases where the method does not help are given.


翻译:暂无翻译
0
下载
关闭预览

相关内容

ACM/IEEE第23届模型驱动工程语言和系统国际会议,是模型驱动软件和系统工程的首要会议系列,由ACM-SIGSOFT和IEEE-TCSE支持组织。自1998年以来,模型涵盖了建模的各个方面,从语言和方法到工具和应用程序。模特的参加者来自不同的背景,包括研究人员、学者、工程师和工业专业人士。MODELS 2019是一个论坛,参与者可以围绕建模和模型驱动的软件和系统交流前沿研究成果和创新实践经验。今年的版本将为建模社区提供进一步推进建模基础的机会,并在网络物理系统、嵌入式系统、社会技术系统、云计算、大数据、机器学习、安全、开源等新兴领域提出建模的创新应用以及可持续性。 官网链接:http://www.modelsconference.org/
【ICML2024】揭示Graph Transformers 中的过全局化问题
专知会员服务
21+阅读 · 2024年5月27日
论文荐读:理解图表示学习中的负采样
学术头条
29+阅读 · 2020年5月29日
绝对干货!NLP预训练模型:从transformer到albert
新智元
15+阅读 · 2019年11月10日
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
利用动态深度学习预测金融时间序列基于Python
量化投资与机器学习
18+阅读 · 2018年10月30日
论文浅尝 | 用可微的逻辑规则学习完成知识库推理
开放知识图谱
14+阅读 · 2018年7月5日
论文浅尝 | 基于知识图谱的子图匹配回答自然语言问题
开放知识图谱
27+阅读 · 2018年5月17日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
Arxiv
0+阅读 · 10月30日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
23+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
10+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
专知会员服务
10+阅读 · 11月8日
人工智能在军事教育中的应用:若干视角与经验
专知会员服务
11+阅读 · 11月6日
“星链”减速与不断适应的乌克兰
专知会员服务
9+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
6+阅读 · 11月6日
相关VIP内容
【ICML2024】揭示Graph Transformers 中的过全局化问题
专知会员服务
21+阅读 · 2024年5月27日
相关资讯
论文荐读:理解图表示学习中的负采样
学术头条
29+阅读 · 2020年5月29日
绝对干货!NLP预训练模型:从transformer到albert
新智元
15+阅读 · 2019年11月10日
强化学习三篇论文 避免遗忘等
CreateAMind
20+阅读 · 2019年5月24日
利用动态深度学习预测金融时间序列基于Python
量化投资与机器学习
18+阅读 · 2018年10月30日
论文浅尝 | 用可微的逻辑规则学习完成知识库推理
开放知识图谱
14+阅读 · 2018年7月5日
论文浅尝 | 基于知识图谱的子图匹配回答自然语言问题
开放知识图谱
27+阅读 · 2018年5月17日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
相关基金
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
1+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
Top
微信扫码咨询专知VIP会员