Word embedding has become ubiquitous and is widely used in various text mining and natural language processing (NLP) tasks, such as information retrieval, semantic analysis, and machine translation, among many others. Unfortunately, it is prohibitively expensive to train the word embedding in a relatively large corpus. We propose a graph-based word embedding algorithm, called Word-Graph2vec, which converts the large corpus into a word co-occurrence graph, then takes the word sequence samples from this graph by randomly traveling and trains the word embedding on this sampling corpus in the end. We posit that because of the stable vocabulary, relative idioms, and fixed expressions in English, the size and density of the word co-occurrence graph change slightly with the increase in the training corpus. So that Word-Graph2vec has stable runtime on the large scale data set, and its performance advantage becomes more and more obvious with the growth of the training corpus. Extensive experiments conducted on real-world datasets show that the proposed algorithm outperforms traditional Skip-Gram by four-five times in terms of efficiency, while the error generated by the random walk sampling is small.


翻译:词嵌入已成为文本挖掘和自然语言处理(NLP)任务中广泛应用的基础技术,包括信息检索、语义分析和机器翻译等众多领域。然而,在相对庞大的语料库上训练词嵌入的成本过高。我们提出一种基于图的词嵌入算法,名为Word-Graph2vec。该算法首先将大规模语料库转换为词共现图,然后通过随机游走从该图中采样词序列,最后在此采样语料库上训练词嵌入。我们假设,由于英语中稳定的词汇、惯用语和固定表达,词共现图的规模和密度会随着训练语料库的增加而发生微小变化。因此,Word-Graph2vec在大规模数据集上具有稳定的运行时间,且其性能优势随着训练语料库的增长而愈发显著。在真实数据集上进行的大量实验表明,该算法在效率上比传统Skip-Gram模型提高四到五倍,同时随机游走采样产生的误差较小。


0
下载
关闭预览

相关内容

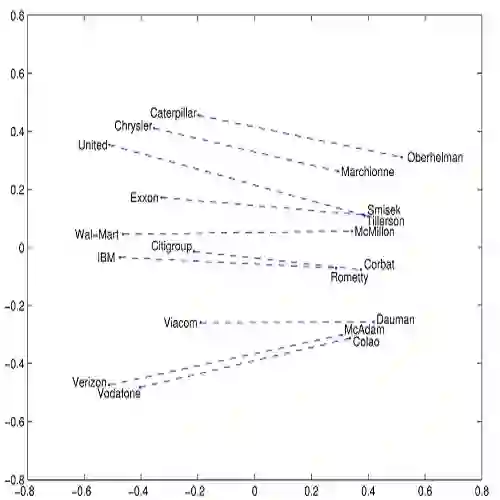
分散式表示即将语言表示为稠密、低维、连续的向量。 研究者最早发现学习得到词嵌入之间存在类比关系。比如apple−apples ≈ car−cars, man−woman ≈ king – queen 等。这些方法都可以直接在大规模无标注语料上进行训练。词嵌入的质量也非常依赖于上下文窗口大小的选择。通常大的上下文窗口学到的词嵌入更反映主题信息,而小的上下文窗口学到的词嵌入更反映词的功能和上下文语义信息。
Linux导论,Introduction to Linux,96页ppt
专知会员服务
82+阅读 · 2020年7月26日
FlowQA: Grasping Flow in History for Conversational Machine Comprehension
专知会员服务
35+阅读 · 2019年10月18日
《DeepGCNs: Making GCNs Go as Deep as CNNs》
专知会员服务
32+阅读 · 2019年10月17日
Keras François Chollet 《Deep Learning with Python 》, 386页pdf
专知会员服务
164+阅读 · 2019年10月12日
【SIGGRAPH2019】TensorFlow 2.0深度学习计算机图形学应用
专知会员服务
41+阅读 · 2019年10月9日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
meta learning 17年:MAML SNAIL
CreateAMind
11+阅读 · 2019年1月2日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
STRCF for Visual Object Tracking
统计学习与视觉计算组
15+阅读 · 2018年5月29日
IJCAI | Cascade Dynamics Modeling with Attention-based RNN
KingsGarden
13+阅读 · 2017年7月16日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
6+阅读 · 2014年12月31日
VIP会员
最新内容
世界模型入门:从序贯决策到通用智能体
专知会员服务
8+阅读 · 10月24日
军事域更好使用人工智能的实用指南
专知会员服务
10+阅读 · 10月22日
《衡量语言模型中的作战规划能力》
专知会员服务
14+阅读 · 10月20日
Maven智能系统:帕兰提尔军事人工智能平台详解
专知会员服务
17+阅读 · 10月20日
《测试自动化框架在敏捷软件开发中的角色》
专知会员服务
9+阅读 · 10月20日
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
13+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
19+阅读 · 10月15日
相关资讯
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
meta learning 17年:MAML SNAIL
CreateAMind
11+阅读 · 2019年1月2日
disentangled-representation-papers
CreateAMind
26+阅读 · 2018年9月12日
STRCF for Visual Object Tracking
统计学习与视觉计算组
15+阅读 · 2018年5月29日
IJCAI | Cascade Dynamics Modeling with Attention-based RNN
KingsGarden
13+阅读 · 2017年7月16日
相关基金
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
3+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
2+阅读 · 2014年12月31日
国家自然科学基金
6+阅读 · 2014年12月31日
Top
微信扫码咨询专知VIP会员