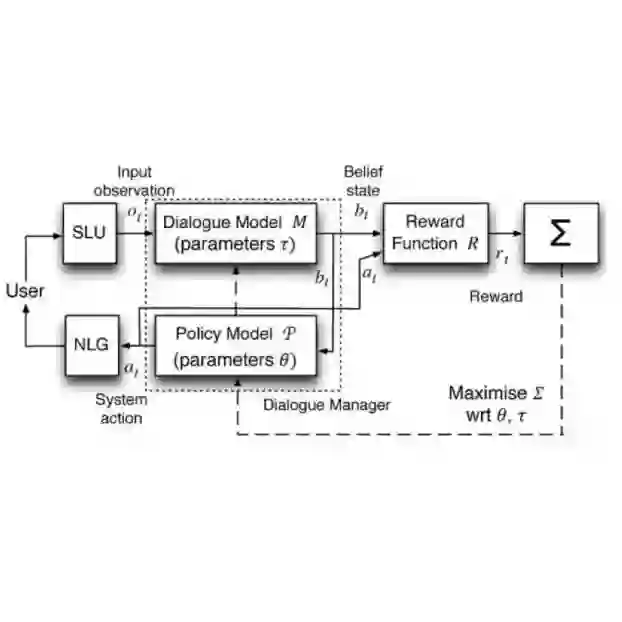
Multi-turn tool-using agents must coordinate long-horizon tool sequences while tracking dialogue state and policy constraints. Existing approaches often separate inference-time orchestration from parameter-level learning, leaving tool selection weakly structured and preference updates vulnerable to train--deployment prompt mismatch. For within-benchmark self-improvement, ToolGraph combines schema-derived topology, transition weights estimated from successful rollouts, and history-aware controls for write prerequisites and repeated-search loops. We then construct 161 preference pairs by locating divergence points via state-based matching and prefix-based alignment, filtered through action-correctness annotations, and train DPO under the same ToolGraph context used at inference. Across 375 tau2-bench tasks, ToolGraph raises the weighted average reward from 0.304 to 0.338 (+11.2% relative), while ToolGraph+DPO reaches 0.355 (+16.8% over the baseline), with the DPO gain concentrated in airline and retail. Fine-grained diagnostics further show that roughly half of telecom trajectories exhaust the step budget before action execution and that chosen reward positivity is the most useful checkpoint signal across our 16 evaluated DPO configurations.


翻译:暂无翻译

0
下载
关闭预览

相关内容

Agent视域下的人工智能赋能作战系统
专知会员服务
61+阅读 · 2024年12月15日
基于Multi-Agent的无人机集群体系自主作战系统设计
专知会员服务
76+阅读 · 2024年4月8日
作战 Agent 的学习算法研究进展与发展趋势
专知会员服务
72+阅读 · 2023年10月3日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
半监督多任务学习:Semisupervised Multitask Learning
我爱读PAMI
18+阅读 · 2018年4月29日
读书报告 | Deep Learning for Extreme Multi-label Text Classification
科技创新与创业
48+阅读 · 2018年1月10日
论文笔记:多任务相关粒子滤波跟踪器
统计学习与视觉计算组
10+阅读 · 2017年7月7日
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
47+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
24+阅读 · 2011年12月31日
国家自然科学基金
18+阅读 · 2009年12月31日
Arxiv
10+阅读 · 2022年2月25日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
11+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
4+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
7+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
4+阅读 · 11月6日
相关VIP内容
Agent视域下的人工智能赋能作战系统
专知会员服务
61+阅读 · 2024年12月15日
基于Multi-Agent的无人机集群体系自主作战系统设计
专知会员服务
76+阅读 · 2024年4月8日
作战 Agent 的学习算法研究进展与发展趋势
专知会员服务
72+阅读 · 2023年10月3日
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关基金
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2015年12月31日
国家自然科学基金
47+阅读 · 2015年12月31日
国家自然科学基金
2+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
19+阅读 · 2012年12月31日
国家自然科学基金
24+阅读 · 2011年12月31日
国家自然科学基金
18+阅读 · 2009年12月31日
Top
微信扫码咨询专知VIP会员