

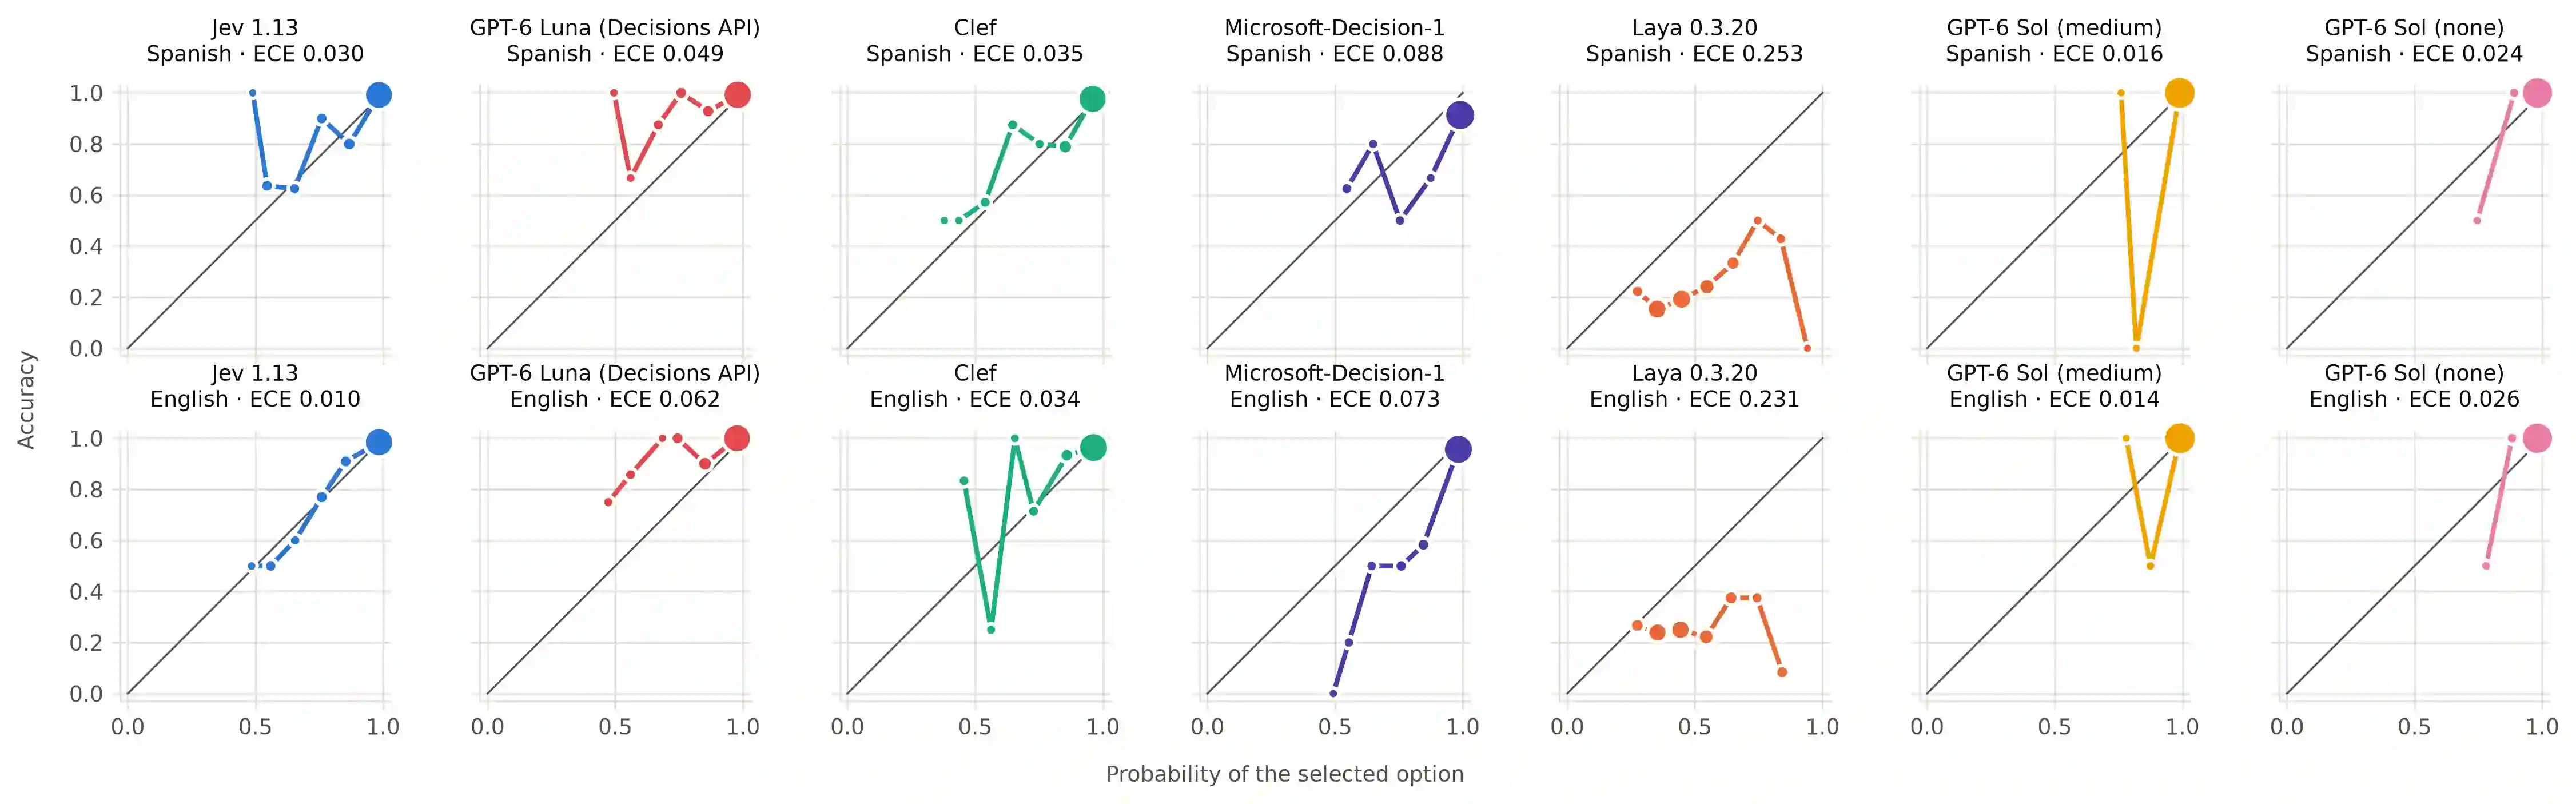
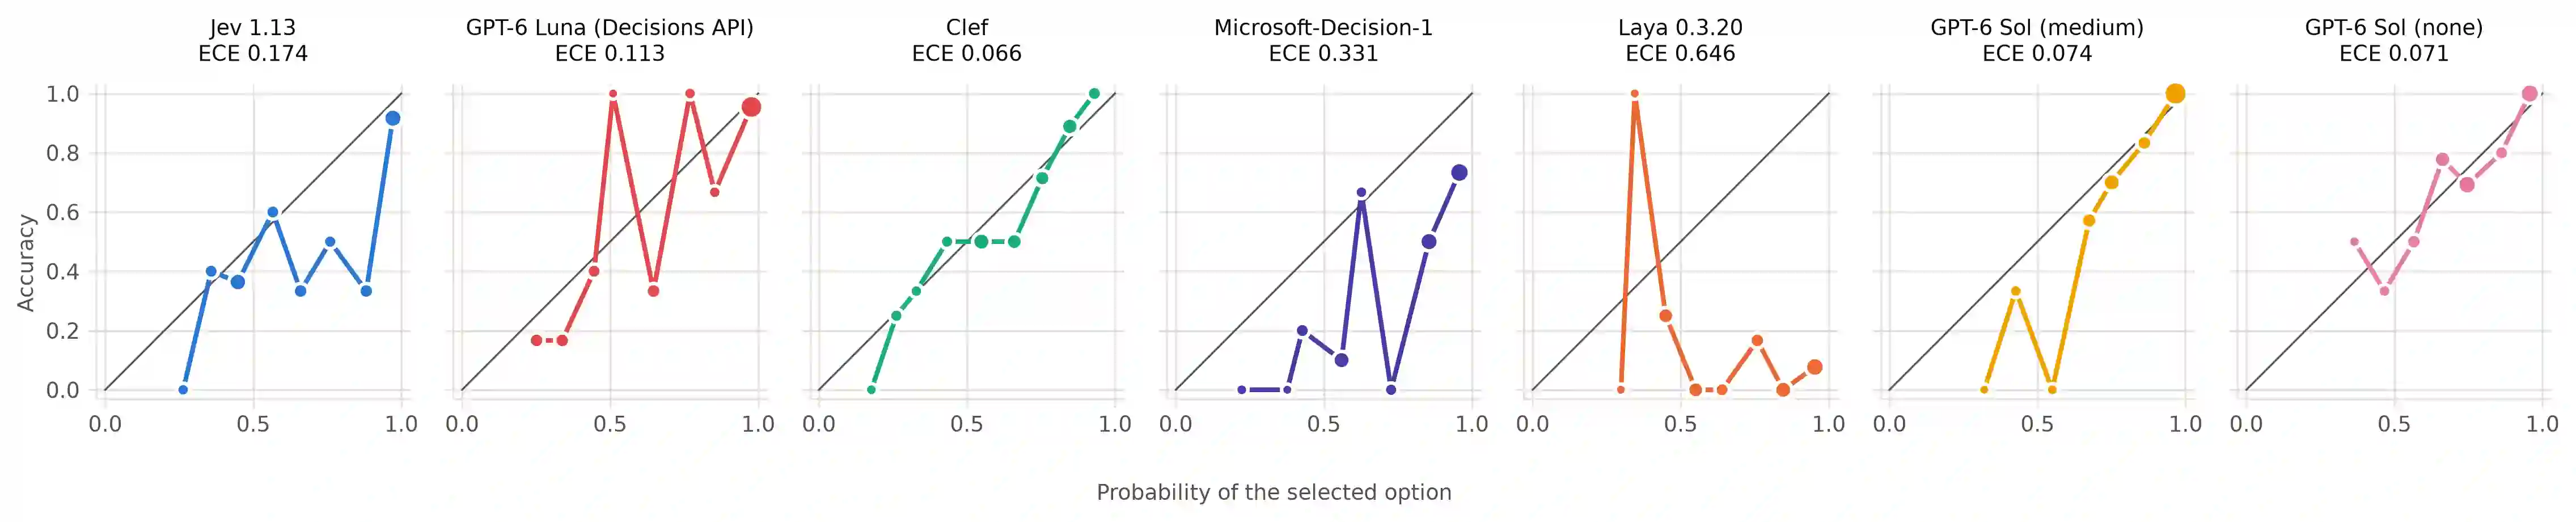
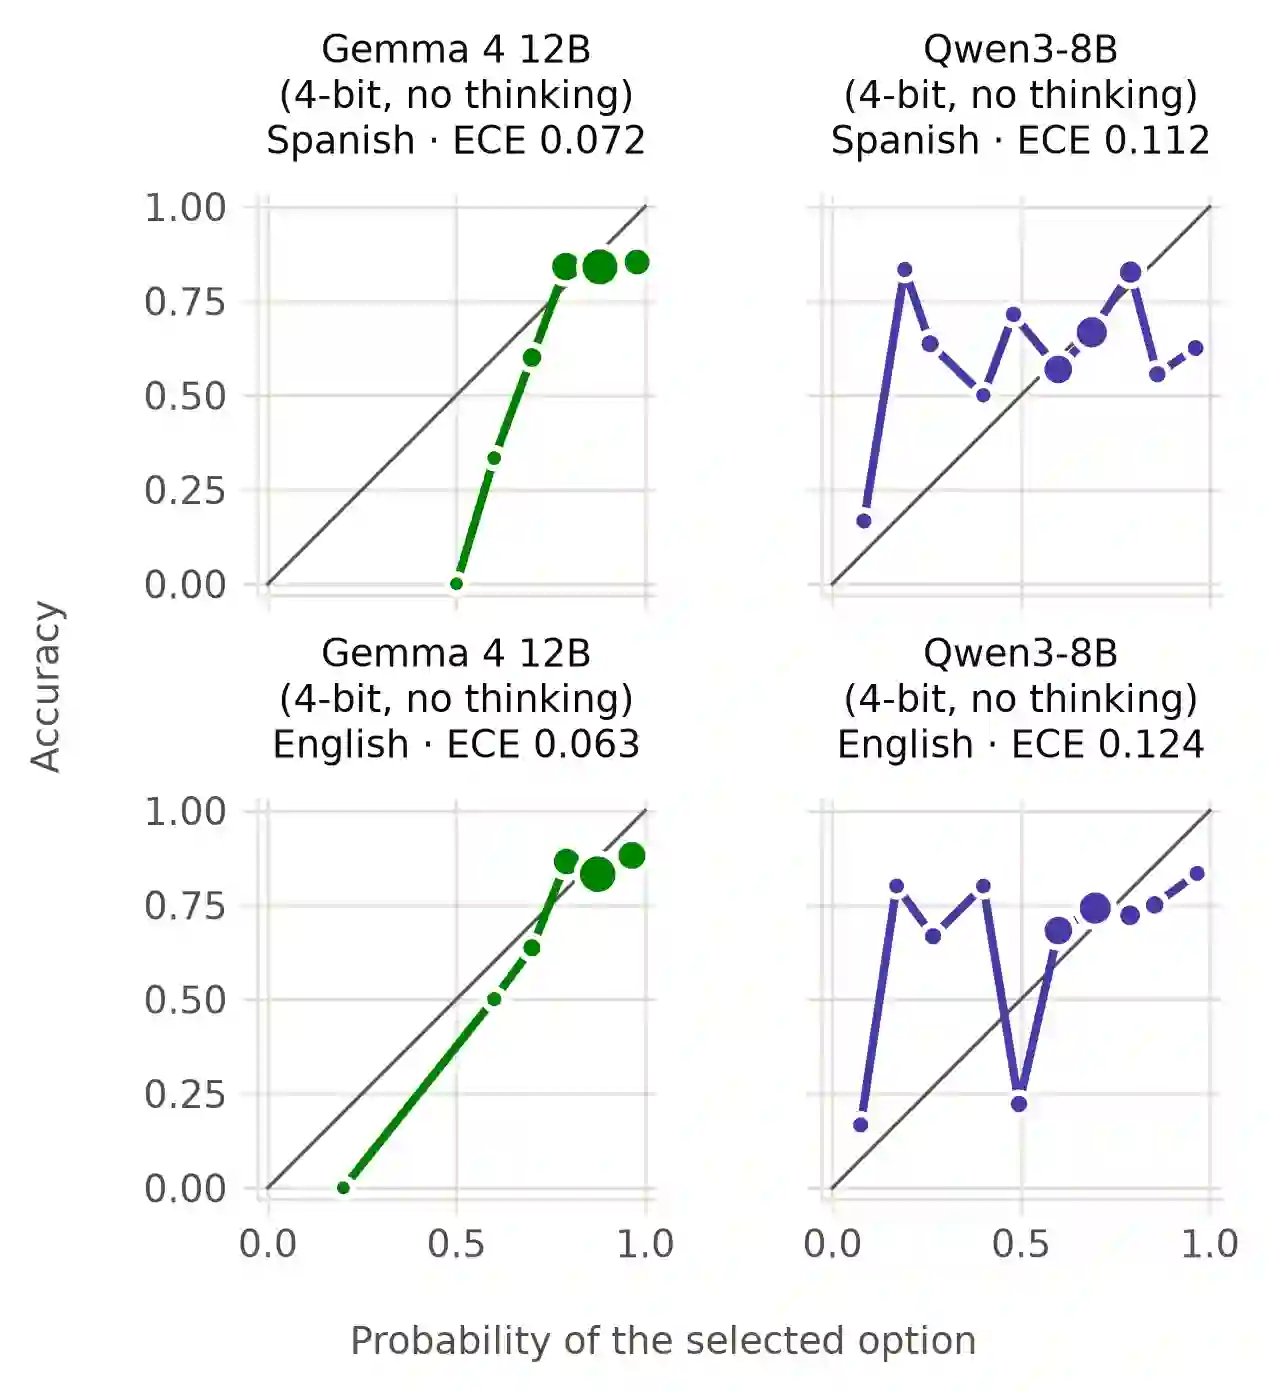
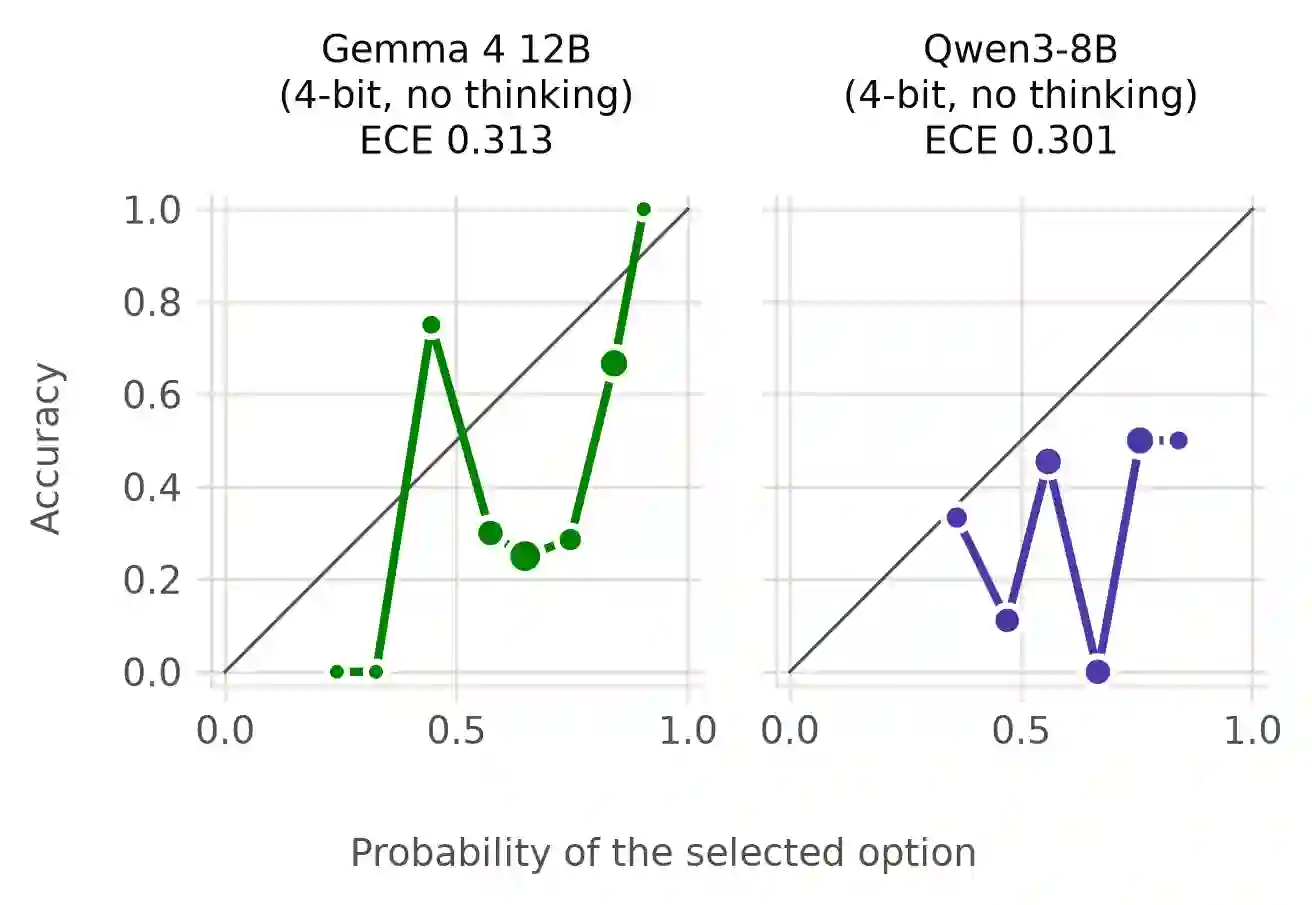
Objectives: To evaluate the accuracy and calibration of Decision and System One models on rheumatology examination questions and diagnostic vignettes. Methods: Two benchmarks were analysed: 172 rheumatology questions from Spanish specialty-training examinations (expanded RheumaMIR dataset) in Spanish and English, and 70 English diagnostic vignettes from RheumBench with 5-18 candidate diagnoses, 52 of which included the reference diagnosis. Four System One models (Jev 1.13, Clef, Microsoft-Decision-1, Laya) and GPT-6 Luna (OpenAI Decisions API) were compared with GPT-6 Sol and two local generative models. The primary outcome was accuracy; secondary outcomes included calibration, discrimination, accuracy of answers with probability >=0.90 and language differences. Results: In RheumaMIR, Jev's accuracy was 93.0% in Spanish and 91.9% in English, below GPT-6 Sol (99.4%; Holm-adjusted P<=0.005); GPT-6 Luna reached 97.7%, Clef 91.9-93.0% and Microsoft-Decision-1 86.0-87.8%, without detectable language differences. Jev's answers with probability >=0.90 (76-77% of answers) were 98.5% correct. In RheumBench, accuracy was lower: GPT-6 Sol 76.9%, GPT-6 Luna 63.5%, Clef 59.6%, Jev 50.0% and Microsoft-Decision-1 40.4% (each System One model below GPT-6 Sol, Holm-adjusted P<=0.045; chance 9.6%). Jev became overconfident (mean probability 0.659; over/underconfidence index +0.159), and its answers with probability >=0.90 (25% of cases) were 84.6% correct, against 95.5% for GPT-6 Luna (42%). Laya performed near chance in both benchmarks. Conclusion: The best-performing System One models were highly accurate on examination questions but less accurate on diagnostic vignettes, remaining below GPT-6 Sol. Jev's high-confidence predictions were less reliable on vignettes, highlighting the need for task-specific evaluation and calibration.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员