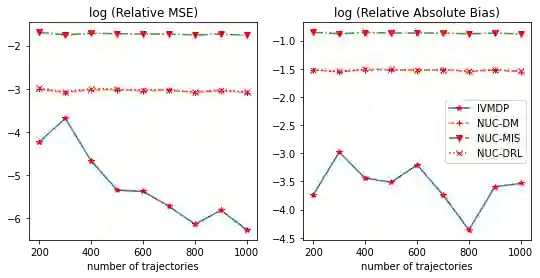
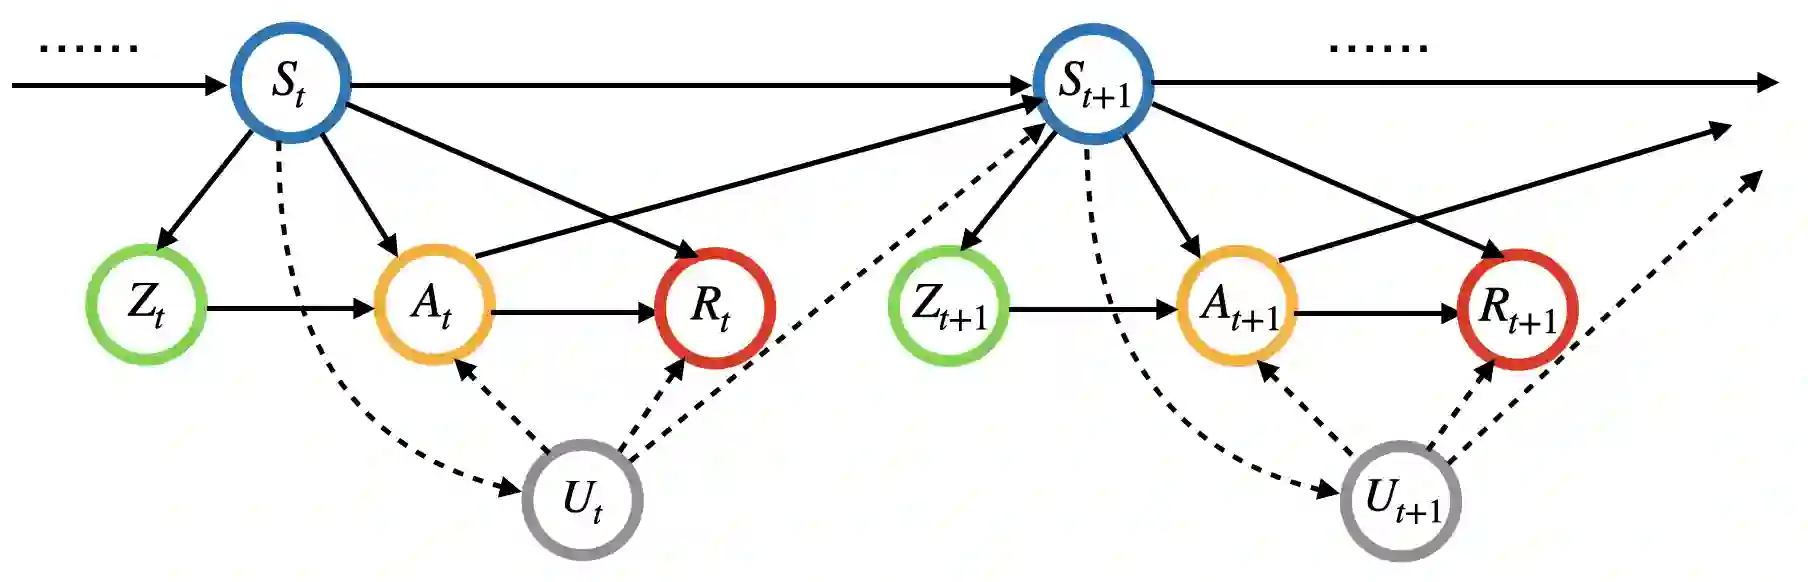
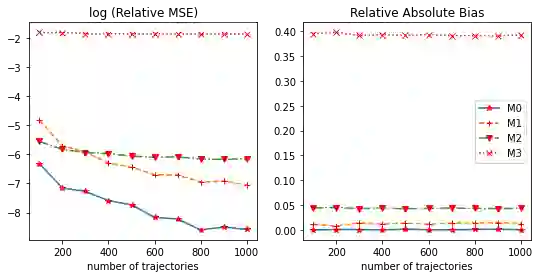
Off-policy evaluation (OPE) is a method for estimating the return of a target policy using some pre-collected observational data generated by a potentially different behavior policy. In some cases, there may be unmeasured variables that can confound the action-reward or action-next-state relationships, rendering many existing OPE approaches ineffective. This paper develops an instrumental variable (IV)-based method for consistent OPE in confounded Markov decision processes (MDPs). Similar to single-stage decision making, we show that IV enables us to correctly identify the target policy's value in infinite horizon settings as well. Furthermore, we propose an efficient and robust value estimator and illustrate its effectiveness through extensive simulations and analysis of real data from a world-leading short-video platform.


翻译:离策略评估(OPE)是一种利用由潜在不同行为策略生成的预收集观测数据来估计目标策略回报的方法。在某些情况下,可能存在未观测变量混淆行动-奖励或行动-下一状态关系,导致许多现有OPE方法失效。本文提出了一种基于工具变量(IV)的混杂马尔可夫决策过程(MDPs)中一致OPE方法。与单阶段决策类似,我们证明IV能够正确识别无限时域设定下目标策略的价值。此外,我们提出了一种高效且稳健的价值估计器,并通过大规模仿真实验和来自全球领先短视频平台的真实数据分析验证了其有效性。
0
下载
关闭预览

相关内容

【ICDM 2022教程】图挖掘中的公平性:度量、算法和应用
专知会员服务
29+阅读 · 2022年12月26日
不可错过!700+ppt《因果推理》课程!杜克大学Fan Li教程
专知会员服务
73+阅读 · 2022年7月11日
不可错过!《机器学习100讲》课程,UBC Mark Schmidt讲授
专知会员服务
76+阅读 · 2022年6月28日
专知会员服务
55+阅读 · 2020年9月7日
Linux导论,Introduction to Linux,96页ppt
专知会员服务
82+阅读 · 2020年7月26日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
VCIP 2022 Call for Demos
CCF多媒体专委会
1+阅读 · 2022年6月6日
VCIP 2022 Call for Special Session Proposals
CCF多媒体专委会
1+阅读 · 2022年4月1日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
强化学习族谱
CreateAMind
26+阅读 · 2017年8月2日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
7+阅读 · 2012年12月31日
国家自然科学基金
26+阅读 · 2011年12月31日
国家自然科学基金
0+阅读 · 2008年12月31日
Arxiv
66+阅读 · 2021年6月18日
VIP会员
最新内容
军事域更好使用人工智能的实用指南
专知会员服务
6+阅读 · 10月22日
《衡量语言模型中的作战规划能力》
专知会员服务
12+阅读 · 10月20日
Maven智能系统:帕兰提尔军事人工智能平台详解
专知会员服务
14+阅读 · 10月20日
《测试自动化框架在敏捷软件开发中的角色》
专知会员服务
8+阅读 · 10月20日
俄罗斯如何拦截乌克兰无人机与巡航导弹
专知会员服务
12+阅读 · 10月15日
《武器-目标分配问题:精确与近似求解算法》
专知会员服务
16+阅读 · 10月15日
现代电磁战:集成式系统簇时代如何实现频谱优势
相关VIP内容
【ICDM 2022教程】图挖掘中的公平性:度量、算法和应用
专知会员服务
29+阅读 · 2022年12月26日
不可错过!700+ppt《因果推理》课程!杜克大学Fan Li教程
专知会员服务
73+阅读 · 2022年7月11日
不可错过!《机器学习100讲》课程,UBC Mark Schmidt讲授
专知会员服务
76+阅读 · 2022年6月28日
专知会员服务
55+阅读 · 2020年9月7日
Linux导论,Introduction to Linux,96页ppt
专知会员服务
82+阅读 · 2020年7月26日
强化学习最新教程,17页pdf
专知会员服务
182+阅读 · 2019年10月11日
相关资讯
VCIP 2022 Call for Demos
CCF多媒体专委会
1+阅读 · 2022年6月6日
VCIP 2022 Call for Special Session Proposals
CCF多媒体专委会
1+阅读 · 2022年4月1日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
Transferring Knowledge across Learning Processes
CreateAMind
29+阅读 · 2019年5月18日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
A Technical Overview of AI & ML in 2018 & Trends for 2019
待字闺中
18+阅读 · 2018年12月24日
【论文】变分推断(Variational inference)的总结
机器学习研究会
39+阅读 · 2017年11月16日
强化学习族谱
CreateAMind
26+阅读 · 2017年8月2日
相关基金
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
3+阅读 · 2014年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
0+阅读 · 2013年12月31日
国家自然科学基金
7+阅读 · 2012年12月31日
国家自然科学基金
26+阅读 · 2011年12月31日
国家自然科学基金
0+阅读 · 2008年12月31日
Top
微信扫码咨询专知VIP会员