

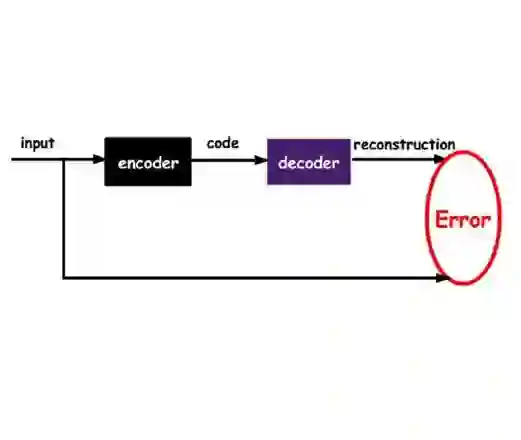
Manipulating the structure of data in the latent space of an autoencoder is a long-standing goal of representation learning. We propose a simple regularization, Manifold Matching, that imposes an explicit geometric structure on that latent space. The idea is to take a reference representation R of the data, which need not be the raw input X fed to the network, and to minimize, batch-wise, the mean squared error between the pairwise distances in R and those in the latent space Z. Although the autoencoder still learns to reconstruct X, the shape of its latent space comes to mimic that of R. The objective requires no labels, only reference distances, and because those are scalars, the dimensionality of R is decoupled from that of Z: any reference can guide any bottleneck. Using this single instrument we study how different geometric structures can be imposed on a latent space, comparing against autoencoders built on geometric or topological regularizers. Across fifteen datasets under a shared protocol with statistical testing, the resulting Manifold-Matching Autoencoder (MMAE) matches the global-structure quality of persistence-based autoencoders, statistically tying RTD-AE on distance correlation and triplet accuracy, and stays competitive on the local and topological metrics that other methods lead, at the computational cost of a plain autoencoder: it uses only a batched distance loss, with no persistence computation. We frame MMAE not as a universal winner but as an efficient and controllable regularizer whose reference selects which structure the latent inherits, and which turns any fixed embedding into a reusable out-of-sample encoder. All experiments use a two-dimensional bottleneck.
翻译:暂无翻译


相关内容



 微信扫码咨询专知VIP会员