

In this work, we explore whether LLMs can predict and explain plausible materials for vehicle components such as brake discs or fuel injectors without extensive fine-tuning. We compare a standard generative LLM baseline, single-pass Retrieval-Augmented Generation (RAG), and an iterative Chain-of-Verification (CoVe) variant across two LLMs, using a domain-filtered Wikipedia corpus that proved helpful in prior work. As no gold standard exists, we develop and release a reusable web-based annotation tool supporting crucial functions for structured domain-expert judgments, such as highlighting, ratings and ranking. Expert agreement is reasonable for plausibility, lower for ratings. LLM-based generation compares favorably to prior work. RAG and CoVe do not improve on it and are partly rated worse by experts. Contrary to prior work, Wikipedia-based retrieval does not help in our setup.
翻译:暂无翻译


相关内容
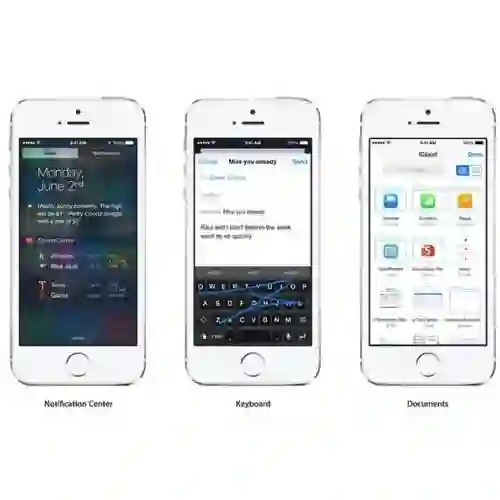
- Today (iOS and OS X): widgets for the Today view of Notification Center
- Share (iOS and OS X): post content to web services or share content with others
- Actions (iOS and OS X): app extensions to view or manipulate inside another app
- Photo Editing (iOS): edit a photo or video in Apple's Photos app with extensions from a third-party apps
- Finder Sync (OS X): remote file storage in the Finder with support for Finder content annotation
- Storage Provider (iOS): an interface between files inside an app and other apps on a user's device
- Custom Keyboard (iOS): system-wide alternative keyboards
Source: iOS 8 Extensions: Apple’s Plan for a Powerful App Ecosystem


 微信扫码咨询专知VIP会员