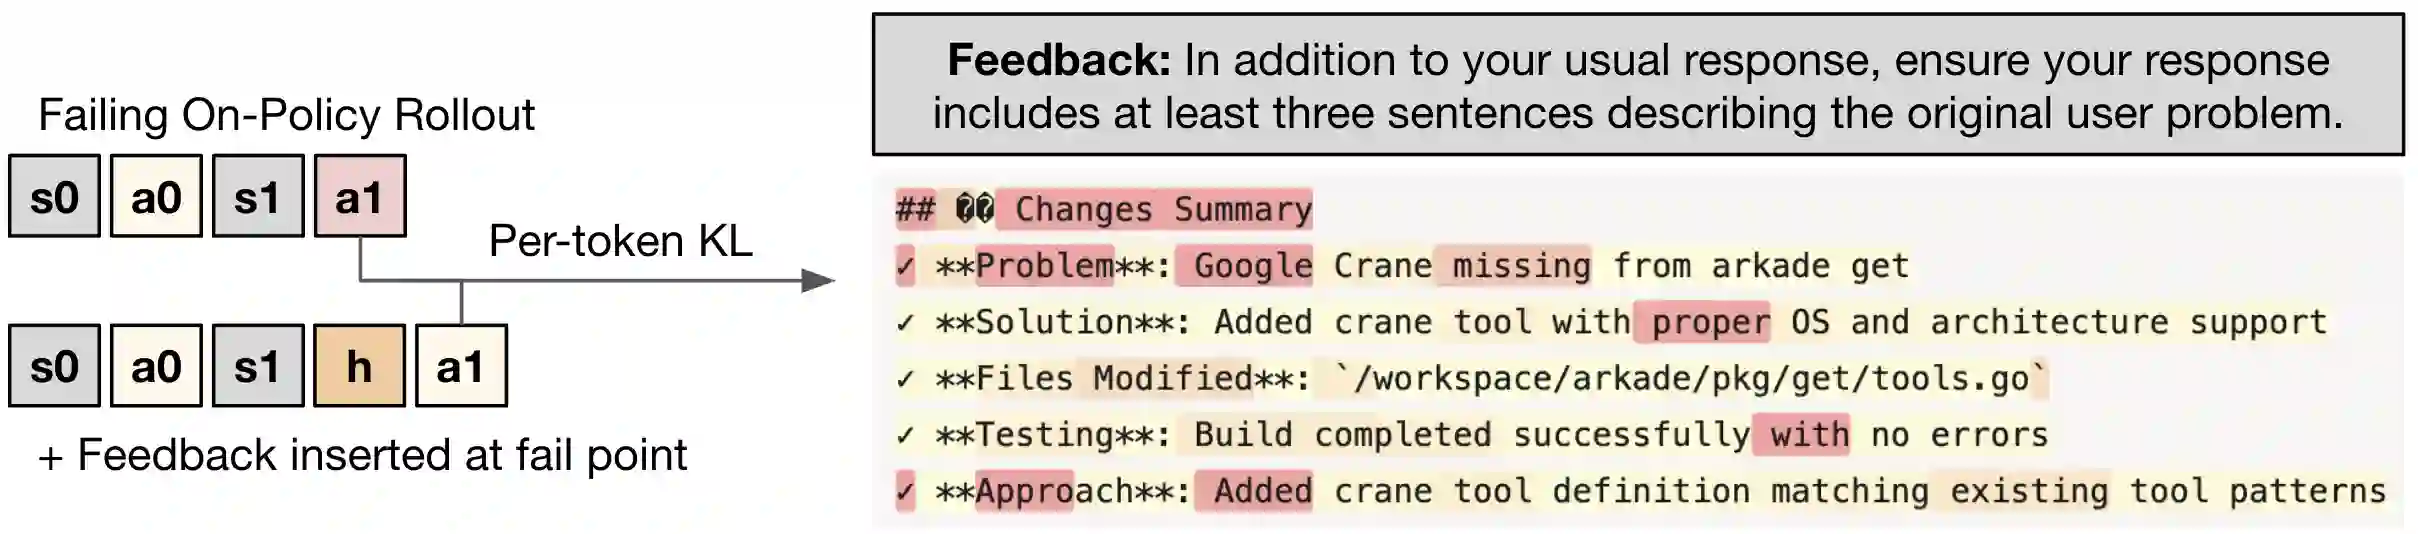
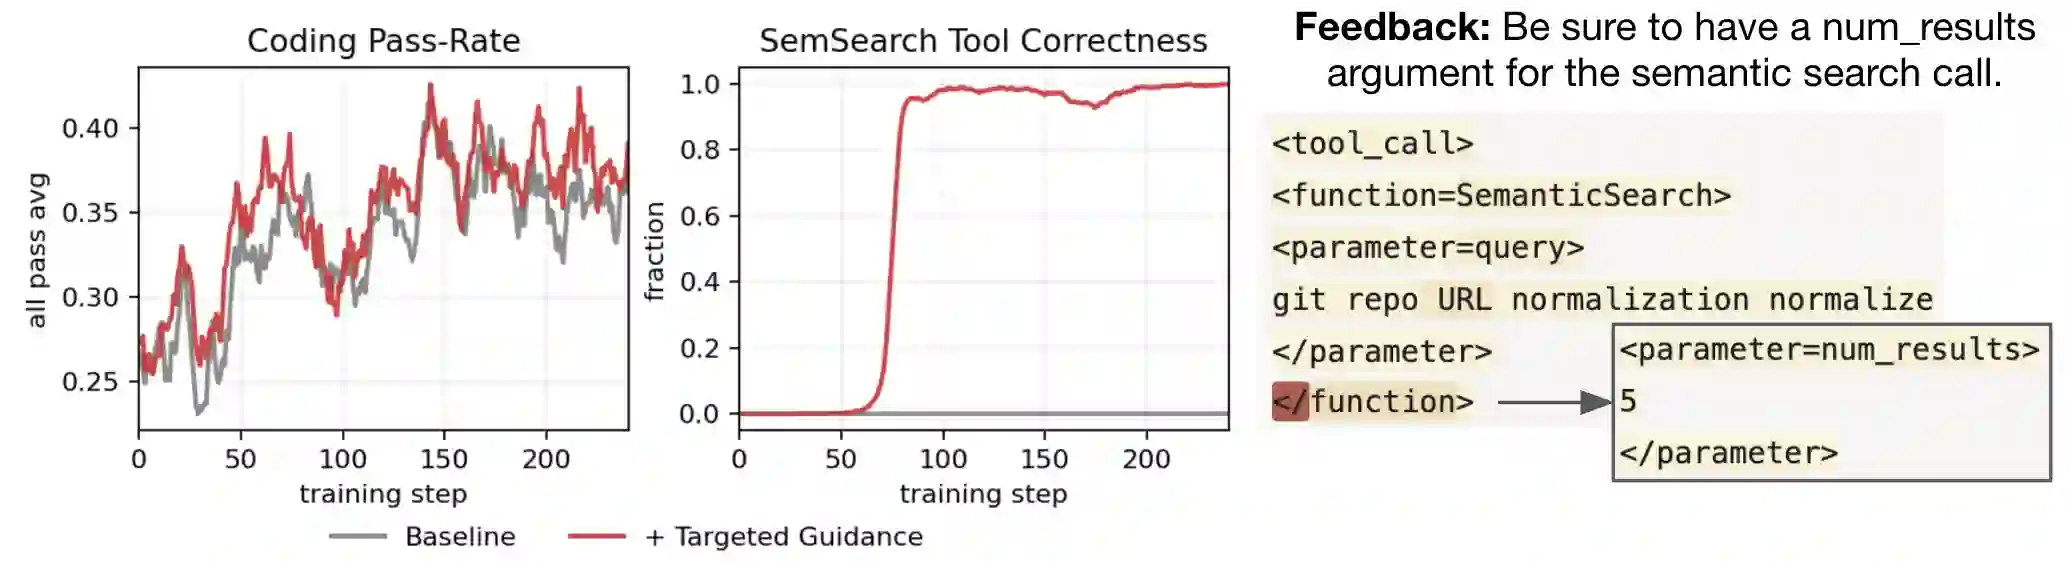
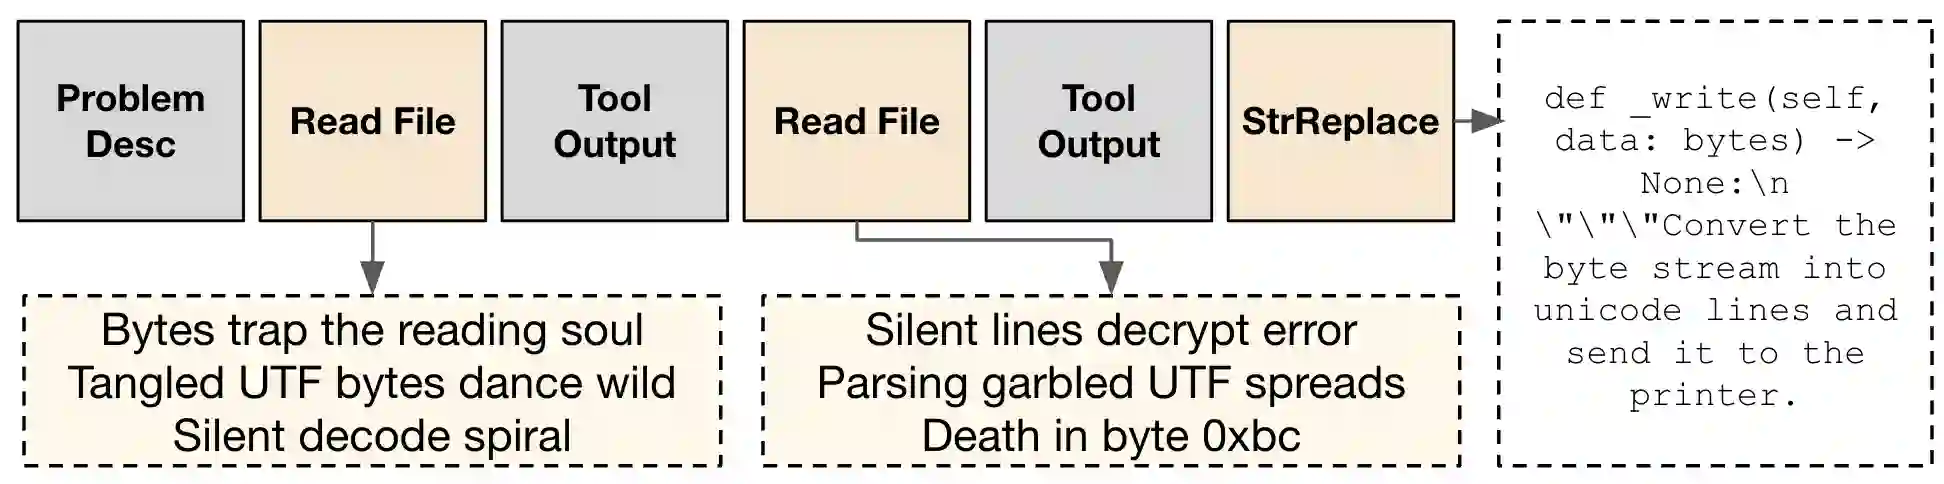
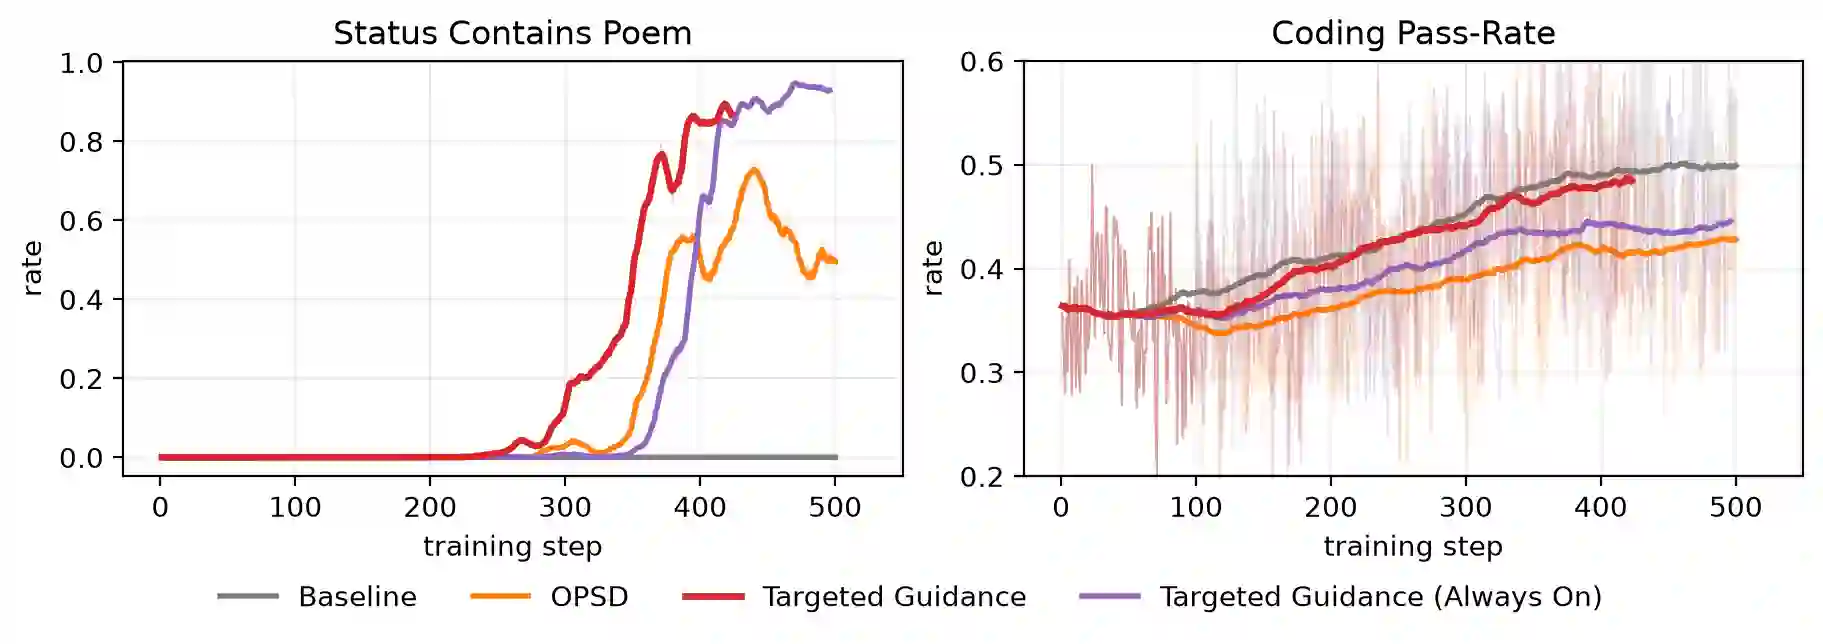
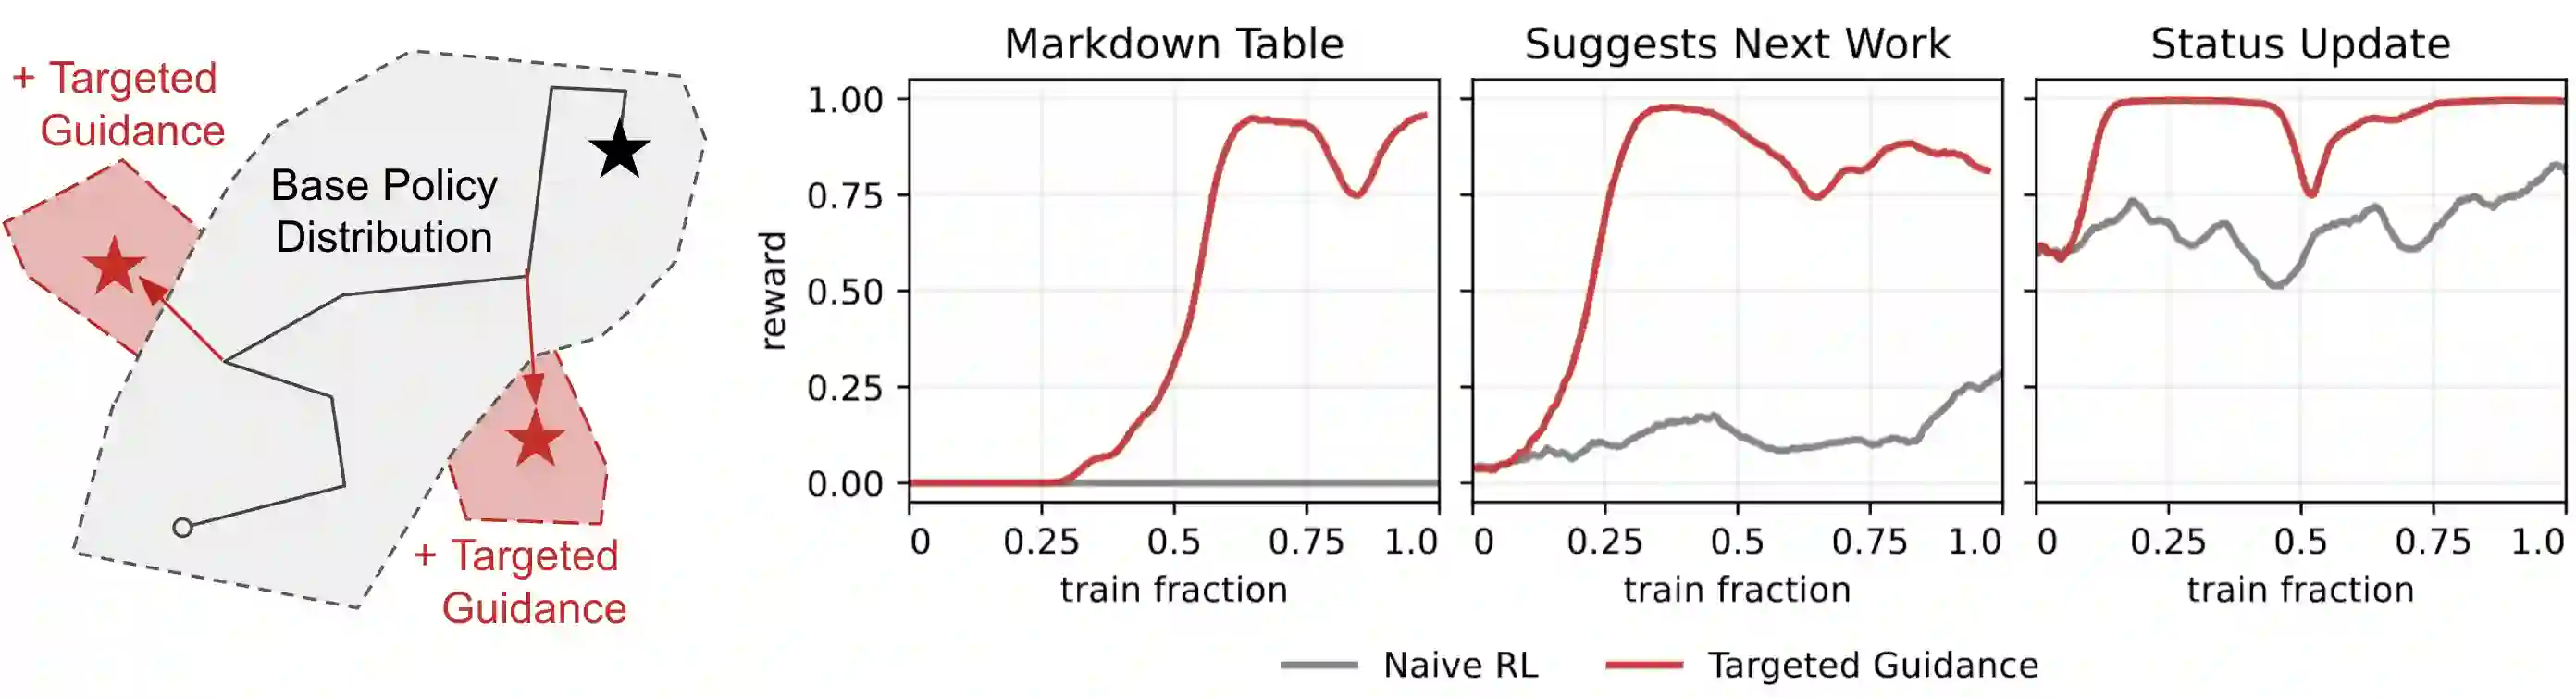
Naive on-policy RL is often bottlenecked by the capabilities of the base model --- insufficient coverage can result in an inability to learn from certain rewards. At the same time, rewards in modern post-training systems often come from rich textual sources, e.g. judge models with a rubric of criteria. Can we utilize such structures to provide a rich directional signal that enables improving on otherwise difficult to optimize rewards? In this work, we examine a framework we refer to as targeted guidance that learns from per-turn textual feedback via an on-policy self-distillation objective. Our focus is not only on directly improving hard-to-optimize behaviors, but on how to do so throughout the training process without degrading baseline RL performance. Over a range of settings across an agentic multi-turn software engineering environment, we find success by combining targeted self-distillation with a per-criteria RL reward, and by limiting feedback to turns where the policy specifically fails. We further examine the design choices that lead to stable entropy and reduce oscillatory behavior throughout training.


翻译:暂无翻译
0
下载
关闭预览

相关内容

Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
半监督多任务学习:Semisupervised Multitask Learning
我爱读PAMI
18+阅读 · 2018年4月29日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
Focal Loss for Dense Object Detection
统计学习与视觉计算组
12+阅读 · 2018年3月15日
原创 | Attention Modeling for Targeted Sentiment
黑龙江大学自然语言处理实验室
25+阅读 · 2017年11月5日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
4+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
Arxiv
0+阅读 · 11月6日
VIP会员
最新内容
《美空军2026条令文件:对海压制作战》
专知会员服务
18+阅读 · 11月9日
人工智能与战争的未来
专知会员服务
6+阅读 · 11月8日
《Agent Mosaic:识别智能体LLM系统中的机密泄露》
人工智能在军事教育中的应用:若干视角与经验
“星链”减速与不断适应的乌克兰
专知会员服务
8+阅读 · 11月6日
美国中期选举之后:帕兰提尔面临不确定性?
专知会员服务
5+阅读 · 11月6日
相关VIP内容
Stabilizing Transformers for Reinforcement Learning
专知会员服务
61+阅读 · 2019年10月17日
相关资讯
Hierarchically Structured Meta-learning
CreateAMind
27+阅读 · 2019年5月22日
强化学习的Unsupervised Meta-Learning
CreateAMind
18+阅读 · 2019年1月7日
Unsupervised Learning via Meta-Learning
CreateAMind
44+阅读 · 2019年1月3日
李宏毅-201806-中文-Deep Reinforcement Learning精品课程分享
深度学习与NLP
15+阅读 · 2018年6月20日
Hierarchical Imitation - Reinforcement Learning
CreateAMind
19+阅读 · 2018年5月25日
半监督多任务学习:Semisupervised Multitask Learning
我爱读PAMI
18+阅读 · 2018年4月29日
Reinforcement Learning: An Introduction 2018第二版 500页
CreateAMind
14+阅读 · 2018年4月27日
Focal Loss for Dense Object Detection
统计学习与视觉计算组
12+阅读 · 2018年3月15日
原创 | Attention Modeling for Targeted Sentiment
黑龙江大学自然语言处理实验室
25+阅读 · 2017年11月5日
相关基金
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
4+阅读 · 2015年12月31日
国家自然科学基金
5+阅读 · 2015年12月31日
国家自然科学基金
20+阅读 · 2015年12月31日
国家自然科学基金
24+阅读 · 2015年12月31日
国家自然科学基金
0+阅读 · 2014年12月31日
国家自然科学基金
4+阅读 · 2014年12月31日
国家自然科学基金
11+阅读 · 2012年12月31日
国家自然科学基金
18+阅读 · 2012年12月31日
Top
微信扫码咨询专知VIP会员