

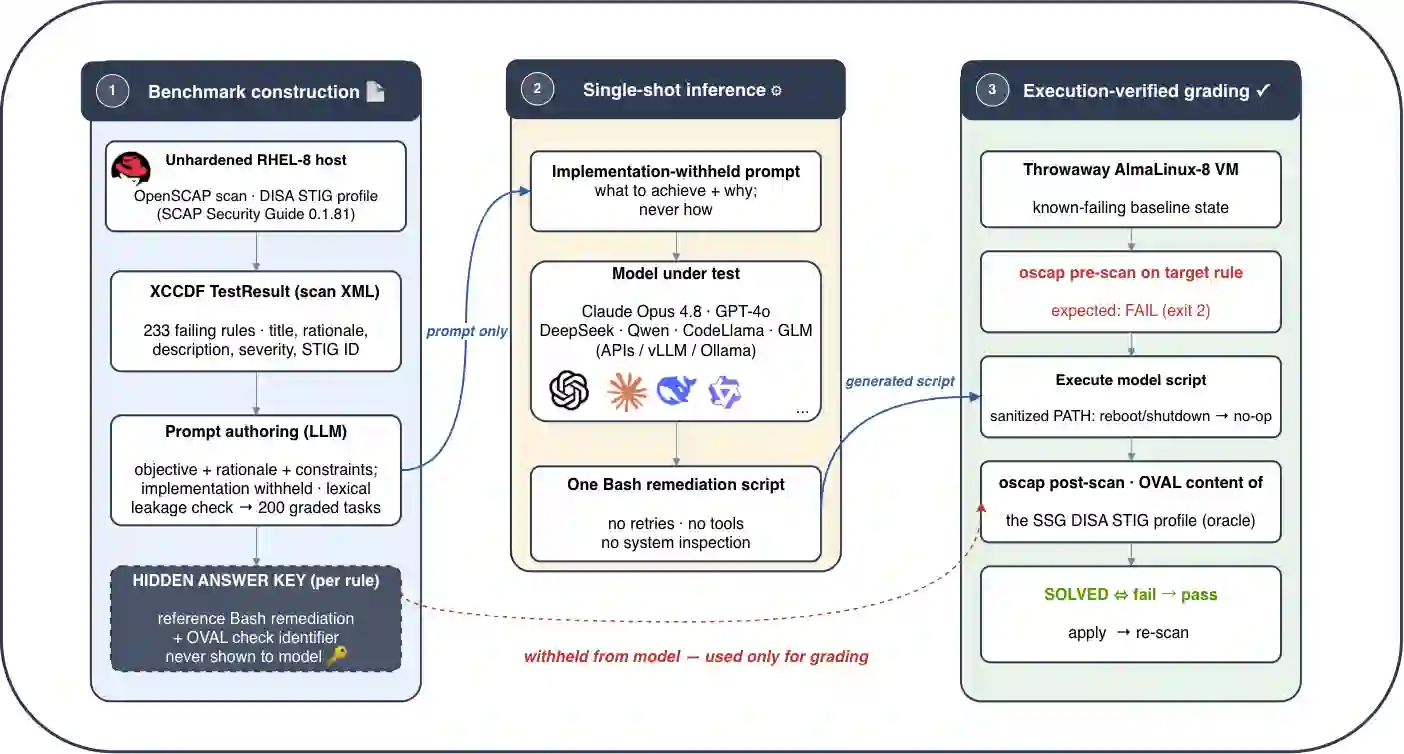
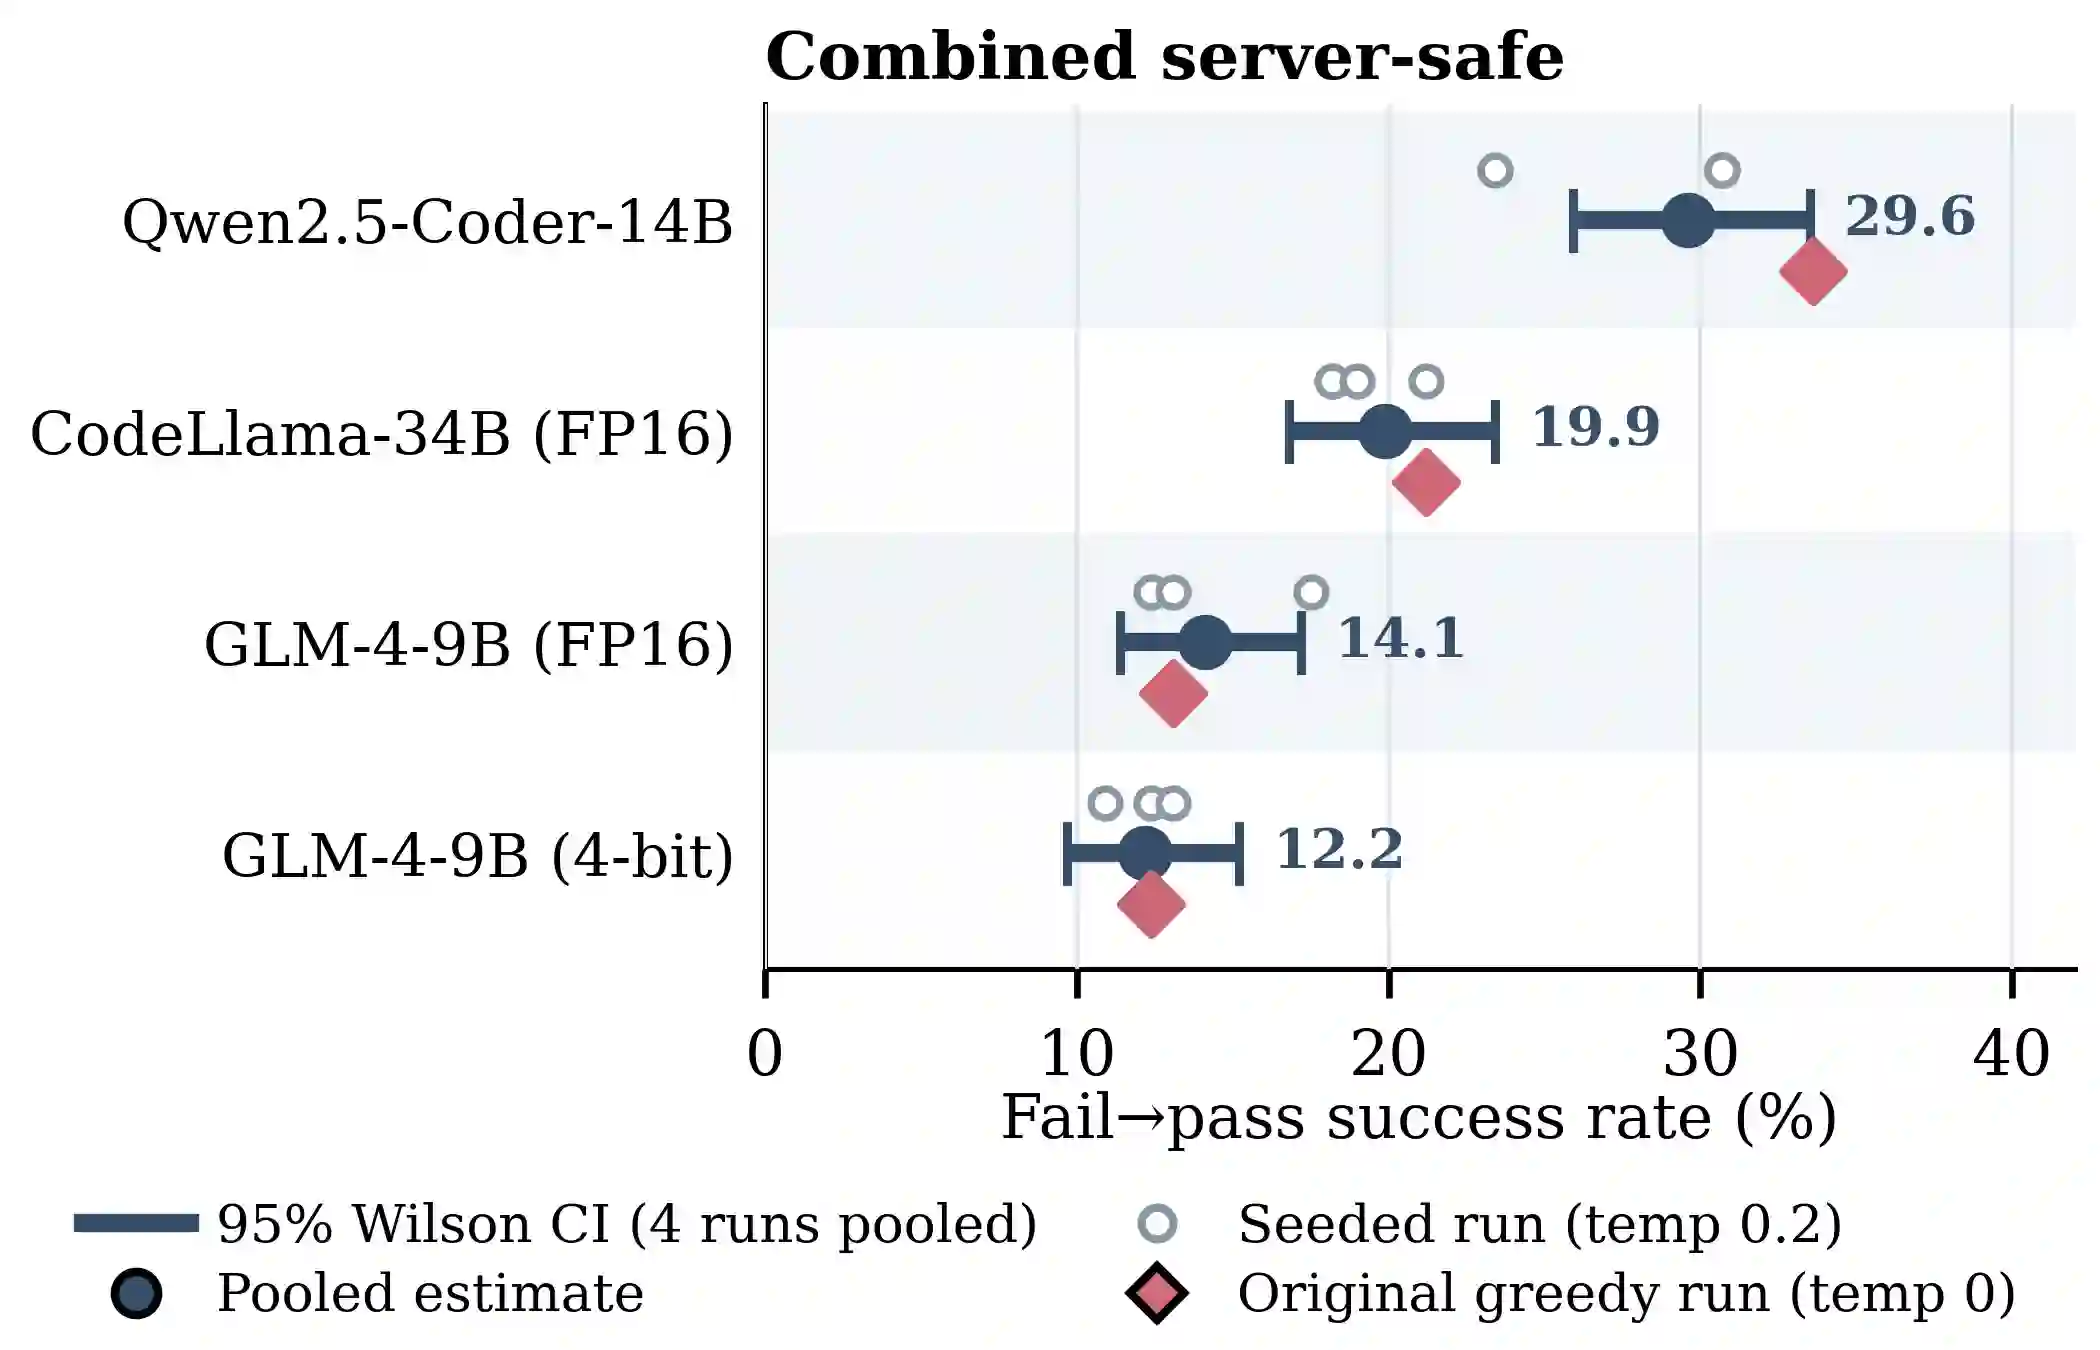
Implementing Security Technical Implementation Guide (STIG) controls remains a demanding operating-system administration task. Each natural-language security requirement must be translated into a precise and persistent configuration change. These changes span Secure Shell (SSH) configuration, authentication policy, audit rules, and kernel parameters. Existing benchmarks do not measure whether a model can perform this task on a live system. Code benchmarks evaluate isolated programs without persistent system state, while agent benchmarks largely focus on applications rather than operating-system configuration. In this paper, we introduce \textbf{HardEval}, an execution-verified benchmark for evaluating language-model-assisted security hardening. HardEval is built from Red Hat Enterprise Linux 8 STIG controls that fail on an unhardened baseline system. Expert-written reference remediations and Open Vulnerability and Assessment Language (OVAL) checks serve as hidden ground truth for grading; they are never shown to the model, and each task states only the required security outcome while withholding the implementation. The model produces a Bash script, which is executed on a live virtual machine and graded from fail to pass using the corresponding OpenSCAP/OVAL compliance check. Evaluation of fourteen frontier and open-weight configurations reveals large and uneven capability differences across security domains. A recurring failure mode is plausible security code that does not satisfy the exact compliance condition. For four open-weight configurations, multi-run Wilson confidence intervals preserve the observed ordering. HardEval is publicly available.
翻译:暂无翻译




相关内容




 微信扫码咨询专知VIP会员